AI

Tutorials

Automating Tag Recommendations with CloudQuery and n8n

Automating Tag Recommendations with CloudQuery and n8n

TL;DR: Learn how to build an AI-powered automation pipeline using n8n that monitors cloud storage buckets for missing resource tags. You’ll build a system that uses an AI agent connected to a PostgreSQL database (populated by CloudQuery), leverages OpenAI's models to analyze bucket names and recommend appropriate tags, then sends Slack notifications with actionable recommendations.

Keeping track of resource tagging is important for cost management, security, and operational efficiency. When tags are missing, it’s quite difficult to find out who owns what and who you should go and shout at when things break (like when a storage bucket is public).

We previously wrote about the CloudQuery MCP server that you can use with Claude to ask questions about your infrastructure. However, that requires your manual input. For this blog post, I have decided to add a bit of automation: I am going to build an AI automation pipeline with an AI Agent that will check the data from my syncs to find buckets with some missing tags, and send me a notification with recommendations.

The goal

I want to make sure that all our storage buckets have three tags:

  • Env (as in “environment”)
  • Owner
  • Service

If a storage bucket is missing one of these tags, I want to know about it. I would also like to receive a recommendation on what the tags should actually be. I am going to use the bucket name and project name to help recommend the tags.

Prerequisites

  1. A basic idea about what LLMs are and how they work.
  2. An account with n8n. They offer a free trial, or you can run the full setup locally (but that complicates the Slack connection a bit). In this blog post, I am going to be using the cloud-hosted n8n service.
  3. OpenAI API key (or if you use another model supported by n8n, then some other API key)
  4. A database accessible from n8n. You can either run one locally and proxy with ngrok, or just use Neon for PostgreSQL.
  5. Finished CloudQuery sync from AWS or GCP to the database. We’ll only need the aws_s3_buckets or gcp_storage_buckets table, respectively. Check out the getting started guide for instructions on how to run a CloudQuery sync.

The automation pipeline

The pipeline consists of a scheduled trigger, an AI agent with access to a model, parser, and a database, a piece of transformation code to help me craft the Slack message, and the actual Slack integration to send the message.

n8n workflow diagram displaying automated tag recommendation pipeline: Schedule Trigger initiates AI Agent (containing Chat Model, Memory, Tool, and Output Parser modules), followed by Code processing and Figma message delivery. PostgreSQL query execution and OpenAI Chat Model connect to the AI Agent via dashed lines, with the Structured Output Parser ensuring formatted results.

The core of the pipeline is the AI Agent, which is essentially a program that observes, thinks, and acts to solve problems automatically based on the context we give it.

The n8n’s AI Agent has several tools and parameters that help build that context.

To start, we’ll create a new workspace in n8n and then add an AI agent component from the drawer on the right. It will add some other things, such as triggers. Let’s remove them for now and focus on the Agent itself.

n8n AI Agent node configuration interface showing three core components: Chat Model (marked with red asterisk), Memory, and Tool, each with add/configure buttons below.

Open the AI agent to modify its configuration by double clicking on it. You’ll see that it has options to configure a prompt, which should sound familiar.
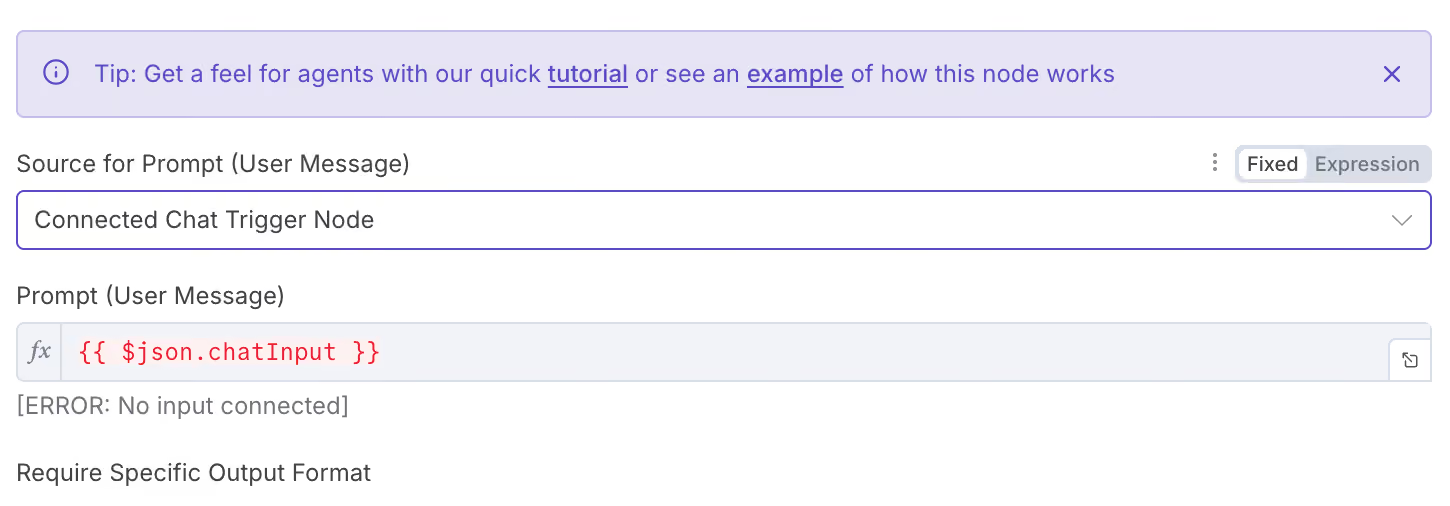
n8n AI Agent configuration interface showing prompt setup with blue information banner at top, dropdown for 'Connected Chat Trigger Node' as message source, expression field containing '{{ $json.chatInput }}' in red text.

Let’s start with the prompt. If the AI Agent was connected to a chat trigger, we could leave the options as they are. But we’re going to use a schedule, so we need to give the agent a tailored user prompt asking it to do stuff.

Switch the “User message” dropdown to “Define below” and then write the prompt in the Prompt box.

Here’s mine:

Analyze storage buckets and their tags. List storage buckets that are missing service, owner, or env tag.

Decide on the individual tags based on the bucket name or similar tags. For example, use the value of the 'environment' tag if it is present but 'env' is empty.

Typical separators in bucket names that separate services, owners, or environments are underscore (_) or hyphen (-).

A typical environment values are test, staging, prod, production.

If you cannot infer any of the tags, leave them empty.

If a service name is unknown, it's likely the GCP project name or AWS account name.

Output a json array with the project names, bucket names, the original tags, and the recommended tags. Return only the json, nothing else.

Example:

[
{
"project":"test",
"bucket":"empty_bucket",
"tags": {
"environment": "test",
"service": "picture-service",
"owner": "unknown"
},
"recommended_tags":{
"environment": "test",
"service": "picture-service",
"owner": "abc"
}
}
]

I am giving the agent a clear task and asking it to produce a specific output (we’ll get to the validation in a bit).

Next, we need a system message. A system message contains the AI's overall instructions, personality, and rules that should apply to every interaction. It’s a good idea to separate this because unlike user prompts, it is meant to stay consistent across conversations. You can reuse this system message with other AI agents you’ll eventually build and only change the prompt.

To add a system message, go down to Options and select Add Option -> System Message.

n8n configuration panel showing Options section with 'No properties' text, expandable 'Add Option' button, and configuration fields for 'System Message' and 'Max Iterations' below.

A good system message should describe the agent’s role, give it instructions, provide guardrails (rules), and optionally some examples. You see that the default system message is “You are a helpful assistant”. We’ll provide a little bit more information.

Here’s my system message for the agent:

# Role
You are a cloud infrastructure engineer's assistant. Your role is to get information about your cloud infrastructure data stored in a PostgreSQL database.

# Instructions
Follow these steps to answer user's questions:
1. Use the `executeQuery` tool to find out what tables you have available in the database and what cloud providers they are from.
2. Find out what tables are relevant to the user's question.
3. Use the `executeQuery` tool to find out the columns for the tables to see what columns are relevant to the user's question.
4. Using the information about tables and columns, write a PostgreSQL query to answer the user's question.
5. Use the `executeQuery` tool to run the query from the previous step and return the result to the user.

# Rules
- If you do not know the answer, do not make it up, just say you don't know how to answer it.
- Do not hallucinate the table or column names.
- Don't make things up, ask the user clarifying question if you need additional information to complete the task. If you are asked a question to which you don't know the answer to, say so.

# Examples
Database tables are always follow the format of [cloud_provider]_[service]_[resource].

gcp_storage_buckets
aws_ec2_instances

Next, we need to give the agent some tools to work with. First, we need to connect it to a language model. Close the AI agent configuration, click the [+] on the Chat Model “pin”, and select the model you want to use with the agent. You will most likely need to add a credential (the API key) to use with the model.
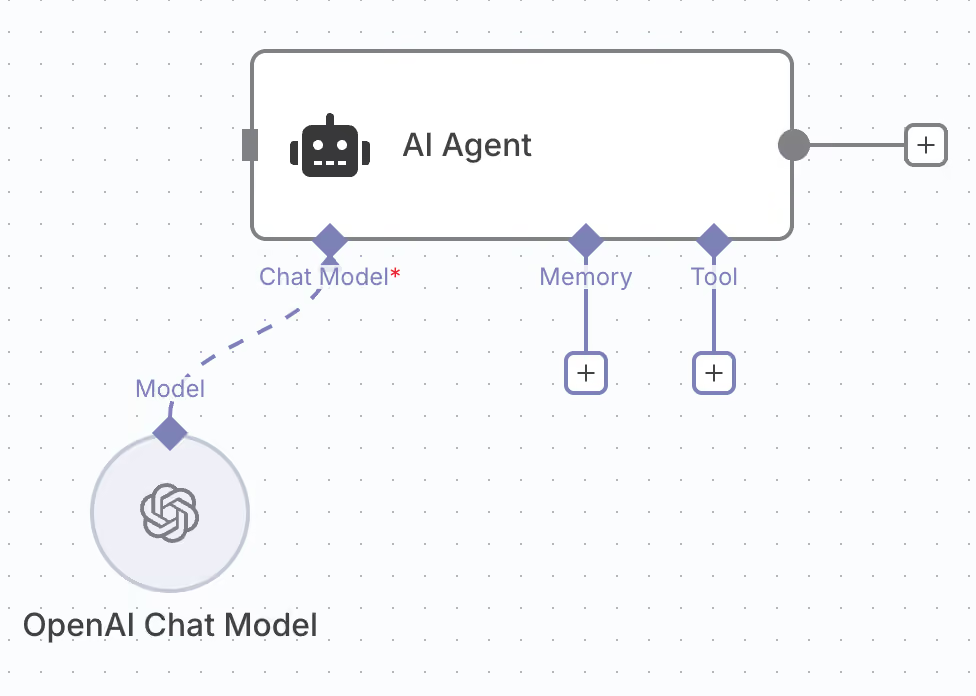
n8n AI Agent workflow view showing main AI Agent node with three components (Chat Model marked with red asterisk, Memory, and Tool), connected via dashed line to OpenAI Chat Model node below. Memory and Tool sections show add buttons for configuration.

Now we need to make sure the agent has access to the database with the data from CloudQuery sync. Click the [+] button on the Tool pin, and add a PostgreSQL tool. Add its credentials (specify the connection parameters for your database), choose to set the description manually, and set it to Execute a SQL query in MySQL. Use ‘sql_query’ parameter to pass the query.

Change the operation to Execute Query and set the value of the query to this expression:

{{ $fromAI('sql_query') }}

We just created a tool for the AI agent to use that tells the agent when to use it and how to use it.
The last thing we need to add is a structured output parser to make sure the agent’s output is validated and consistent. Since we’re planning to massage the output a little bit using a script before sending it to Slack, it’s usually a good idea to make it consistent. If you were to connect another agent to the output of the first one, you’d also want to make sure they have a consistent communication protocol.

Open the AI Agent configuration and set the toggle “Require Specific Output Format” on. This will tell you to add a structured parser. Select the "Structured Output Parser" from the list and make sure it’s connected to the AI agent.

You can let the Parser infer the schema from a sample JSON, or you can use this JSON schema directly:

{
"$schema": "http://json-schema.org/draft-07/schema#",
"type": "array",
"items": {
"type": "object",
"properties": {
"project": {
"type": "string",
"description": "Project identifier"
},
"bucket": {
"type": "string",
"description": "Storage bucket name"
},
"tags": {
"type": "object",
"properties": {
"environment": {
"type": "string"
},
"service": {
"type": "string"
},
"owner": {
"type": "string"
}
},
"required": ["environment", "service", "owner"],
"additionalProperties": true,
"description": "Required tags for the project"
},
"recommended_tags": {
"type": "object",
"properties": {
"environment": {
"type": "string"
},
"service": {
"type": "string"
},
"owner": {
"type": "string"
}
},
"additionalProperties": true,
"description": "Optional recommended tags for the project"
}
},
"required": ["project", "bucket", "tags"],
"additionalProperties": false
}
}

Check the “Auto-fix Format,” which will help make the output more consistent. Finally, we need to connect the Parser to our Chat Model. You can drag from the Parser’s “Model” pin to the existing Model.

n8n AI Agent workflow diagram showing complete component connections: AI Agent node with four parts (Chat Model, Memory, Tool, Output Parser) connected via dashed lines to OpenAI Chat Model, Execute SQL query in Postgres, and Structured Output Parser, respectively.

Almost there!

Click the rightmost pin on the AI agent to connect a new node to its output. Select Code from the drawer.
Paste this short JavaScript code in:

const input = $input.all();
return input[0].json['output'];

What it does is transform the output from the Agent/Parser so it’s sent as individual items to the Slack component, which we will add next.
Click the output pin on the Script and select Slack -> Send a message (you might need to scroll down and expand some sections in the drawer on the right).
Follow the steps required by the Slack credentials to authenticate n8n with Slack.
Then set the Operation to Send, pick a user or channel, and specify the text message. Use Expression, rather than the fixed format.
You can use this message to send all the details:

Bucket tag recommendation:
Project: {{ $json.project }}
Bucket: {{ $json.bucket }}
Current Tags: env:{{ $json.tags.environment }} owner:{{ $json.tags.owner }} service:{{ $json.tags.service }}
Recommended Tags:
env:{{ $json.recommended_tags.environment || "" }}
owner:{{ $json.recommended_tags.owner || ""}}
service:{{ $json.recommended_tags.service }}

The last thing that’s missing is a trigger. Click the + button on the right and add a Schedule trigger. Configure the schedule. You can also use the big orange Execute Workflow button to execute the workflow immediately.
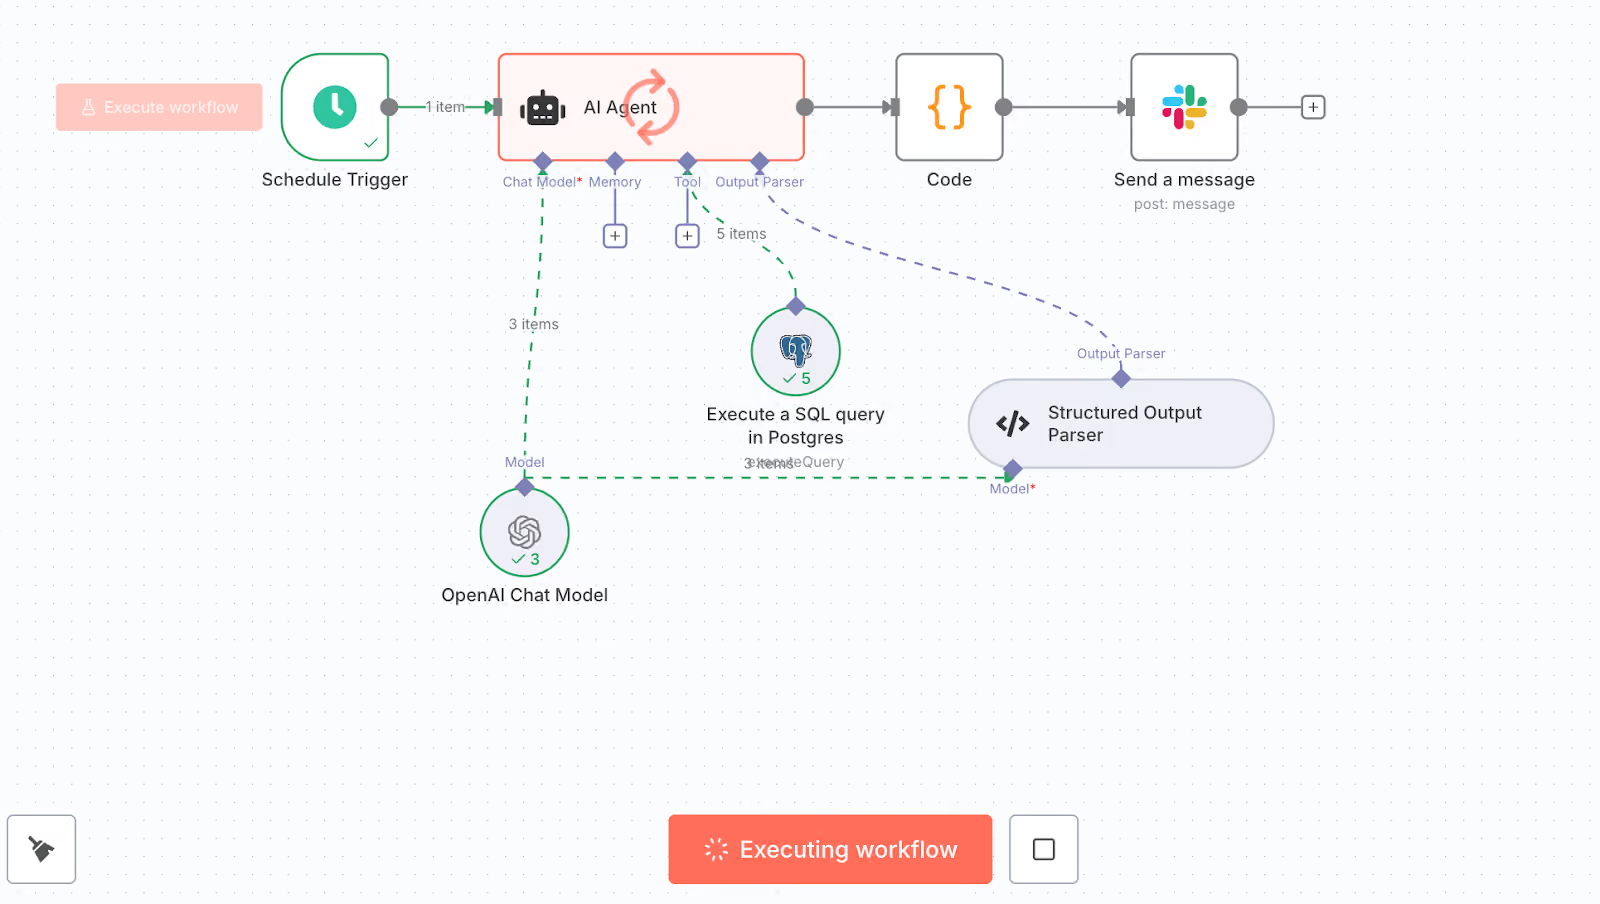
N8N workflow execution view showing completed automation run with green checkmarks: Schedule Trigger (1 item) connects to AI Agent (red border indicating selection), followed by Code and Figma message nodes. Supporting components show item counts - OpenAI Chat Model (3 items), PostgreSQL query (5 items), and Structured Output Parser. Delete workflow button visible in top-left corner.

If everything goes well, you should receive a few Slack messages soon (based on how many untagged buckets there are).

Slack message showing automated tag recommendations for AWS S3 bucket 'cq_michal_platform_test' in project 'cq-playground'. Current tags show empty values for env, owner, and service. AI-recommended tags include 'env', 'owner', and 'service'. Message footer indicates automation via n8n workflow.

Making this better

Experiment with the user prompts and system messages. Give the agent more examples or better structured tasks to perform. You can also connect to the CloudQuery MCP server to give it more tools to better understand your database structure. All you need to do is run CloudQuery MCP as a streamable HTTP server and connect the AI agent to it.

Summary

You know what's interesting about this automation? We're not just identifying problems anymore. We're providing solutions based on the actual patterns in your infrastructure. This AI agent looks at bucket names like prod_analytics_team and figures out the tags should probably be env, service, owner.
The real magic happens in how modular this whole thing is. We could swap out the storage bucket logic for EC2 instances tomorrow. Or add approval workflows. The data from CloudQuery gives us a consistent data foundation, and the structured output means everything plays nicely with whatever comes next in your toolchain.
Here’s what I’m most excited about: this pattern works for way more than just tagging. Security configurations? Same approach. Cost anomalies? Yep. Architectural drift? Absolutely. We've basically built a template for turning any compliance headache into automated monitoring that actually understands your environment's quirks.
Ready to build your own? Start with syncing your data with CloudQuery, then set up your n8n pipeline and start experimenting. The combination opens up so many possibilities for intelligent cloud operations that we're still discovering new use cases every week (In fact, we would love to hear what you built over on the CloudQuery Community Forum).

Try CloudQuery yourself

Self-hosted, open source, and free to start. Or schedule a demo to see the managed version.
Related posts

AI

Engineering

Tutorials

Scale GitHub Issues semantic search with CloudQuery, BigQuery, and Vertex AI

Sync GitHub issues to BigQuery with CloudQuery, generate Vertex AI embeddings via BigQuery remote models, and power fast, fully managed semantic search.

Mariano Gappa

Mariano Gappa

October 9, 2025

AI

Engineering

Tutorials

Improve GitHub Issues search effortlessly with CloudQuery, pgvector and OpenAI

Turn GitHub issues into instant insights by syncing with CloudQuery, generating pgvector embeddings in PostgreSQL, and querying with natural language.

Mariano Gappa

Mariano Gappa

October 1, 2025

AI

Security

Tutorials

Building Secure AI-Powered Cloud Security: From Data Pipeline to Risk Detection

Learn how AI-powered cloud security reduces investigation time by 55% across AWS, GCP, Azure with our open-source demo.

Joe Karlsson

Joe Karlsson

September 17, 2025

AI

Cloud Asset Inventory

Product News

CloudQuery Platform Adds Business Context and Scheduled Exports to Cloud Inventory

CloudQuery Platform now groups cloud resources into apps and environments, and lets you schedule automated data exports to your data warehouse on a cron.

Zeen Rachidi

Zeen Rachidi

August 31, 2026

AI

Product News

What's new in the CloudQuery Platform AI Assistant

The CloudQuery Platform AI Assistant just got a major upgrade enabling you to build reports from chat, revisit past conversations, manage policies conversationally, and more.

Zeen Rachidi

Zeen Rachidi

July 16, 2026

AI

Product News

Try CloudQuery Platform Today: Self-Service Signup Is Here

CloudQuery's Platform now offers self-service signup

Zeen Rachidi

Zeen Rachidi

June 18, 2026

Tutorials

How to Automatically Update CloudQuery Integrations with Renovate

Configure Renovate to automatically update CloudQuery integration versions in your YAML files using the CloudQuery Hub API as a custom datasource.

Matthew M

Matthew M

May 20, 2026

AI

Product News

Introducing the CloudQuery Platform AI Assistant

CloudQuery's new AI Assistant lets you ask questions about your cloud infrastructure in plain English - no SQL required.

Joe Karlsson

Joe Karlsson

May 18, 2026

AWS

Security

Tutorials

Finding AWS Unrestricted Outbound Access in 2026: EC2, Lambda, and Beyond

Find EC2, Lambda, and ECS Fargate resources with unrestricted outbound access in AWS using SQL. Why egress controls still break attack chains in 2026.

Joe Karlsson

Joe Karlsson

May 5, 2026

Own your pipeline.
Own your data.