How can you replace a traditional CMDB for large cloud infrastructure environments and save time and money? Let's look at the new architecture we call the "Infrastructure Lake".

In this blog (with a bit of click bait title, sorry), I would like to take you on a tour of Configuration Management Databases, or CMDBs, for short. We will cover what they are, their history, why you would need one and an alternative modern architecture that solves the same problems, but in a more scalable and customizable way.
History
CMDBs first appeared sometime around 2005: 19 years ago at the time of writing, and a year before the first release of AWS S3.
A CMDB, even though it contains a database, is actually much more than just a database. Rather, it is a full-blown application that stores the configuration of your IT infrastructure: both hardware and software. If it helps, think CRM, but for IT. Some popular services that solve this use case include ServiceNow and Jira.
Let’s take a look at a high-level architecture of a common CMDB:

A typical CMDB application combines a few key components:
The core is the database, or sometimes multiple databases. However, this layer is usually not exposed to the end user.
It then bundles several applications on top of the database: a Service Catalog, Incident Management, and an Orchestration & Workflow application.
In the early days of CMDB, entries were manually inserted and deleted when a new computer was purchased, or a new rack was added to the company database. Jira and ServiceNow were the perfect fit for such tasks, as you can create your own programmable table via the CMDB interface, insert and edit records via the built-in UI, or ingest the info from CSV or API, and then create various reports and automations on top.
Infrastructure Lake
Fast forward to 2024: assets have grown exponentially, especially cloud assets. Furthermore, most systems are now queryable via APIs. In addition, other tools like databases, data lakes, and data warehouses saw a huge advancement, along with standalone BI tools, incident management tools, and orchestration applications.
In an environment where assets are automated and you have millions of them in a highly dynamic environment where those assets also update every minute cost and performance will start to become a real problem in an old architecture (think about syncing hundreds of millions of resources from thousands of AWS accounts on an hourly basis to Jira or to Google Spreadsheet - that would not end working well).
A new alternative to classic CMDB tools has emerged: one which takes an unbundled approach and resembles the modern data stack. It uses the best-in-class tools and is cheaper, faster, and more customizable.
Enter the “Infrastructure Lake”:
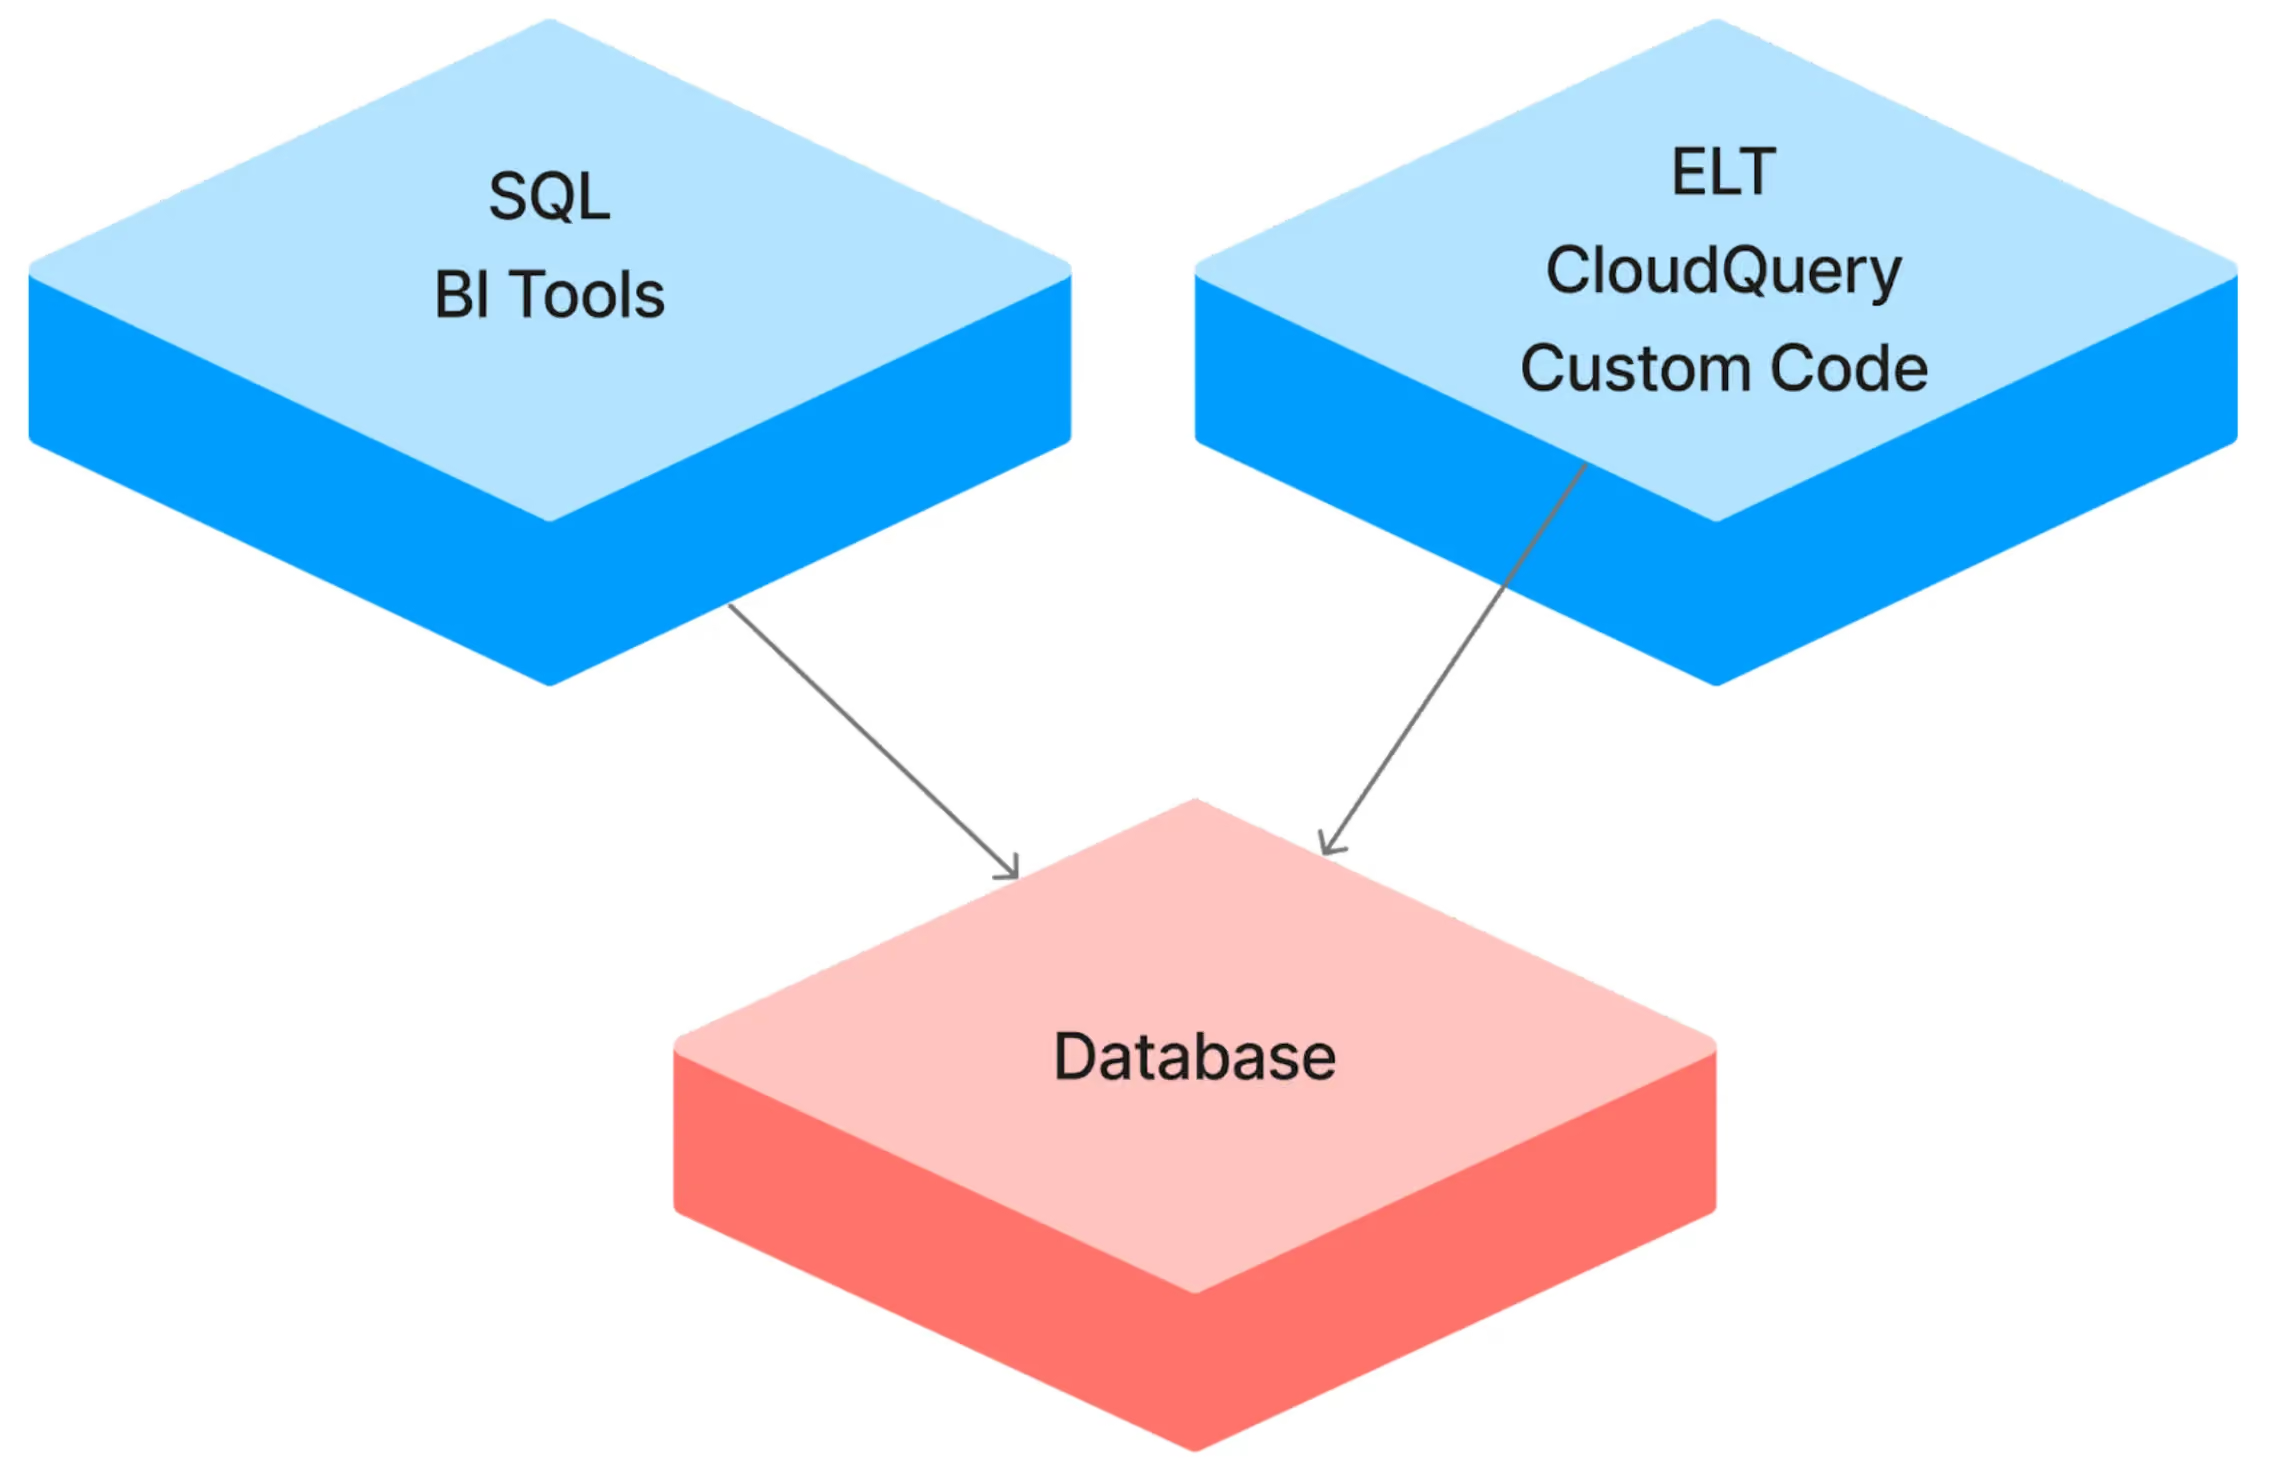
In this architecture, we use any database that scales to our needs and that potentially we already have in our stack - whether it is a vanilla PostgreSQL database, one running in the cloud (like RDS, CloudSQL, or AzureSQL), a data lake (Athena, Databricks) or a data warehouse (BigQuery, ClickHouse, MotherDuck, Snowflake).
We ingest the data via any ELT (Extract, Load, Transform) tool - in this case CloudQuery. This supports connectors for all the major cloud providers, whether you're looking to build a CMDB for AWS or want to include data from other platforms such as GCP, Azure or other applications, and extracts the configuration out of cloud environments at scale.
Once we ingest the data, it is immediately available upstream. Users can directly connect to it, or access it via a BI tool using a standard query language (SQL).
What do you gain?
- Price: This will be significantly cheaper. We remove a full-stack application ingesting millions of records that was not initially built for such scale, both in terms of architecture and in terms of pricing. Modern managed databases, data lakes, and data warehouses are great at ingesting these volumes of data at scale without becoming prohibitively expensive.
- Flexibility: by having raw access to the database, we have maximum flexibility and can reuse a wide range of tools that are already available in our stack. We can use our favorite dashboard solution. We can use
dbtto create models and drive new insights. For simple automation, we can use code–or even lambda functions–to do anything else that we want to connect or act upon, depending on what changed in our “infrastructure lake”.
Does it mean you do not need a CMDB anymore?
This depends on what you were using it for. If your ticketing system is there and you have other uses, you do not need to remove it. In fact, you can actually connect the infrastructure lake to the CMDB, whether through code or via one of the database integrations, to facilitate a smooth transition and give users a single pane of glass for all assets.
Summary
In this blog, we went over a new architecture we call the Infrastructure Lake that can extend or replace a traditional CMDB for large cloud infrastructure environments. It uses standard data tools leading to a more customizable, faster, and cheaper solution. If you want to find out more, check out our other resources.
Want to see CloudQuery in action? Schedule a demo with our team or check out the platform documentation to learn more.
Want help getting started? Join the CloudQuery community to connect with other users and experts, or message our team directly here if you have any questions.
Written by
Try CloudQuery yourself
Self-hosted, open source, and free to start. Or schedule a demo to see the managed version.