Configuring Workload identity federation between GCP and AWS EKS
Workload identity federation is the process of impersonating an identity in one cloud provider from the other without long lived keys. In this blog post we will walk through how to setup federation between a workload running on AWS EKS (In this case CloudQuery so you can also fetch configuration from your GCP accounts) to GCP.
Step 1: Create AWS Infrastructure for CloudQuery on EKS
In this guide, we run CloudQuery on AWS EKS with the official CloudQuery Helm Charts.
IAM Roles for CloudQuery on EKS
For EKS, IAM setup may require an Amazon EKS cluster IAM role and an Amazon EKS node IAM role. Refer to AWS documentation for more information on IAM setup and best practices for securing IAM for EKS Clusters.
Step 2: Enable Additional GCP Services
The Security Token Service API and the IAM Service Account Credentials API need to be enabled in our GCP project.
Step 3: Create GCP Service Account
Now we need to create the GCP Service Account which CloudQuery will authenticate with in order to fetch the GCP resources.
We need to ensure that the new Service Account has the appropriate permissions to view the desired projects in GCP.
Step 4: Create GCP Workload Identity Pool
Next, we need to create the GCP Workload Identity Pool.
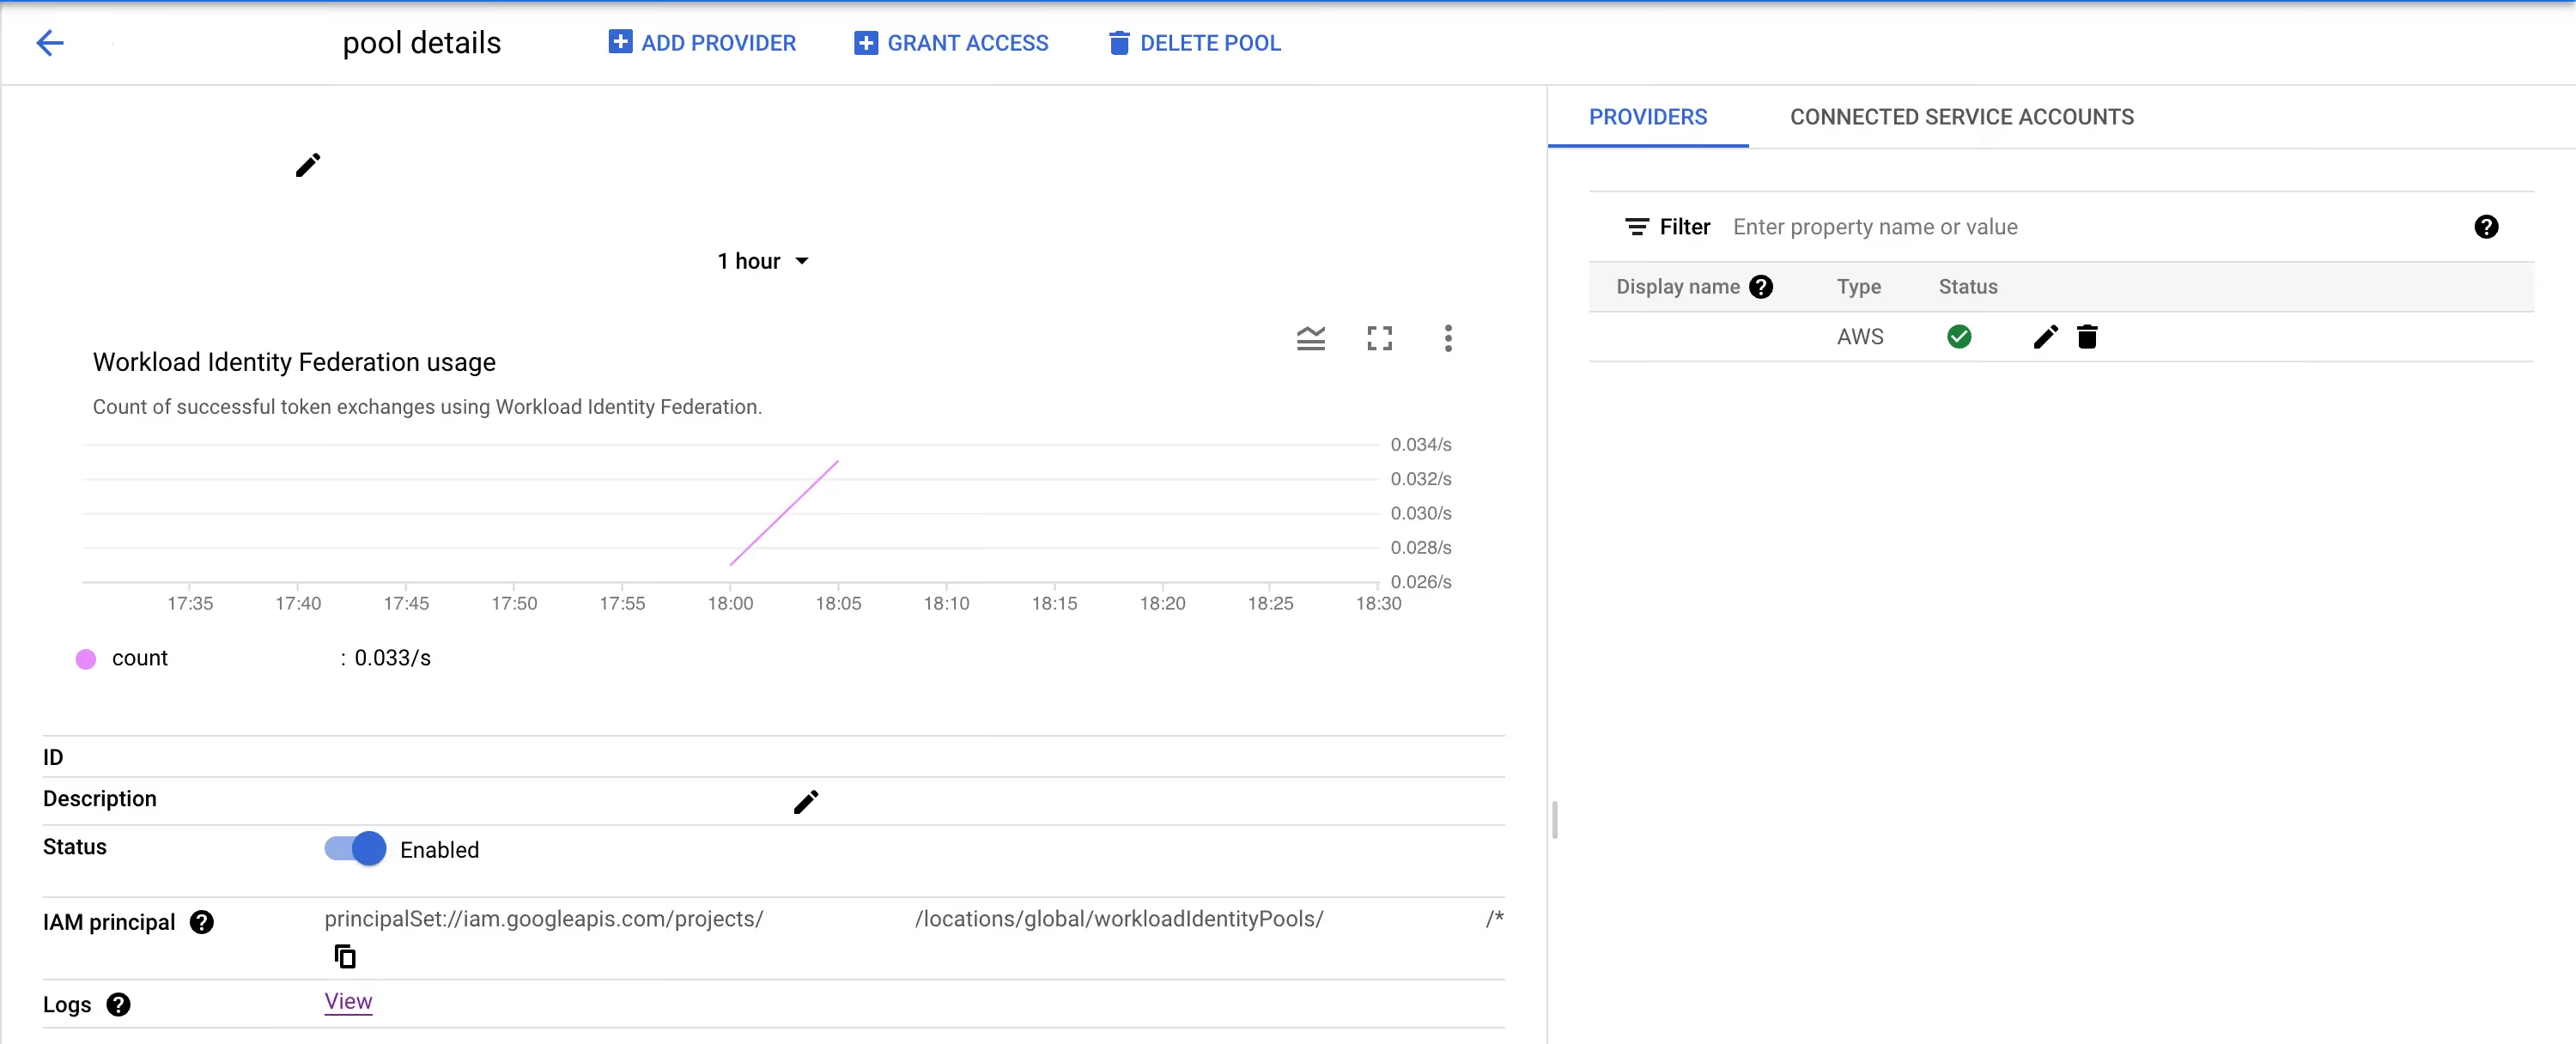
Step 5: Create Workload Identity Provider
After creating the GCP Workload Identity Pool we need to create the Workload Identity Provider. This example does not cover how to harden the Identity Provider, which can be achieved by passing the --attribute-condition flag.

Step 6: Bind GCP Service Account Impersonation
Now, we will create an IAM policy binding.
The below command allows all identities from our pool to impersonate the GCP Service Account we created earlier by binding the IAM role roles/iam.workloadIdentityUser to the GCP service account. Replace the number in the -member flag with the GCP project number.
Please consider adjusting the -member flag for additional security with GCP service account impersonation. More granular options include options such as a single identity, all identities in a group, or all identities with a specific attribute value. More information can be found in the Service account impersonation section of Google Cloud Docs. We recommend using granular scoping for service account impersonation.
An example of using a single identity in the pool could look like the following command. Additional configuration may be required for attribute mapping and conditions. Information on defining attribute mapping can be found here.
Step 7: Download Client library Config
The Client library Config needs to be downloaded, this can be achieved by navigating to the Workload Identity Pool and selecting the CONNECTED SERVICE ACCOUNTS Tab on the right side. The Client library Config can be obtained from there. The file does NOT contain sensitive information.
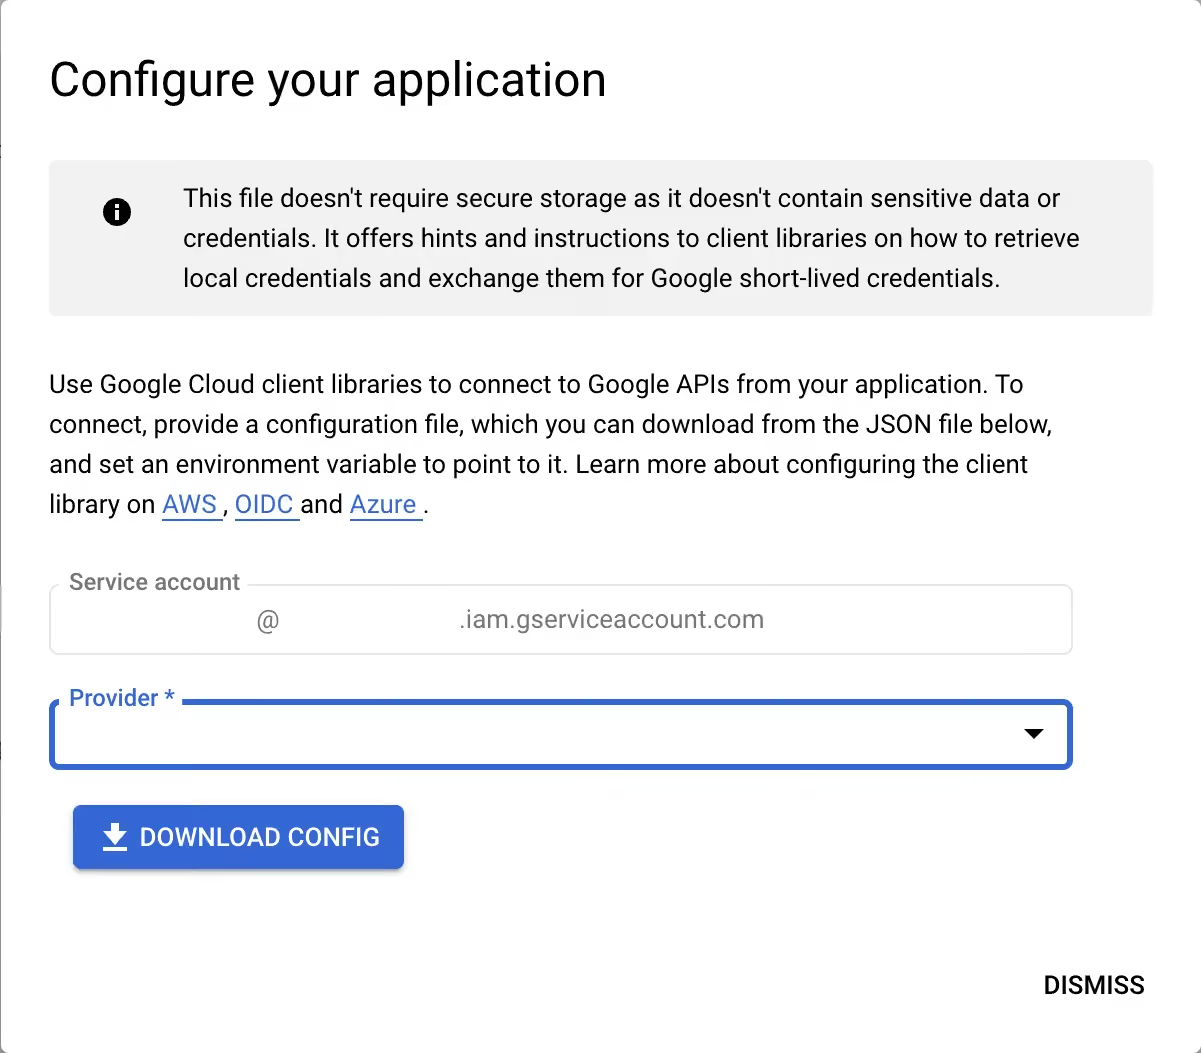
Step 8: Configure CloudQuery
The downloaded Client library config needs to be uploaded to our Kubernetes as a config map.
Now we just need to inject the Client library config into our Pod with the help of a volume mount. This can be achieved by adding those values into the values.yaml of the Helm Chart.
Conclusion
That’s it! Now you can ingest your configuration across clouds into a single PostgreSQL database, visualise with your favourite BI tool and build your own asset inventory, CSPM, search and any other use-case you have in mind!
Want to see CloudQuery in action? Schedule a demo with our team or check out the platform documentation to learn more.
Want help getting started? Join the CloudQuery community to connect with other users and experts, or message our team directly here if you have any questions.
Written by
Try CloudQuery yourself
Self-hosted, open source, and free to start. Or schedule a demo to see the managed version.