CloudQuery is an efficient standalone tool for creating solutions that rely on moving data, but for teams who already have an ELT stack implementation in place, it’s even easier to integrate CloudQuery into your existing stack. Last week, we published a blog showing how to use CloudQuery for teams working with Airflow. Today, we’ll explore how to do the same for teams working with Argo Workflows.
As with our tutorial on using Apache Airflow with CloudQuery, we’ll provide you with a recipe for running an Argo Workflow to sync all xkcd comics into a local MongoDB database. We chose the xkcd comics because they don’t require any extra technology-specific configuration, and it costs you nothing to sync. Still, the steps outlined below are similar for any of CloudQuery's other sources and destinations.
Setting up your Argo Workflow
To get started with Argo Workflows, follow their Quick Start guide for the most up-to-date methods. Be sure that you have installed the argo CLI tool.
Setting up MongoDB
For this example, we can try the free Community version by following the steps here.
Make sure to have the MongoDB server listening on localhost:27017. We’ll sync data to it from the workflow’s container by using the special hostname host.docker.internal.
How to configure CloudQuery
Setting up the configuration file that CloudQuery uses when syncing requires minimal configuration. The basics of this file are telling CloudQuery what to sync from and where to sync that data to, i.e., sources and destinations. Let’s specify this first.
Create a file called cloudquery-source.yml with these contents. Information on how to configure each CloudQuery Plugin can be found on the Plugin page
This specification will tell the CloudQuery CLI:
- To use the xkcd source integration with version v1.0.6 from the CloudQuery Hub as source.
- To sync all available source tables.
- To sync them to a “MongoDB” destination, which will be specified on a separate YAML file.
- Apply the ConfigMap with
kubectl apply -n argo -f cloudquery-source.yml - Add a file called
cloudquery-destination.ymlwith these contents
This specification will tell the CloudQuery CLI:
- To use the MongoDB destination integration with version v2.5.6 from the CloudQuery Hub as the destination.
- To connect to MongoDB via the host’s special hostname, and store the data onto a database called
xkcd.
- Apply the ConfigMap with
kubectl apply -n argo -f cloudquery-destination.yml
How to authenticate to CloudQuery with an API key
The CloudQuery CLI needs to be logged in to download the source and destination integrations. Since this is a non-interactive workflow, let’s create an API key.
- Follow these steps to generate a CloudQuery API key: Generate API key
- Create a Secret with the API key
- Apply the secret with
kubectl apply -n argo -f cloudquery-apikey.yml
(Note that the secret is Opaque, so remember to base64 the API key)
How to run CloudQuery within an Argo Workflow
At this point, all the resources needed to implement the workflow are done.
The finalized workflow looks like this:
The above workflow will do the following when run:
- Hook up the source & destination ConfigMaps and the Secret we previously defined.
- Start up a CloudQuery docker image.
- Run the CloudQuery sync, which will send the xkcd comics to MongoDB.
To view the Argo Workflows UI, first port forward the server:
If we open localhost:2746 in the browser, you can see the Workflows UI with no workflows created yet.
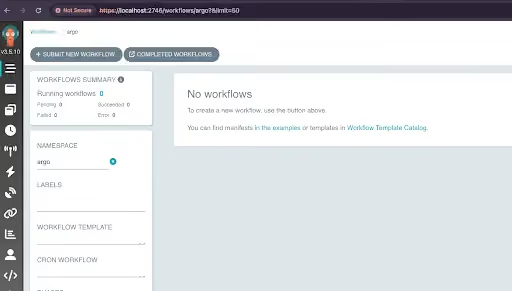
Make sure you’re looking at the argo namespace. Visit /workflows/argo.
Running CloudQuery within the Argo Workflow
At this point, you need to submit the workflow from the terminal by using the argo CLI:
You can see that the workflow is immediately created:
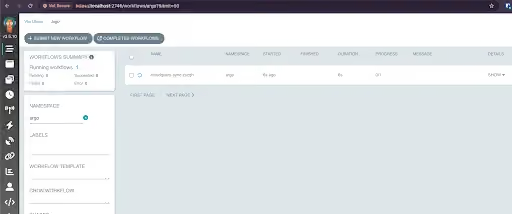
Upon entering the workflow, you can see it’s running. Feel free to inspect the logs to see how it downloads the plugins and runs the sync.
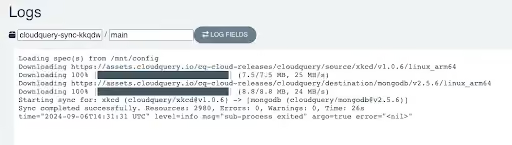
When the sync completes, we’re ready to go to MongoDB and check the resulting database.
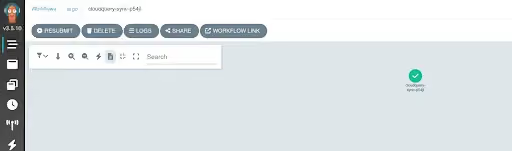
The final result
You can then use mongosh to inspect the newly created xkcd database in your host computer:
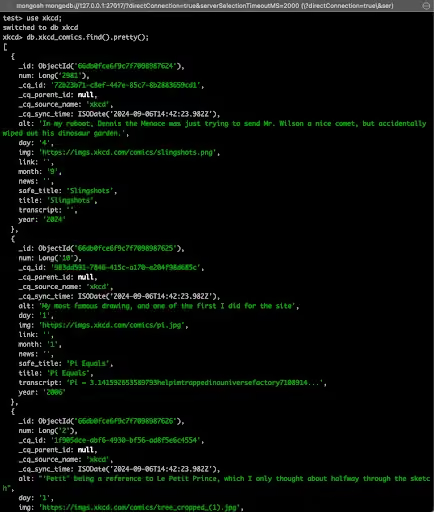
In this blog post, we’ve implemented an Argo Workflow that runs a CloudQuery sync, downloading the complete history of xkcd comics to a local MongoDB database.
With this knowledge, you can now:
- Explore our extensive collection of integrations (https://www.cloudquery.io/hub/plugins/source).
- Find the right integration for the technology stack your team works with.
- Simplify your ELT implementations by integrating CloudQuery syncs into your existing Argo Workflows.
If you’re ready to try using CloudQuery in your Argo workflow, you can start by downloading CloudQuery or checking our docs.
Want help getting started? Join the CloudQuery community to connect with other users and experts, or message our team directly here if you have any questions.
Written by
Try CloudQuery yourself
Self-hosted, open source, and free to start. Or schedule a demo to see the managed version.