TL;DR: If you're running CloudQuery ELT jobs on separate infrastructure like Kubernetes or Airflow while storing data in Snowflake, you're managing unnecessary complexity and data movement overhead. Snowpark Container Service lets you run CloudQuery directly inside your Snowflake account, eliminating the infrastructure gap between extraction and storage while leveraging the same compute scaling you already use for analytics. This tutorial shows you how to sync data from 60+ sources directly into Snowflake tables without external dependencies, reducing operational overhead and network latency. By the end of this post, you'll have a unified data platform where ELT workloads execute adjacent to your warehouse instead of shuttling data across separate systems.
Due to CloudQuery’s standalone architecture, it is straightforward to run CloudQuery in any other container service or even inside your Airflow or any other orchestrator. Snowpark Container Service has its own advantages, especially if you are a heavy Snowflake user or have special data requirements where you want your ELT workloads to run near your data warehouse.
Permissions to create databases and warehouses in Snowflake
Caveats:
Snowpark is GA, but some features are not available on all clouds (this tutorial was tested on Snowflake AWS)
Run the following in a Snowflake Worksheet to create the database, warehouse, and compute pool where the CloudQuery job will be executed (You can also reuse an existing setup once):
USE ROLE ACCOUNTADMIN;

CREATE ROLE IF NOT EXISTS cq_role;

CREATE DATABASE IF NOT EXISTS cq_db;
GRANT OWNERSHIP ON DATABASE cq_db TO ROLE cq_role COPY CURRENT GRANTS;

CREATE OR REPLACE WAREHOUSE cq_warehouse WITH
 WAREHOUSE_SIZE='X-SMALL';
GRANT USAGE ON WAREHOUSE cq_warehouse TO ROLE cq_role;

GRANT BIND SERVICE ENDPOINT ON ACCOUNT TO ROLE cq_role;

CREATE COMPUTE POOL cq_compute_pool
 MIN_NODES = 1
 MAX_NODES = 1
 INSTANCE_FAMILY = CPU_X64_XS;
GRANT USAGE, MONITOR ON COMPUTE POOL cq_compute_pool TO ROLE cq_role;

GRANT ROLE cq_role TO USER
Create the following repository where you will push the CloudQuery Docker and the stage where you can put the CloudQuery config files to run different ELT (sync) jobs (You can also reuse repositories and stages if you already have those).
USE ROLE cq_role;
USE DATABASE cq_db;
USE WAREHOUSE cq_warehouse;

CREATE SCHEMA IF NOT EXISTS cq_schema;
USE SCHEMA cq_schema;
CREATE IMAGE REPOSITORY IF NOT EXISTS cq_repository;
CREATE STAGE IF NOT EXISTS cq_stage
 ENCRYPTION = ( TYPE = 'SNOWFLAKE_SSE')
 DIRECTORY = ( ENABLE = true );
Upload CloudQuery Docker
You will only need to perform the following step once, as Snowflake Container Service doesn’t yet support running public Docker. Therefore, you will need to download and then push the CloudQuery Docker to the Snowflake repository. You may want to upload a new Docker when a new version of CloudQuery CLI is released, but the integrations version is downloaded at runtime and can be updated via configuration.
# Update the version after a new snowflake is released docker pull ghcr.io/cloudquery/cloudquery:6.21-linux-amd64
# Authenticate with the snowflake docker repository # This is only possible if the administrator enables username/password login otherwise use the snowspcs command in the following line docker login .registry.snowflakecomputing.com/cq_db/cq_schema/cq_repository -u
# Use it if the previuos one didn't work snow spcs image-registry login --account --user --mfa-passcode
# will prompt you for a password (You should have multi factor auth enabled) docker tag ghcr.io/cloudquery/cloudquery:6.21-linux-amd64 .registry.snowflakecomputing.com/cq_db/cq_schema/cq_repository/cloudquery:6.21
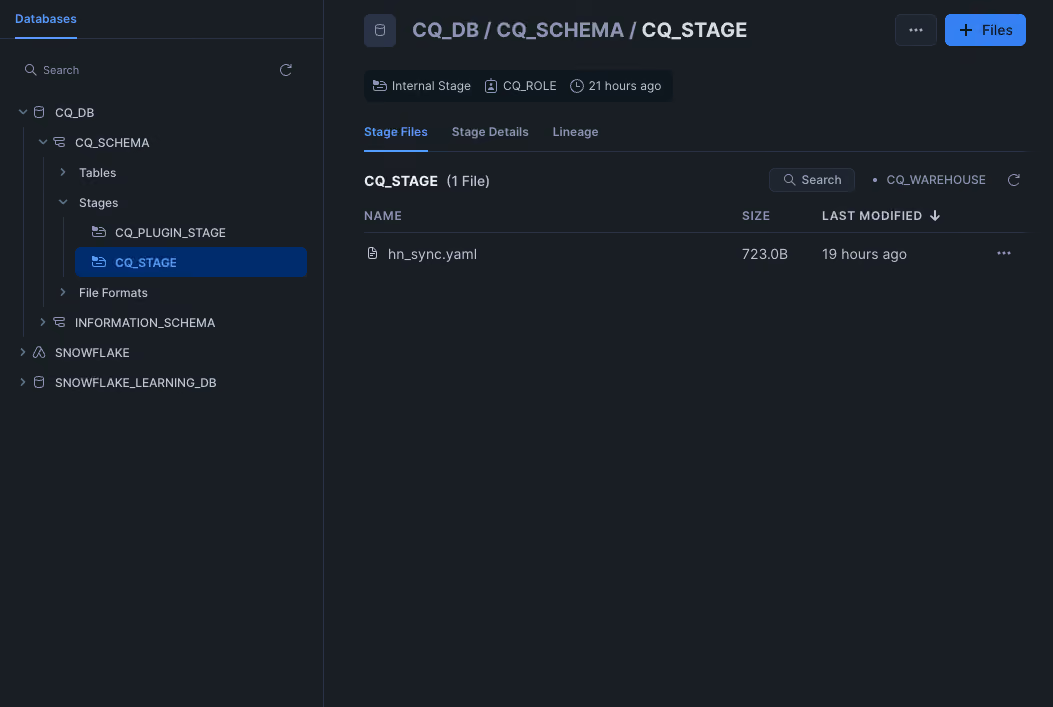
Next, you’ll need to upload the CloudQuery config. This will make it easy to mount the different configs required for the CloudQuery job to run.
You can easily do that via the UI by going to the stage and pressing “Add File”.
The config file in this tutorial looks like this:
kind: source
spec:
  name: 'hackernews'
  path: 'cloudquery/hackernews'
  registry: 'cloudquery'
  version: 'v3.10.0'
  tables: ['*']
  destinations:
    - 'snowflake'
  # Learn more about the configuration options at https://cql.ink/hackernews_source
  spec:
    item_concurrency: 100
    start_time: '2025-06-28T00:00:00Z'
---
kind: destination
spec:
  name: snowflake
  path: cloudquery/snowflake
  version: 'v5.2.14'
  write_mode: 'append'
  # Learn more about the configuration options at https://cql.ink/snowflake_destination
  spec:
    connection_string: '${SNOWFLAKE_HOST}/${SNOWFLAKE_DATABASE}/${SNOWFLAKE_SCHEMA}?warehouse=${SNOWFLAKE_WAREHOUSE}&authenticator=oauth&token=token'
Running CloudQuery
Execute the following from a CloudQuery worksheet:
By default, jobs don't have access to the internet, so you need to configure EGRESS. In this example, I’m configuring EGRESS to have access to all IPs, but in production, you might want to scope this down to *.[cloudquery.io](https://cloudquery.io) and the APIs that CloudQuery integrations interact with to perform the extraction of data.
-- this needs to run from accountadmin
use database cq_db;
use schema public;
CREATE OR REPLACE NETWORK RULE allow_all_egress_rule
 MODE = EGRESS
 TYPE = HOST_PORT
 VALUE_LIST = ('0.0.0.0:80', '0.0.0.0:443');

CREATE EXTERNAL ACCESS INTEGRATION cloudquery_access_integration
 ALLOWED_NETWORK_RULES = (allow_all_egress_rule)
 ENABLED = true;
GRANT USAGE ON INTEGRATION cloudquery_access_integration TO ROLE cq_role;
use schema cq_schema;
Now you are finally ready to run the job!
EXECUTE JOB SERVICE
 IN COMPUTE POOL cq_compute_pool
 NAME=cq_sync
 EXTERNAL_ACCESS_INTEGRATIONS = (cloudquery_access_integration)
 FROM SPECIFICATION $$
 spec:
   container:
   - name: main
     image: /cq_db/cq_schema/cq_repository/cloudquery:6.22
     env:
       SNOWFLAKE_WAREHOUSE: cq_warehouse
       CLOUDQUERY_API_KEY: ****
     volumeMounts:
       - name: configs
         mountPath: /tmp/configs
     args:
       - "sync"
       - "--log-console"
       - "/tmp/configs/hn_sync.yaml"
   volumes:
     - name: configs
       source: "@cq_stage"
 $$
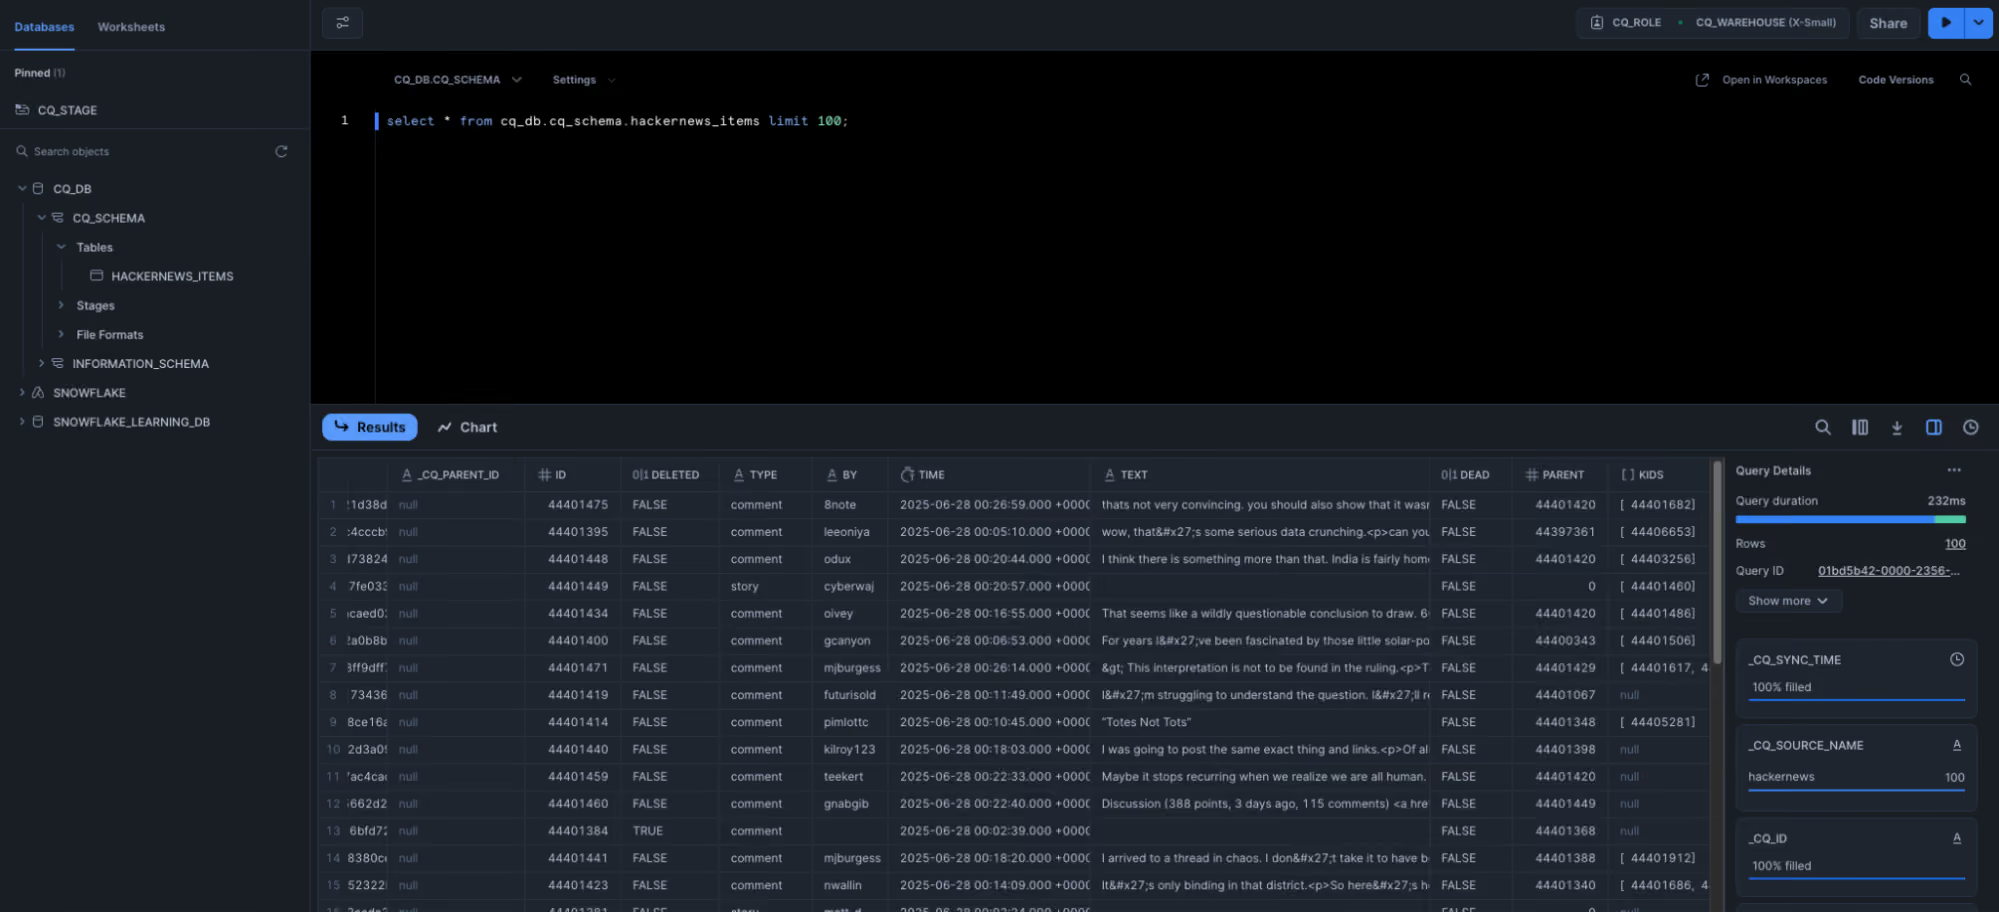
That’s it! Now you should be able to query HackerNews comments in your Snowflake database!
If you need to sync data from 60+ sources, check out CloudQuery Hub, or if you need to write a custom plugin, take a look at our developer guide!
Written by
Yevgeny Pats
Yevgeny Pats is the Co-Founder & CEO at CloudQuery. Prior to establishing CloudQuery, he successfully founded and exited other startups. He has a background in software engineering and cybersecurity.
Try CloudQuery yourself
Self-hosted, open source, and free to start. Or schedule a demo to see the managed version.
Download →
Schedule a demo →
Related posts
Tutorials
How to Automatically Update CloudQuery Integrations with Renovate
Configure Renovate to automatically update CloudQuery integration versions in your YAML files using the CloudQuery Hub API as a custom datasource.
Matthew M
May 20, 2026
AWS
Security
Tutorials
Finding AWS Unrestricted Outbound Access in 2026: EC2, Lambda, and Beyond
Find EC2, Lambda, and ECS Fargate resources with unrestricted outbound access in AWS using SQL. Why egress controls still break attack chains in 2026.
Joe Karlsson
May 5, 2026
AWS
Security
Tutorials
AWS IAM Identity Center with Google Workspace as an IdP: 2026 Step-by-Step Guide
Set up AWS IAM Identity Center with Google Workspace: SAML authentication, SCIM user provisioning, and group sync with CLI or ssosync. Updated for 2026.
Joe Karlsson
May 5, 2026
GCP
Security
Tutorials
Creating Cross-Project Service Accounts in GCP (Console + gcloud CLI)
Create a GCP service account that reads across all your projects with one credential. Covers gcloud CLI, org-level vs.
Joe Karlsson
May 5, 2026
AWS
Cloud Infrastructure
Security
Tutorials
Integrate AbuseIPDB Threat Intelligence with CloudQuery
Enrich your cloud asset inventory with AbuseIPDB threat intelligence to identify public cloud IPs with known abuse reports.
Joe Karlsson
April 20, 2026
AWS
Cloud Infrastructure
Tutorials
How to Query ipinfo.io Data with CloudQuery
Learn how to enrich your cloud asset inventory with ipinfo.io IP geolocation and threat intelligence data using CloudQuery.
Joe Karlsson
April 20, 2026
AWS
Security
Tutorials
AWS IAM Identity Center (Formerly AWS SSO): The Complete 2026 Guide
AWS IAM Identity Center replaced AWS SSO in 2022. Learn how to set it up, configure permission sets, use the AWS CLI, and audit access with CloudQuery.
Joe Karlsson
April 6, 2026
AWS
Tutorials
AWS Pinpoint Is Being Deprecated: How to Assess Your Migration Scope
AWS Pinpoint reaches end of support October 2026. Query your Pinpoint usage across all accounts to find what needs migrating before the deadline.
Joe Karlsson
March 24, 2026
Tutorials
Moving Data from PostgreSQL to MotherDuck
How to sync PostgreSQL data to MotherDuck using CloudQuery, with both one-off batch and continuous CDC streaming options for serverless analytics.