Keeping track of your AWS resource capacity is crucial for maintaining optimal performance and cost-efficiency. DynamoDB, Elastic Compute Cloud (EC2), Elastic Block Store (EBS) volumes, and Lambda functions in AWS frequently undergo significant changes that affect performance and costs. This is where CloudQuery comes in handy. CloudQuery allows you to sync and query your AWS cloud assets with SQL, providing a simple and flexible way to track changes to your AWS resources and manage your cloud infrastructure effectively.
To get started, download the CloudQuery CLI and set up your CloudQuery configuration file by following the AWS Source Integration documentation. When writing your CloudQuery AWS configuration file, make sure that you add aws_dynamodb_tables, aws_ec2_ebs_volumes, and aws_lambda_functions to the list of tables being synced.
If you want to track historical usage trends of your AWS resources, be sure that you sync your resources in append mode in your database for at least 30 days to gather sufficient data and derive meaningful insights. By consistently monitoring these metrics, you can proactively manage your cloud infrastructure, optimize resource allocation, and ensure your applications run smoothly without unexpected interruptions.
How to Track Capacity Changes Over Time for DynamoDB Tables
When discussing DynamoDB capacity, we refer to read and write capacity units, which you can configure manually or set to auto scale based on your application’s needs.
After syncing data from AWS, CloudQuery creates a table named aws_dynamodb_tables. This table holds crucial data regarding the capacity units for each DynamoDB table.
To analyze capacity changes, you can use the SQL Lag() function, along with partitioning by the unique resource identifier, Amazon Resource Names (ARN), and ordering by sync time. This approach allows you to observe changes at each sync point.
The Lag() function lets you look at previous rows with the previous being dependent on your ordering (in this case the _cq_sync_time column) and also specify groups/partitions which first “groups” the data and then looks only at rows that are of the same group (in this case rows with the same ARN).
SELECT
    ARN,
    _cq_sync_time,
    provisioned_throughput->>'ReadCapacityUnits' AS current_read_capacity,
    provisioned_throughput->>'WriteCapacityUnits' AS current_write_capacity,
    LAG((provisioned_throughput->>'ReadCapacityUnits')::integer) OVER (PARTITION BY ARN ORDER BY _cq_sync_time) AS previous_read_capacity,
    LAG((provisioned_throughput->>'WriteCapacityUnits')::integer) OVER (PARTITION BY ARN ORDER BY _cq_sync_time) AS previous_write_capacity,
    ((provisioned_throughput->>'ReadCapacityUnits')::integer - LAG((provisioned_throughput->>'ReadCapacityUnits')::integer) OVER (PARTITION BY ARN ORDER BY _cq_sync_time)) AS read_capacity_change,
    ((provisioned_throughput->>'WriteCapacityUnits')::integer - LAG((provisioned_throughput->>'WriteCapacityUnits')::integer) OVER (PARTITION BY ARN ORDER BY _cq_sync_time)) AS write_capacity_change
FROM
    aws_dynamodb_tables
ORDER BY
    ARN, _cq_sync_time;
In this example, data is synced every 12 hours, which results in a table like this:
ARN
_cq_sync_time
current_read_capacity
current_write_capacity
previous_read_capacity
previous_write_capacity
read_capacity_change
write_capacity_change
arn:aws:dynamodb:REGION:ACCOUNT/example1
2024-06-03 09:00:00
14
17
15.0
15.0
-1.0
2.0
arn:aws:dynamodb:REGION:ACCOUNT/example1
2024-06-05 09:00:00
14
18
14.0
17.0
0.0
2.0
arn:aws:dynamodb:REGION:ACCOUNT/example2
2024-06-03 09:00:00
14
13
16.0
20.0
1.0
-1.0
arn:aws:dynamodb:REGION:ACCOUNT/example2
2024-06-05 09:00:00
17
16
14.0
13.0
1.0
1.0
arn:aws:dynamodb:REGION:ACCOUNT/example3
2024-06-03 09:00:00
16
16
15.0
15.0
1.0
1.0
arn:aws:dynamodb:REGION:ACCOUNT/example3
2024-06-05 09:00:00
20
22
18.0
20.0
2.0
2.0
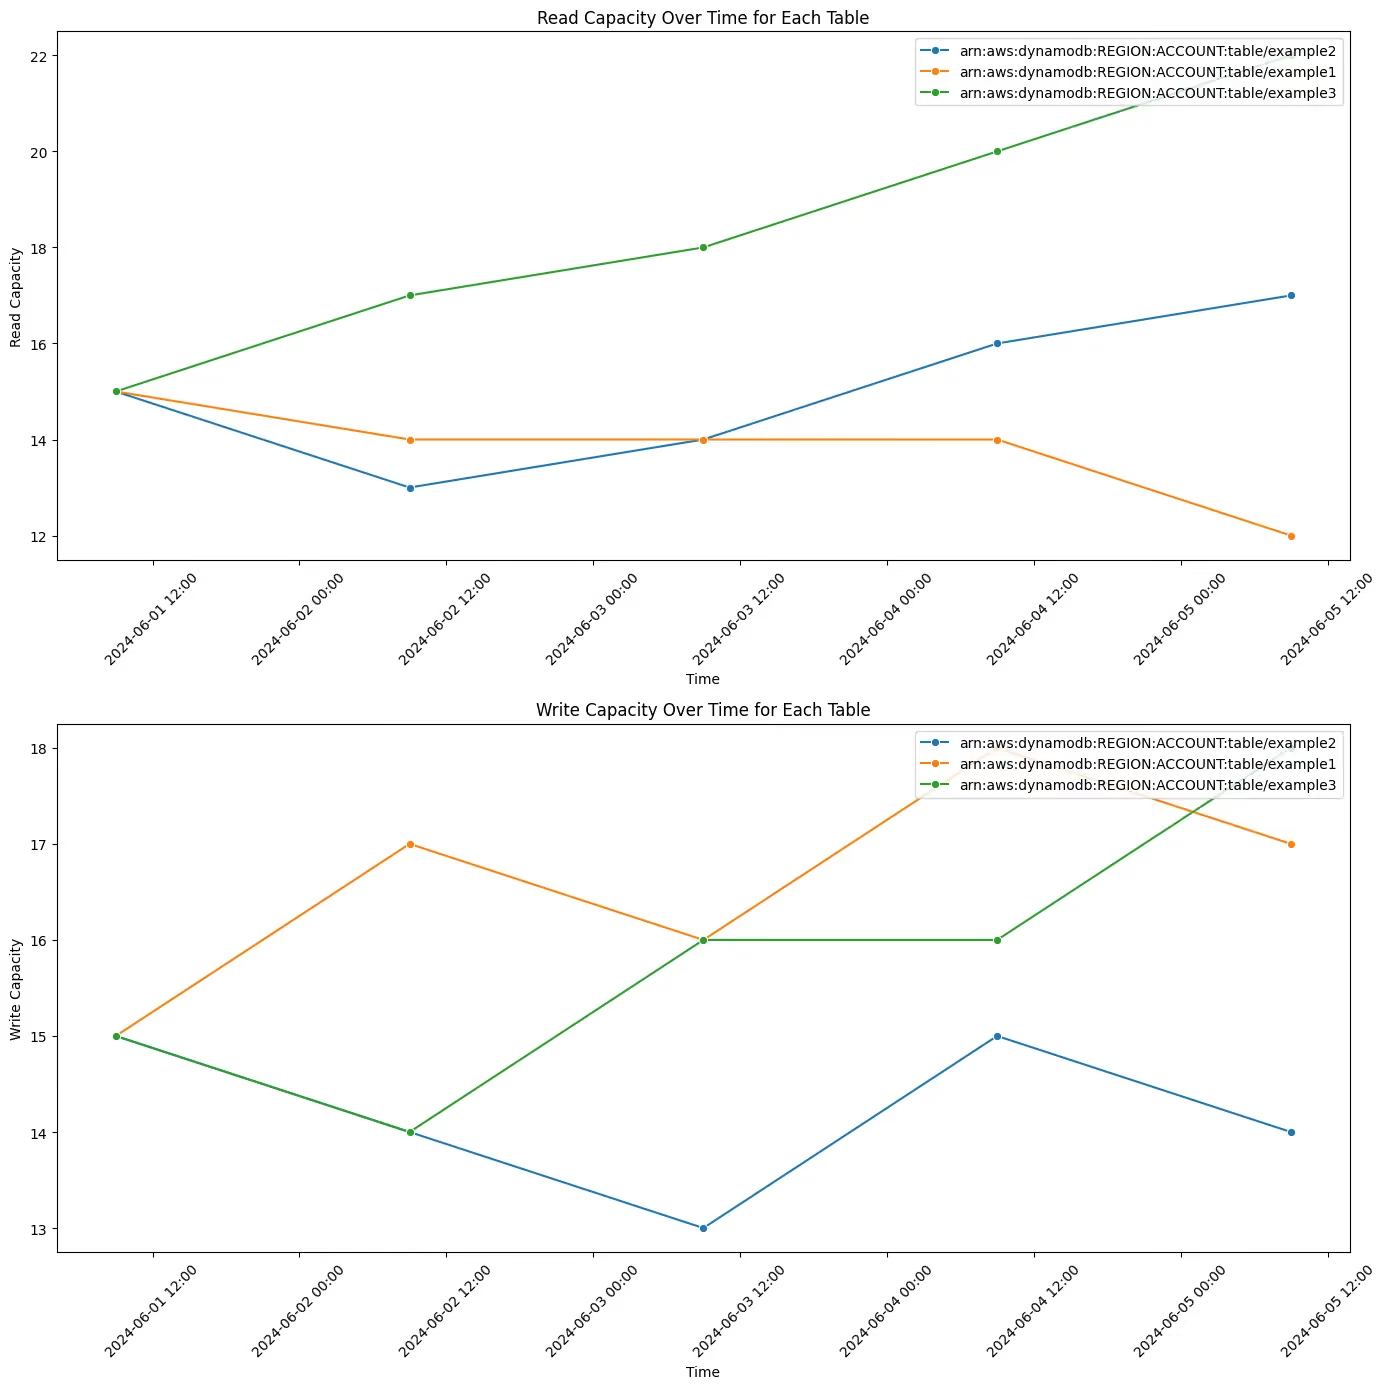
Visualizing this data can provide immediate insights into which of your tables have experienced an increase in capacity:
You can run the query below to identify which DynamoDB tables have grown the most in capacity over the past 30 days. This query is the same as the previous one, this query also utilizes the SQL Lag() function, but after that, you group the data by the ARN and aggregate the metrics calculated before, which then lets you see the combined/summed change over time.
WITH capacity_changes AS (
    SELECT
        ARN,
        _cq_sync_time,
        (provisioned_throughput->>'ReadCapacityUnits')::integer AS current_read_capacity,
        (provisioned_throughput->>'WriteCapacityUnits')::integer AS current_write_capacity,
        LAG((provisioned_throughput->>'ReadCapacityUnits')::integer) OVER (PARTITION BY ARN ORDER BY _cq_sync_time) AS previous_read_capacity,
        LAG((provisioned_throughput->>'WriteCapacityUnits')::integer) OVER (PARTITION BY ARN ORDER BY _cq_sync_time) AS previous_write_capacity,
        ((provisioned_throughput->>'ReadCapacityUnits')::integer - LAG((provisioned_throughput->>'ReadCapacityUnits')::integer) OVER (PARTITION BY ARN ORDER BY _cq_sync_time)) AS read_capacity_change,
        ((provisioned_throughput->>'WriteCapacityUnits')::integer - LAG((provisioned_throughput->>'WriteCapacityUnits')::integer) OVER (PARTITION BY ARN ORDER BY _cq_sync_time)) AS write_capacity_change
    FROM
        aws_dynamodb_tables
    WHERE
        _cq_sync_time >= NOW() - INTERVAL '30 days'
)
SELECT
    ARN,
    SUM(read_capacity_change) AS total_read_capacity_change,
    SUM(write_capacity_change) AS total_write_capacity_change,
    SUM(read_capacity_change + write_capacity_change) AS total_capacity_change
FROM
    capacity_changes
GROUP BY
    ARN
ORDER BY
    total_capacity_change DESC;
The resulting table would look something like this:
arn
total_read_capacity_change
total_write_capacity_change
total_capacity_change
arn:aws:dynamodb:REGION:ACCOUNT/EXAMPLE3
24.0
9.0
33.0
arn:aws:dynamodb:REGION:ACCOUNT/EXAMPLE1
11.0
12.0
23.0
arn:aws:dynamodb:REGION:ACCOUNT/EXAMPLE2
14.0
7.0
21.0
This table shows that the table, EXAMPLE3, has seen the largest increase in read and write capacity units combined over the past 30 days. This information is crucial for optimizing resource allocation and ensuring your DynamoDB tables are scaled appropriately.
Identifying AWS Lambda Functions with the Most Growth in Memory and Storage Over the Last 30 Days
AWS Lambda is a serverless computing service that allows you to run code without provisioning or managing servers. You pay only for the compute time you consume. Lambda functions can be configured with different memory sizes and automatically provide a fixed amount of CPU power proportional to the memory configured. Additionally, you can configure ephemeral storage for temporary data. Tracking changes in memory and storage configurations is essential for performance tuning and cost management.
To analyze changes in memory and storage sizes for your Lambda functions, you can use a similar SQL query as you did above to analyze the capacity of your DynamoDB tables. The query below tracks changes over time using the SQL lag function and partitions the data by the ARN.
SELECT
    arn,
    _cq_sync_time,
    (configuration->>'MemorySize')::integer AS current_memory_size,
    LAG((configuration->>'MemorySize')::integer) OVER (PARTITION BY arn ORDER BY _cq_sync_time) AS previous_memory_size,
    ((configuration->>'MemorySize')::integer - LAG((configuration->>'MemorySize')::integer) OVER (PARTITION BY arn ORDER BY _cq_sync_time)) AS memory_size_change,
    (configuration->'EphemeralStorage'->>'Size')::integer AS current_storage_size,
    LAG((configuration->'EphemeralStorage'->>'Size')::integer) OVER (PARTITION BY arn ORDER BY _cq_sync_time) AS previous_storage_size,
    ((configuration->'EphemeralStorage'->>'Size')::integer - LAG((configuration->'EphemeralStorage'->>'Size')::integer) OVER (PARTITION BY arn ORDER BY _cq_sync_time)) AS storage_size_change
FROM
    aws_lambda_functions
ORDER BY
    arn, _cq_sync_time;
This will result in a table like this:
arn
_cq_sync_time
current_memory_size
current_storage_size
previous_memory_size
previous_storage_size
memory_size_change
storage_size_change
arn:aws:lambda:REGION:ACCOUNT:function
2024-06-01 09:00:00
128
512
NaN
NaN
NaN
NaN
arn:aws:lambda:REGION:ACCOUNT:function
2024-06-02 09:00:00
256
528
128.0
512.0
128.0
16.0
arn:aws:lambda:REGION:ACCOUNT:function
2024-06-03 09:00:00
224
560
256.0
528.0
-32.0
32.0
arn:aws:lambda:REGION:ACCOUNT:function
2024-06-01 09:00:00
128
512
NaN
NaN
NaN
NaN
arn:aws:lambda:REGION:ACCOUNT:function
2024-06-02 09:00:00
256
544
128.0
512.0
128.0
32.0
arn:aws:lambda:REGION:ACCOUNT:function
2024-06-03 09:00:00
320
560
256.0
544.0
64.0
16.0
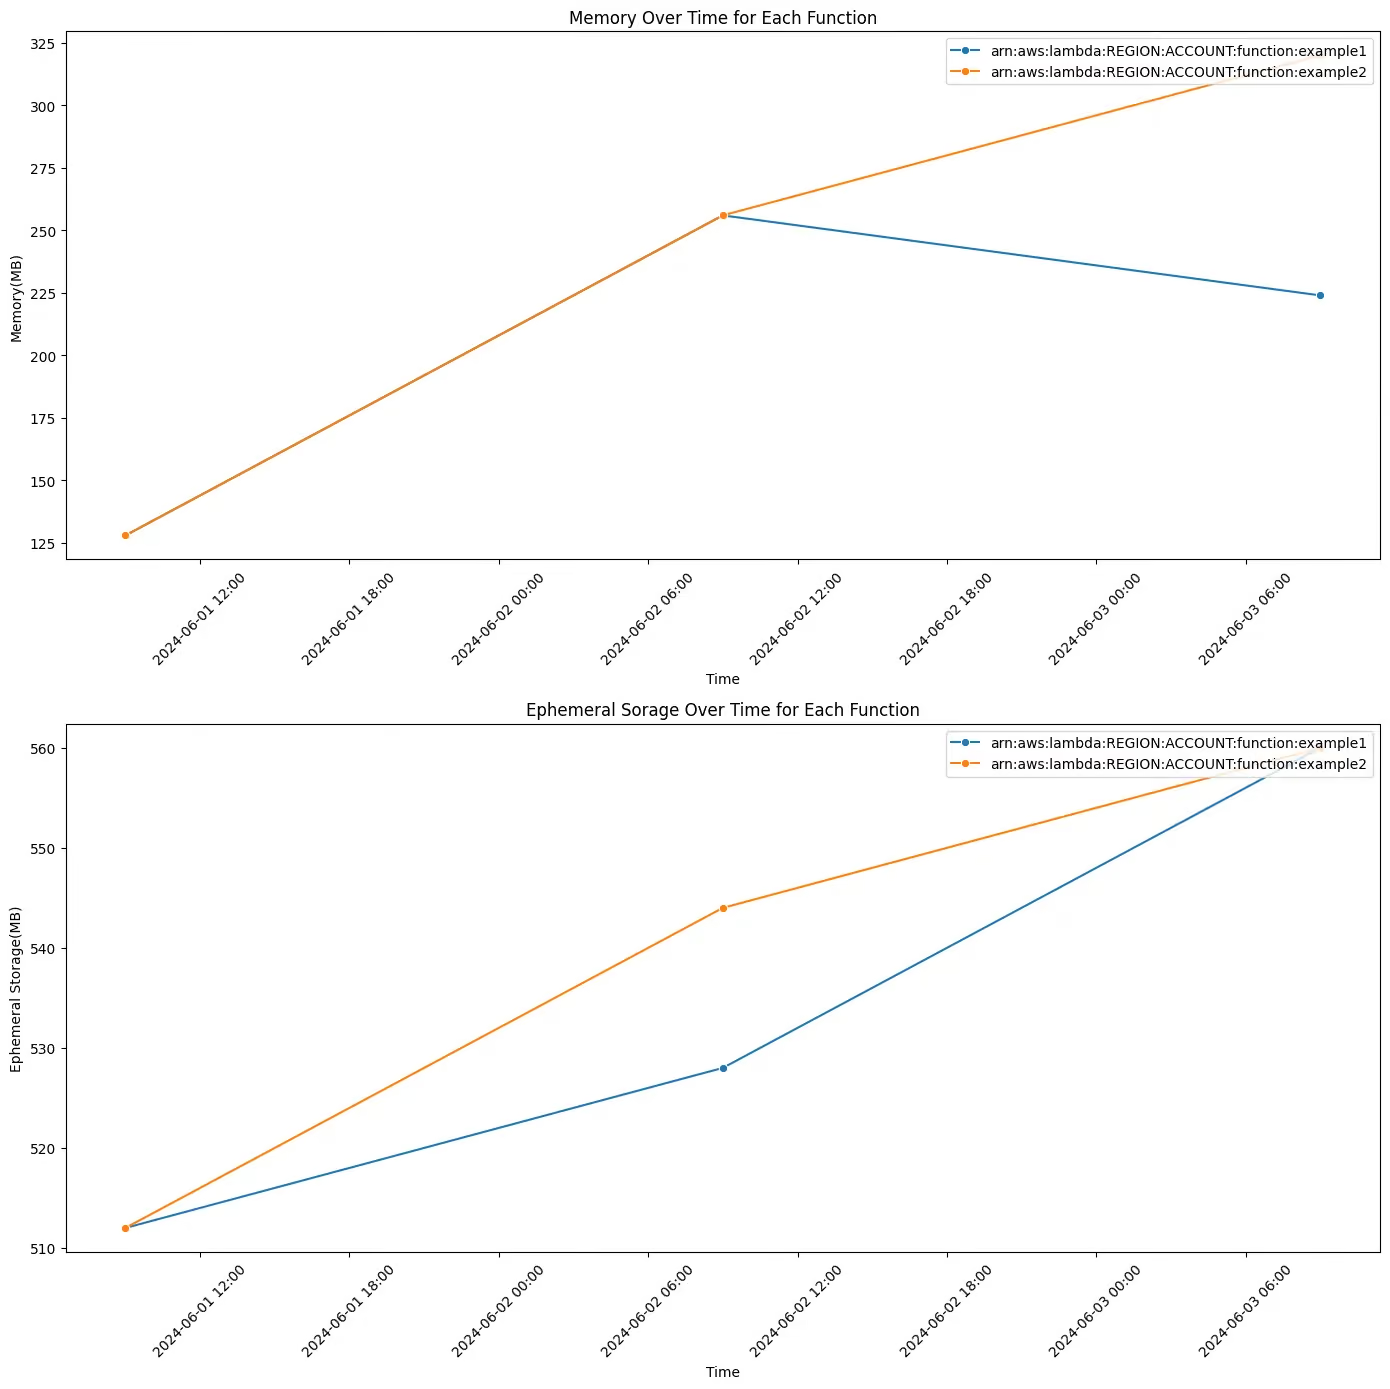
Which can then be visualized like the DynamoDB table data
In the same way that you previously identified DynamoDB tables with the most growth in capacity, you can identify which Lambda functions grew the most in terms of memory and storage capacity. The query below finds this result and will be sorted by largest memory size change:
WITH memory_storage_changes AS (
    SELECT
        arn,
        _cq_sync_time,
        (configuration->>'MemorySize')::integer AS current_memory_size,
        LAG((configuration->>'MemorySize')::integer) OVER (PARTITION BY arn ORDER BY _cq_sync_time) AS previous_memory_size,
        ((configuration->>'MemorySize')::integer - LAG((configuration->>'MemorySize')::integer) OVER (PARTITION BY arn ORDER BY _cq_sync_time)) AS memory_size_change,
        (configuration->'EphemeralStorage'->>'Size')::integer AS current_storage_size,
        LAG((configuration->'EphemeralStorage'->>'Size')::integer) OVER (PARTITION BY arn ORDER BY _cq_sync_time) AS previous_storage_size,
        ((configuration->'EphemeralStorage'->>'Size')::integer - LAG((configuration->'EphemeralStorage'->>'Size')::integer) OVER (PARTITION BY arn ORDER BY _cq_sync_time)) AS storage_size_change
    FROM
        aws_lambda_functions
    WHERE
        _cq_sync_time >= NOW() - INTERVAL '30 days'
)
SELECT
    arn,
    SUM(memory_size_change) AS total_memory_size_change,
    SUM(storage_size_change) AS total_storage_size_change
FROM
    memory_storage_changes
GROUP BY
    arn
ORDER BY
    total_memory_size_change DESC;
And will result in a table like this:
arn
total_memory_size_change
total_storage_size_change
arn:aws:lambda:REGION:ACCOUNT/EXAMPLE1
384
512
arn:aws:lambda:REGION:ACCOUNT/EXAMPLE2
0
0
arn:aws:lambda:REGION:ACCOUNT/EXAMPLE3
0
0
From this table, you can identify which functions grew the most over the last 30 days in terms of memory and storage capacity.
How to analyze changes in size and throughput for AWS EBS volumes
Amazon Elastic Block Store (EBS) provides persistent block storage for Amazon EC2 instances. EBS volumes are designed to offer high availability and durability, making them suitable for a wide range of workloads. When working with EBS volumes, two critical aspects to monitor are size and throughput:
Size: This refers to the allocated storage capacity of the EBS volume. Tracking changes in volume size is crucial for cost management and ensuring that your storage meets the demands of your applications.
Throughput: This measures the data transfer rate to and from the EBS volume. Monitoring throughput helps in optimizing performance, especially for applications that require high I/O operations.
By using CloudQuery, you can track these changes over time, allowing you to manage your EBS volumes more effectively and ensure optimal performance and cost-efficiency.
To analyze changes in size and throughput for EBS volumes, you can use a similar SQL query as you did for DynamoDB tables and Lambda functions. The query tracks changes over time using the lag function and partitions the data by the ARN.
SELECT
    arn,
    _cq_sync_time,
    (size)::integer AS current_size,
    LAG((size)::integer) OVER (PARTITION BY arn ORDER BY _cq_sync_time) AS previous_size,
    ((size)::integer - LAG((size)::integer) OVER (PARTITION BY arn ORDER BY _cq_sync_time)) AS size_change,
    (throughput)::integer AS current_throughput,
    LAG((throughput)::integer) OVER (PARTITION BY arn ORDER BY _cq_sync_time) AS previous_throughput,
    ((throughput)::integer - LAG((throughput)::integer) OVER (PARTITION BY arn ORDER BY _cq_sync_time)) AS throughput_change
FROM
    aws_ec2_ebs_volumes
ORDER BY
    arn, _cq_sync_time;
This query results table similar to this
arn
_cq_sync_time
current_size
current_throughput
previous_size
previous_throughput
size_change
throughput_change
arn:aws:ec2:REGION:ACCOUNT/example1
2024-06-01 09:00:00
100
100
NaN
NaN
NaN
NaN
arn:aws:ec2:REGION:ACCOUNT/example1
2024-06-02 09:00:00
125
150
100.0
100.0
25.0
50.0
arn:aws:ec2:REGION:ACCOUNT/example1
2024-06-03 09:00:00
150
170
125.0
150.0
25.0
20.0
arn:aws:ec2:REGION:ACCOUNT/example2
2024-06-01 09:00:00
100
100
NaN
NaN
NaN
NaN
arn:aws:ec2:REGION:ACCOUNT/example2
2024-06-02 09:00:00
100
150
100.0
100.0
0.0
50.0
arn:aws:ec2:REGION:ACCOUNT/example2
2024-06-03 09:00:00
110
200
100.0
150.0
10.0
50.0
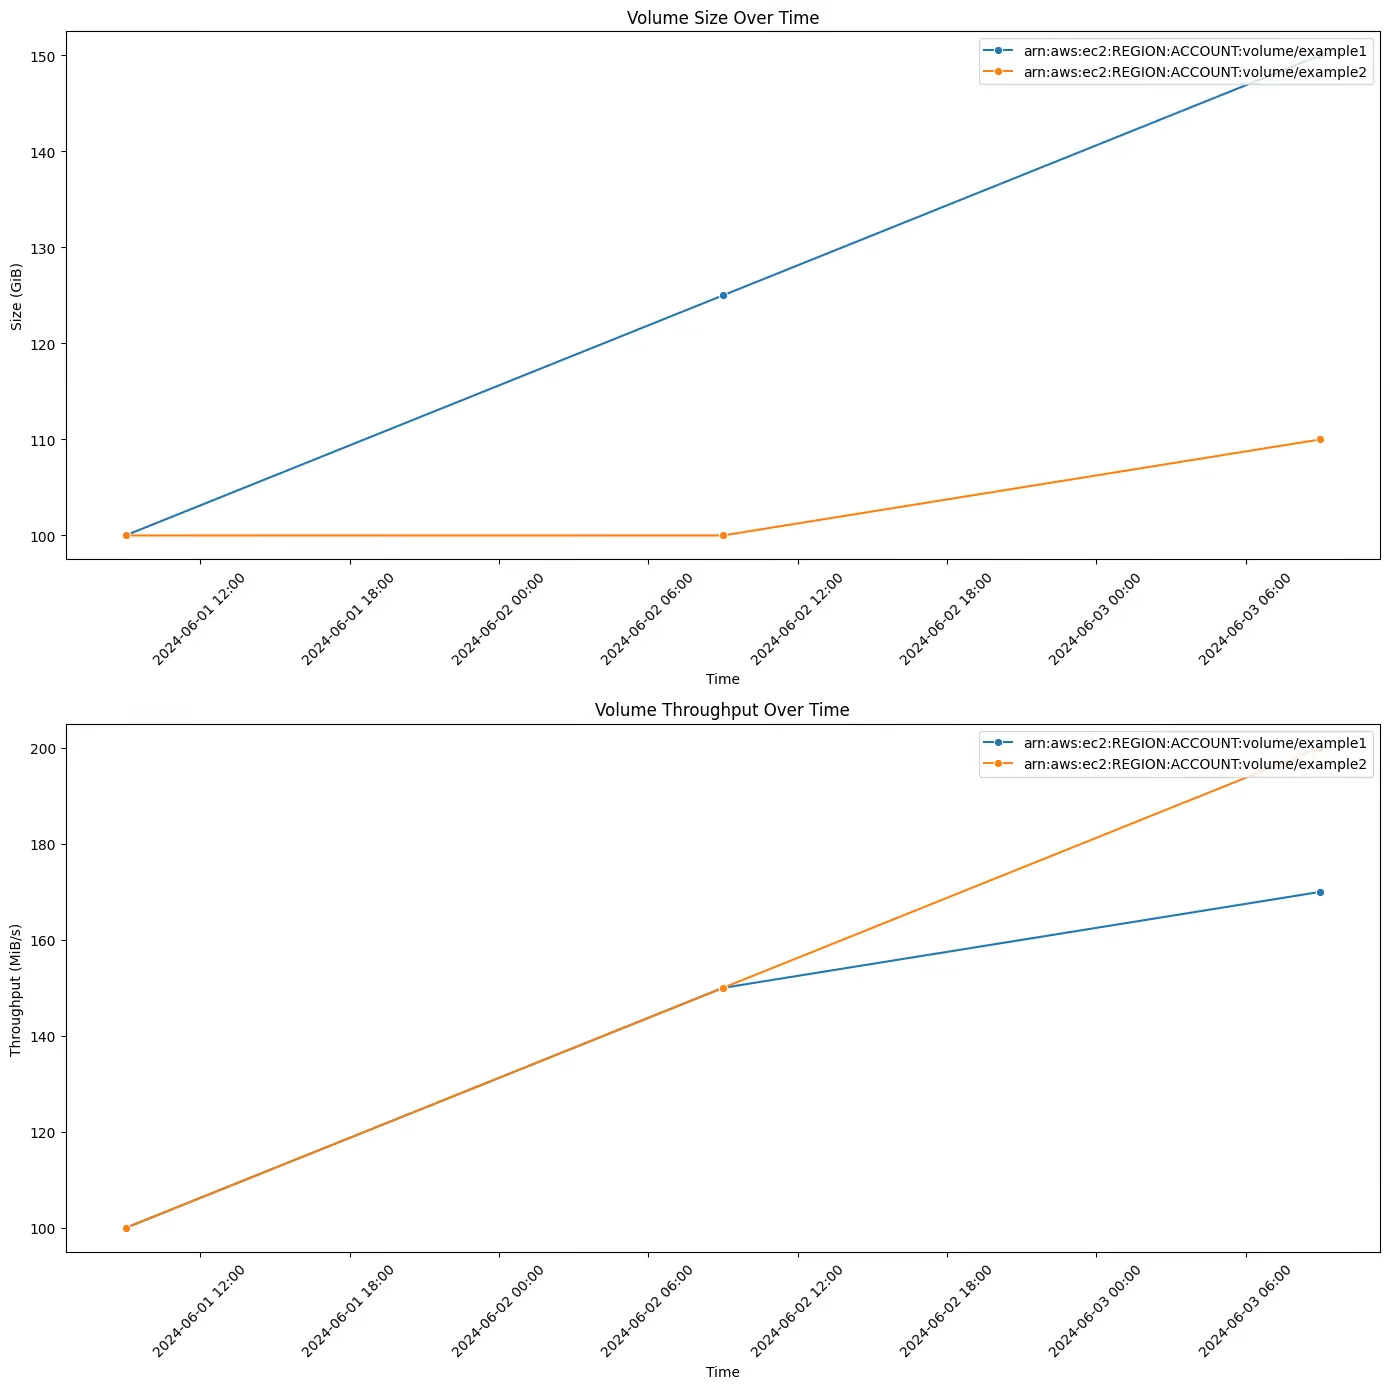
Visualized:
With a small modification, you can take one of the queries previously written and get the volumes that grew the most:
WITH size_throughput_changes AS (
    SELECT
        arn,
        _cq_sync_time,
        (size)::integer AS current_size,
        LAG((size)::integer) OVER (PARTITION BY arn ORDER BY _cq_sync_time) AS previous_size,
        ((size)::integer - LAG((size)::integer) OVER (PARTITION BY arn ORDER BY _cq_sync_time)) AS size_change,
        (throughput)::integer AS current_throughput,
        LAG((throughput)::integer) OVER (PARTITION BY arn ORDER BY _cq_sync_time) AS previous_throughput,
        ((throughput)::integer - LAG((throughput)::integer) OVER (PARTITION BY arn ORDER BY _cq_sync_time)) AS throughput_change
    FROM
        aws_ec2_ebs_volumes
    WHERE
        _cq_sync_time >= NOW() - INTERVAL '30 days'
)
SELECT
    arn,
    SUM(size_change) AS total_size_change,
    SUM(throughput_change) AS total_throughput_change
FROM
    size_throughput_changes
GROUP BY
    arn
ORDER BY
    total_size_change DESC;
This results in this table where you can identify which volume grew and which volume didn't change.
arn
total_size_change
total_throughput_change
arn:aws:ec2:REGION:ACCOUNT/EXAMPLE1
6
75
arn:aws:ec2:REGION:ACCOUNT/EXAMPLE2
0
0
arn:aws:ec2:REGION:ACCOUNT/EXAMPLE3
0
0
Summary
By leveraging CloudQuery to track changes in AWS resources like DynamoDB, Lambda functions, and EBS volumes, you can gain insights into your cloud infrastructure’s performance and cost dynamics. Start syncing your AWS resources with CloudQuery today and take control of your cloud infrastructure like never before.
Ready to dive deeper into your AWS resource capacity data? Try CloudQuery today and gain comprehensive insights into your AWS resources. Contact us or Join the CloudQuery Community to connect with other users and our engineering team, and explore the full potential of CloudQuery.
Written by
Jonathan Sarig
Jonathan is a software engineer at CloudQuery with a particular interest in machine learning. He primarily works in golang but also has experience in (and a passion for) Rust.
Try CloudQuery yourself
Self-hosted, open source, and free to start. Or schedule a demo to see the managed version.
Download →
Schedule a demo →
Related posts
AWS
Security
Tutorials
Finding AWS Unrestricted Outbound Access in 2026: EC2, Lambda, and Beyond
Find EC2, Lambda, and ECS Fargate resources with unrestricted outbound access in AWS using SQL. Why egress controls still break attack chains in 2026.
Joe Karlsson
May 5, 2026
AWS
Security
Tutorials
AWS IAM Identity Center with Google Workspace as an IdP: 2026 Step-by-Step Guide
Set up AWS IAM Identity Center with Google Workspace: SAML authentication, SCIM user provisioning, and group sync with CLI or ssosync. Updated for 2026.
Joe Karlsson
May 5, 2026
AWS
Cloud Infrastructure
Security
Tutorials
Integrate AbuseIPDB Threat Intelligence with CloudQuery
Enrich your cloud asset inventory with AbuseIPDB threat intelligence to identify public cloud IPs with known abuse reports.
Joe Karlsson
April 20, 2026
AWS
Cloud Infrastructure
Tutorials
How to Query ipinfo.io Data with CloudQuery
Learn how to enrich your cloud asset inventory with ipinfo.io IP geolocation and threat intelligence data using CloudQuery.
Joe Karlsson
April 20, 2026
AWS
Security
Tutorials
AWS IAM Identity Center (Formerly AWS SSO): The Complete 2026 Guide
AWS IAM Identity Center replaced AWS SSO in 2022. Learn how to set it up, configure permission sets, use the AWS CLI, and audit access with CloudQuery.
Joe Karlsson
April 6, 2026
AWS
Tutorials
AWS Pinpoint Is Being Deprecated: How to Assess Your Migration Scope
AWS Pinpoint reaches end of support October 2026. Query your Pinpoint usage across all accounts to find what needs migrating before the deadline.
Joe Karlsson
March 24, 2026
AWS
Best Practices
Tutorials
CloudQuery Sync Performance: A Practical Troubleshooting Guide
Diagnose why CloudQuery syncs slow down after plugin upgrades, identify expensive tables, and use the CLI command that replaces the tables wildcard.
Joe Karlsson
March 6, 2026
AWS
Security
Tutorials
Set Up AWS CLI with SSO (IAM Identity Center) — Step by Step
Set up AWS CLI v2 with IAM Identity Center in 5 minutes. Covers SSO registration scopes, sso-session config, token refresh, and multi-account profiles.
Yevgeny Pats
February 25, 2026
AWS
Cloud Infrastructure
Tutorials
AWS Lambda Python 3.9 End-of-Support: Find and Upgrade Every Affected Function
AWS Lambda Python 3.9 security patches stopped Dec 15, 2025. Find every affected function across all accounts with SQL queries and upgrade to 3.12 or 3.13.