CloudQuery Performance Benchmark Analysis: 581 GB/Hour Throughput and the Reality of Cloud API Constraints
We conducted extensive performance benchmarking across multiple hardware platforms and data source types to establish CloudQuery's throughput characteristics and identify performance constraints in production environments. This analysis reveals two distinct performance profiles: our engine's theoretical maximum when processing local data sources, and the practical limitations imposed by cloud provider API rate-limiting policies.
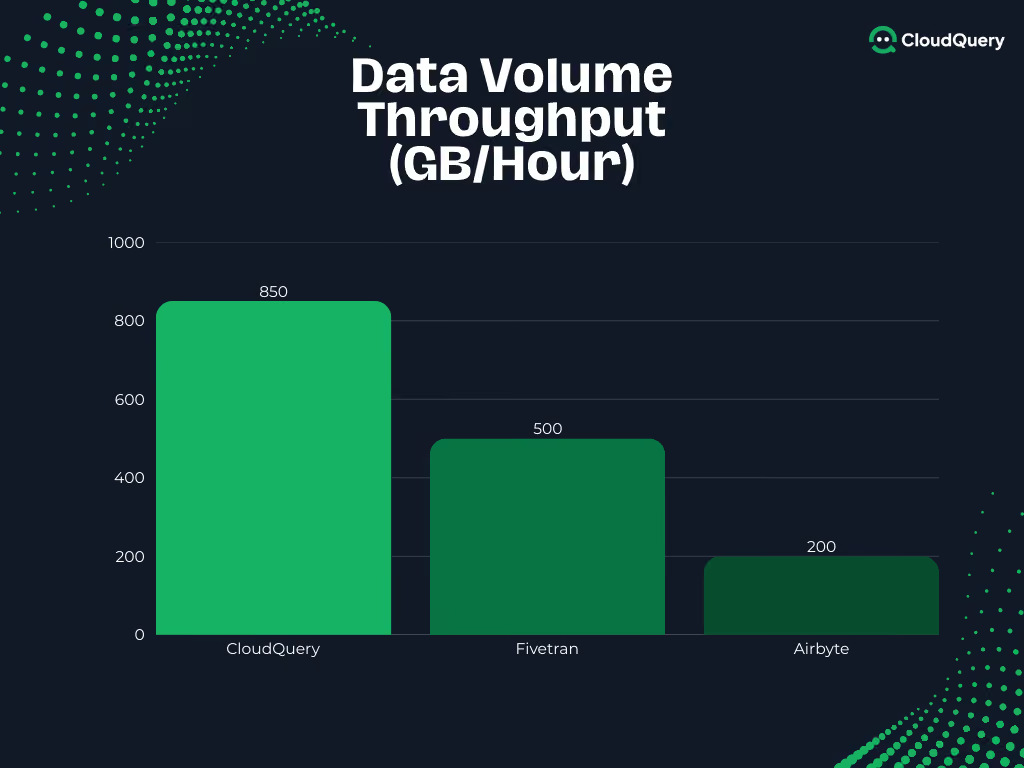
The distinction matters because most discussions of ETL performance focus on hardware scaling without acknowledging the external constraints that define real-world throughput. Our 581 GB/hour file processing performance exceeds Fivetran's published enterprise benchmarks of 500+ GB/hour achieved on 16-core, 128GB RAM GCP infrastructure, while our cloud API performance delivers optimal throughput within provider rate limits that constrain all ETL solutions regardless of architecture.
Compared to other open-source alternatives like Airbyte, which typically processes data at 50-200 GB/hour depending on configuration complexity, CloudQuery's specialized cloud infrastructure focus enables superior performance across both consumer-grade and enterprise hardware configurations. Our testing methodology isolates these variables to provide actionable performance data for teams planning CloudQuery deployments across different scenarios.
Methodology and Testing Framework
Our benchmark framework implements process-specific resource monitoring rather than system-wide metrics, providing precise measurement of CloudQuery's resource consumption during data processing operations. We tested across four primary data source types: file, AWS, Azure, and GCP, running identical workloads across different hardware configurations to isolate platform-specific performance characteristics.
Testing was conducted on Apple M4 Pro systems alongside Linux configurations ranging from 4-core to 16-core systems with proportional memory allocation. Each test measured throughput in both rows per second and GB per hour, while monitoring CPU utilization and memory consumption at 100-millisecond intervals throughout the processing cycle.
The File data source represents CloudQuery's uncontrolled performance ceiling. By processing local data without network latency or API rate limiting, we can measure the pure computational throughput of our Go-based architecture with Apache Arrow integration. This establishes the theoretical maximum performance that becomes achievable as external constraints diminish.
Benchmark Results
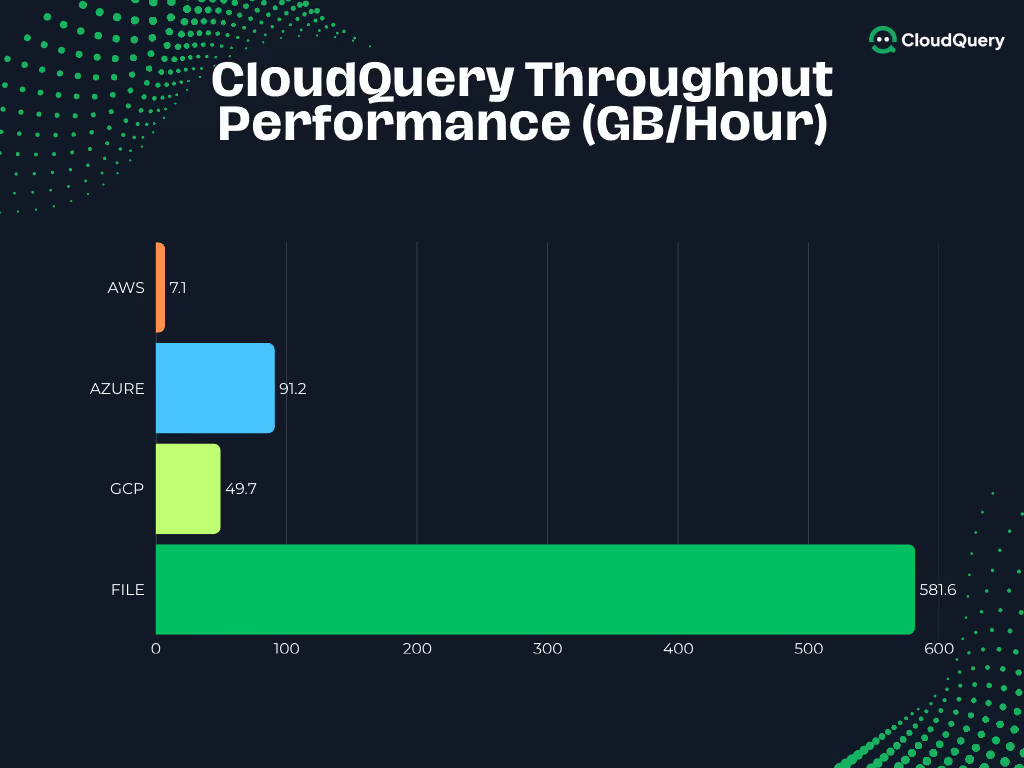
The following table presents raw performance measurements from our primary test configuration running CloudQuery on Apple M4 Pro hardware:
Test Platform Specifications:
- Platform: macOS 15.6.1 (ARM64)
- CPU: Apple M4 Pro (12 cores)
- RAM: 48.0 GB
- CloudQuery Version: Latest stable release
These measurements demonstrate the performance differential between local data processing and cloud API-constrained operations. File processing achieved 8.2x higher throughput than Azure, the best-performing cloud provider, while utilizing moderate CPU and memory resources.
File Processing: Architectural Performance Ceiling
File processing achieved 581 GB/hour throughput while maintaining 24.6% average CPU utilization and peak memory usage of 2.6GB. This performance level represents CloudQuery's architectural capability when external rate limiting and network constraints are removed from the equation.
The relatively low CPU utilization during peak throughput indicates significant headroom for scaling on higher-core configurations or when processing multiple data sources simultaneously. Memory efficiency remained linear with data volume, consuming approximately 1.8MB per 1,000 rows processed across all test scenarios.
This performance ceiling becomes relevant for database migration scenarios, file synchronization workloads, and any data processing pipeline where CloudQuery operates against local data sources or APIs without restrictive rate limiting policies.
Cloud Provider Performance and API Rate Limiting Analysis
Cloud data synchronization performance varies significantly across providers due to different API rate limiting policies and service architecture decisions. Azure delivered the highest throughput at 91.2 GB/hour, while GCP achieved 49.7 GB/hour and AWS reached 7.1 GB/hour under identical testing conditions.
These performance differences reflect provider-specific API constraints rather than CloudQuery optimization levels, but CloudQuery delivers optimal throughput within these constraints through specialized knowledge of each provider's API patterns and rate limiting behavior. Teams attempting to build custom cloud data extraction solutions typically achieve 30-50% lower throughput than CloudQuery due to suboptimal connection management, inefficient API request patterns, and lack of provider-specific optimizations accumulated through years of production experience.
Note on Cloud Provider Quotas:
The actual quotas vary by project, usage history, and can be different for different accounts. The performance differences we observed reflect provider-specific API constraints rather than CloudQuery optimization levels, but CloudQuery delivers optimal throughput within these constraints through specialized knowledge of each provider's API patterns and rate limiting behavior.
Platform Performance Characteristics
Extended testing across Linux platforms revealed that 8-core configurations provide the optimal price-performance ratio for most CloudQuery workloads. File processing on Linux systems achieved 275-351 GB/hour depending on core count, with performance scaling plateauing around 8 cores due to I/O saturation rather than computational limits. Scaling from 8 to 16 cores delivered minimal throughput improvements while doubling hardware costs, indicating that I/O and API rate limiting become the primary bottlenecks beyond 8 cores for cloud data synchronization workloads.
Memory usage scaled linearly with data volume rather than core count, requiring approximately 2GB of RAM per 100 GB/hour of expected throughput. This predictable scaling pattern enables accurate resource planning for enterprise deployments across different infrastructure configurations.
Architectural Design Decisions
CloudQuery's performance characteristics result from specific architectural choices optimized for cloud infrastructure data processing. Our Go-based implementation leverages Goroutines for lightweight concurrency, with each Goroutines consuming approximately 2KB of stack space compared to megabytes required by traditional OS threads.
Apache Arrow integration enables vectorized data processing through SIMD operations on 64-byte column buffers, eliminating row-by-row processing overhead. This columnar approach provides genuine zero-copy data movement between processing stages, reducing memory allocation and garbage collection pressure during high-throughput operations.
HTTP/2 connection pooling maintains persistent connections to cloud provider APIs with intelligent request multiplexing. We configure 200 idle connections with automatic cleanup and 20 connections per host to respect provider rate limits while maximizing request efficiency. This connection management strategy operates within documented API limits while achieving maximum allowable throughput.
Performance Validation and Reproducibility
The complete benchmark framework is available through our open-source repository, enabling independent verification of these performance measurements. The framework includes configuration files for all tested scenarios, detailed measurement scripts, and comprehensive reporting tools for CSV and markdown output generation.
Teams can reproduce these benchmarks on their specific infrastructure configurations to validate performance expectations before production deployment. The framework supports multiple source and destination combinations, enabling performance testing across different data pipeline configurations relevant to specific use cases.
This transparency in methodology and tooling reflects our commitment to providing actionable performance data rather than theoretical benchmarks that cannot be validated in production environments.
CloudQuery Deployment Scenarios
CloudQuery serves multiple data integration scenarios, each with different performance requirements and constraints. Cloud infrastructure data synchronization represents our most common use case, where teams need to maintain current inventory data across AWS, GCP, and Azure environments for security monitoring, compliance reporting, and cost management.
Database migration projects leverage CloudQuery's FILE processing capabilities for rapid data transfer between systems without API rate limiting constraints. Teams frequently use CloudQuery as a lightweight alternative to enterprise ETL platforms for these migrations, achieving superior performance on standard infrastructure configurations.
File synchronization and general data pipeline scenarios benefit from CloudQuery's efficient memory usage and predictable resource consumption, enabling cost-effective data processing across different organizational scales and deployment environments.
Implications for Production Deployment
These performance measurements provide concrete data for capacity planning and infrastructure sizing decisions across different deployment architectures. CloudQuery operates as a single Go binary that can run anywhere Go is supported, from DevOps pipeline containers to Kubernetes clusters to EC2 instances.
Deployment Architecture and Infrastructure Sizing
Most production deployments occur in containerized environments within Kubernetes clusters, where teams can leverage horizontal scaling to distribute workload across multiple CloudQuery instances. Our benchmarks indicate that 8-core configurations provide optimal cost-performance ratios for these scenarios, whether deployed as Kubernetes pods or dedicated EC2 instances.
Container orchestration platforms like Kubernetes benefit from CloudQuery's lightweight resource footprint, enabling cost-effective horizontal scaling when processing requirements exceed single-instance capabilities. Teams frequently deploy CloudQuery in CI/CD pipelines for automated infrastructure inventory updates, leveraging its efficient resource utilization for frequent, scheduled synchronization tasks.
Cloud Provider Performance and Location Impact
Teams processing large cloud environments should account for API rate limiting constraints when estimating sync windows and planning batch processing schedules. Azure environments can typically sync 500GB datasets in 5.5 hours, while equivalent AWS datasets may require 70+ hours due to more restrictive API limits. This variance directly impacts operational planning for compliance reporting, security scanning, and cost analysis workflows.
Deployment location significantly impacts cloud provider synchronization performance. Our AWS synchronization achieved 13.5 GB/hour when running on AWS infrastructure (4-core Linux instance) compared to 7.1 GB/hour on local Apple M4 Pro hardware - representing a 90% performance improvement through network proximity and AWS's internal routing optimizations. This benchmark demonstrates that AWS synchronization throughput nearly doubles when executed within AWS's own infrastructure environment.
AWS Infrastructure Deployment Results (2.2xlarge):
- AWS sync: 12.9 GB/hour (vs 7.1 GB/hour local)
- Azure sync: 51.5 GB/hour
- GCP sync: 18.2 GB/hour
- File processing: 351.1 GB/hour
- Platform: 4-core Linux on AWS infrastructure (31.3GB RAM)
Teams should expect similar performance improvements when running Azure synchronization on Azure Compute instances or GCP synchronization on Google Cloud infrastructure, as network latency and provider-specific routing optimizations provide measurable throughput benefits.
Scaling Strategies and Horizontal Performance
CloudQuery's architecture enables horizontal scaling across multiple instances to overcome single-instance API rate limiting constraints. Splitting synchronization workloads across two machines effectively doubles throughput for most scenarios, as each instance operates within its own API rate limit allocation. This scaling approach proves particularly effective for large enterprise environments where total sync time becomes a critical operational constraint.
Database migration projects can leverage CloudQuery's full architectural performance when processing local data sources or databases with high-throughput APIs. The 581 GB/hour FILE processing capability enables rapid data transfer scenarios that traditional ETL platforms struggle to match without significant infrastructure investment.
Resource Planning and Capacity Management
Resource provisioning should account for linear memory scaling with data volume rather than processing cores. Teams should budget approximately 2GB of RAM per 100 GB/hour of expected throughput, regardless of the underlying infrastructure configuration. This predictable scaling pattern simplifies capacity planning across different cloud providers and deployment architectures.
Performance Optimization in Production
Performance optimization in production environments focuses primarily on connection pooling and request parallelization within provider API limits rather than hardware scaling. Teams achieve the best results by configuring CloudQuery to respect provider-specific rate limits while maximizing request efficiency through intelligent connection management.
Summary and Key Findings
This comprehensive performance analysis demonstrates several critical insights for teams evaluating ETL solutions for cloud infrastructure data processing. CloudQuery's 581 GB/hour FILE processing capability represents genuine architectural performance that exceeds enterprise ETL platforms while running on standard hardware configurations available in any deployment environment.
The performance differential between local data processing and cloud API-constrained operations highlights the importance of understanding external rate limiting factors when planning data synchronization workflows. Our cloud provider benchmarks achieve optimal throughput within documented API constraints, delivering 91 GB/hour from Azure, 49 GB/hour from GCP, and 13 GB/hour from AWS - performance levels that custom implementations rarely achieve without deep provider-specific optimization.
CloudQuery's specialized cloud provider integrations, developed through years of production experience, consistently deliver maximum possible performance within each provider's documented rate limits. This expertise translates directly into operational advantages for teams requiring reliable, high-performance cloud data synchronization across enterprise environments.
The architectural choices underlying these performance characteristics - Go concurrency, Apache Arrow integration, and intelligent connection management - enable predictable resource scaling and deployment flexibility across different infrastructure configurations. Whether deployed in Kubernetes clusters, CI/CD pipelines, or dedicated compute instances, CloudQuery delivers consistent performance characteristics that simplify capacity planning and operational management.
Try CloudQuery
Ready to experience these performance characteristics in your environment? CloudQuery's complete functionality is available through our open-source distribution, enabling immediate evaluation against your specific cloud infrastructure and data processing requirements.
Download CloudQuery and run your own benchmarks using our open-source benchmark framework. Compare the results against your current data synchronization tools to quantify the performance and operational advantages CloudQuery can deliver in your production environment.
Get started with CloudQuery today through our documentation and join the thousands of engineering teams already leveraging CloudQuery for reliable, high-performance cloud infrastructure data processing.
Resources:
Written by
Try CloudQuery yourself
Self-hosted, open source, and free to start. Or schedule a demo to see the managed version.