DuckDB has been making a splash in the data world, and for good reason. It's a fast, in-process SQL OLAP database management system that can be used to explore data in a variety of ways.
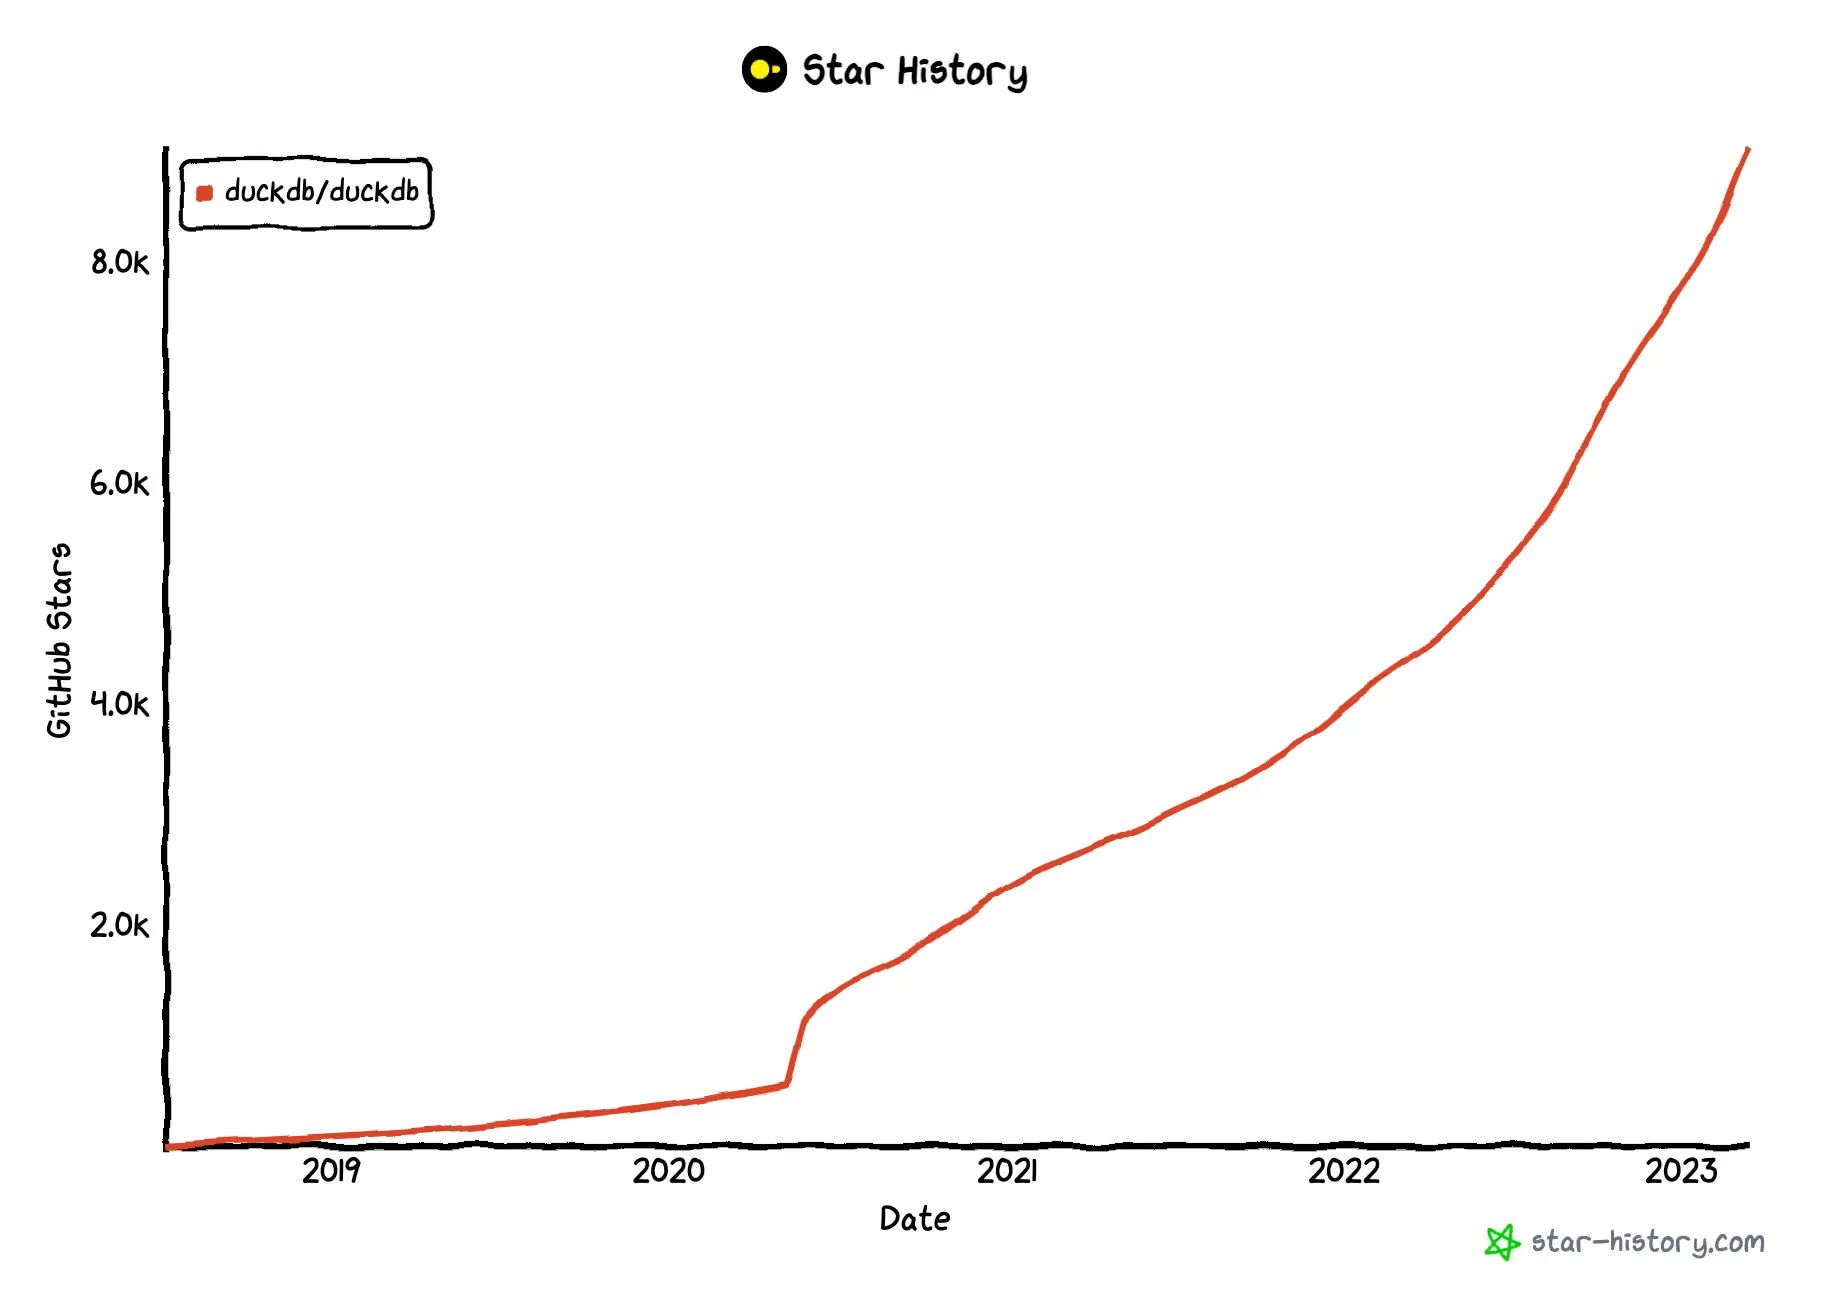
Looking at DuckDB's GitHub star history, it's clear that DuckDB has been gaining popularity rapidly:
I'm excited to share that CloudQuery has now added a new DuckDB destination integration, so you can sync data from any CloudQuery source and explore it using DuckDB. But what is DuckDB? In this post I will introduce DuckDB, show how to sync data to a local DuckDB database, and then explore the data using the DuckDB CLI.
What is DuckDB?
DuckDB describes itself as an in-process SQL OLAP database management system. That's a bit of a mouthful. DuckDB is perhaps most easily understood as being in the same category as SQLite, but focused on OLAP (online analytical processing) instead of OLTP (online transaction processing). As such, DuckDB is a columnar database, which means that it stores data in columns instead of rows. This makes it fast for aggregations and other analytical queries. Being embedded with a focus on OLAP helps it fill a niche that is not well served by other databases, as illustrated by the diagram below from the 2019 SIGMOD paper by Raasveldt & Mühleisen: DuckDB: an Embeddable Analytical Database:
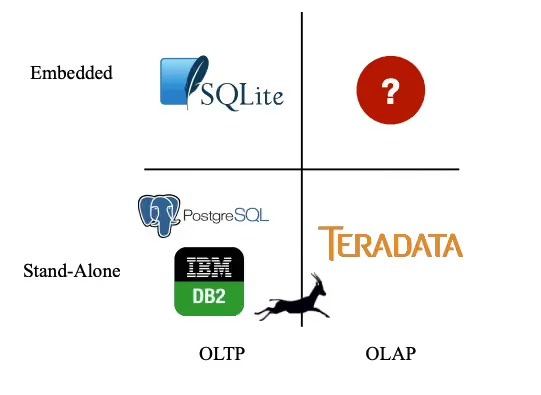
The fact that it runs in-process means that it can be used in a wide variety of applications: from Jupyter notebooks to web browsers to command-line tools.
Exploring API Data with DuckDB
By using the CloudQuery DuckDB destination integration, we can explore data from a whole range of APIs from the comfort of a local DuckDB database. But since DuckDB is an "in-process" database, and CloudQuery usually writes to databases or data lakes, it might not be entirely clear what we mean by a CloudQuery destination integration for DuckDB. Similar to SQLite, DuckDB databases can also be stored as files, so we can use the CloudQuery duckdb destination integration to sync data to a local DuckDB database file. Let's try it out!
First, we need a source dataset to sync from. If you're familiar with CloudQuery, you probably already know about the extensive AWS, GCP and Azure plugins that can sync infrastructure data. DuckDB is a great fit for quick ad-hoc exploration of this data as well, but just for fun, today let's sync data from the Homebrew Analytics API and explore it a bit using DuckDB.
First we create a CloudQuery config file called homebrew-duckdb.yml, in which we'll put both the Homebrew source and the DuckDB destination configuration:
Now we can run cloudquery sync to sync data from the Homebrew source to a local DuckDB database file (you will need to have CloudQuery installed for this step):
This should output something like the following:
Now we have a local DuckDB database file called homebrew.duckdb that contains the data from the Homebrew Analytics API. We can use the DuckDB CLI to explore the data. Check out the DuckDB Installation page for more information on how to install the CLI. Let's open the database:
This outputs the following and then waits for input:
DuckDB is great for data exploration, so let's explore some data! Let's start by looking at the homebrew_analytics_installs_30d table:
Now we can see the top 10 most installed Homebrew packages (on MacOS) in the last 30 days:
Great! This proves it works, but it's a bit boring, in my opinion. What if we wanted to see the fastest-growing Homebrew packages instead?
We can combine the homebrew_analytics_installs_30d and homebrew_analytics_installs_90d tables to find out which packages have gone up in popularity the most. We shouldn't use the count column for this, because Homebrew recently added and publicized a new way to control the analytics that gets sent. This means that the count column, which is an absolute count of installs, is being skewed by more users turning off analytics in the last month. Instead, we will use the number column, which is a relative ranking of popularity. If we do this, we should also make sure we only look at formulae that had a relatively large number of installs to begin with, otherwise a small gain in installs can lead to a large jump in ranking for long-tail formulae. Let's try it out:
And the results are:
To get the output in Markdown format (like I did for this post), you can run .mode markdown before running the query.
There are some interesting tools in that list! I'll be honest, knowing DuckDB's rise in popularity, I was expecting to see it in this list as well. Let's run a quick query to see how it did:
Perhaps not in the top 15, but moving up 228 places in ranking is still impressive! It also backs up the meteoric rise in popularity that we observed on the GitHub Stars graph earlier.
If you'd like to explore the most up-to-date data yourself, you can follow the steps above and try out some of your own queries. You can also check out the DuckDB documentation for more information on how to use DuckDB. A word of caution on the Homebrew Analytics API dataset: I suspect that these Homebrew rankings can be easily gamed or accidentally skewed by tools being installed as part of automated processes (like CI). It will also be influenced by the target demographic's likelihood to have disabled analytics. That said, it's still an interesting way to discover up-and-coming new tools; just don't take the numbers here as the final word on the matter.
Conclusion
In this post, I introduced DuckDB and the new CloudQuery DuckDB destination that allows you to load data from many APIs into a DuckDB-compatible format. I also showed you one specific use case: using DuckDB to query the Homebrew Analytics API and discover new tools that are gaining popularity. From here, we could take the analysis in a million different directions: perhaps by combining it with data from other APIs or datasets? Or graphing the popularity trends? Classifying Homebrew tools with ChatGPT or GPT4 and creating separate rankings by class? I will leave these as exercises for the reader.
Another interesting next step would be to allow CloudQuery to be run as an embedded process in the same way as DuckDB, so that both could be run from the same application, like Jupyter Notebooks. This would certainly make for a powerful combination, and it's something I'd like to explore more. Right now it would be a two-step process: sync to a local DuckDB file first, then load it from the notebook.
I'm looking forward to seeing how CloudQuery and DuckDB get used and what the community comes up with! If you have any questions or feedback, feel free to reach out to us on GitHub or our Community.
Want to see CloudQuery in action? Schedule a demo with our team or check out the platform documentation to learn more.
Want help getting started? Join the CloudQuery community to connect with other users and experts, or message our team directly here if you have any questions.
Written by
Try CloudQuery yourself
Self-hosted, open source, and free to start. Or schedule a demo to see the managed version.