Engineering

How to Work with CloudQuery Syncs with Snowflake and Backstage

We built a Backstage plugin that brings your entire cloud inventory into your developer portal. No more switching between AWS consoles or writing custom scripts to figure out what's running where. The plugin connects to CloudQuery, which automatically discovers and catalogs your cloud resources across AWS, GCP, and Azure. Once connected, your team can browse EC2 instances, S3 buckets, databases, and IAM roles directly in Backstage. Run SQL queries through a web interface, generate filterable asset inventories, and answer questions like "which resources are publicly accessible?" without leaving your developer portal.

What you'll build: A working integration that turns your CloudQuery infrastructure data into browsable, searchable content with Backstage.

What you'll get: SQL console for ad-hoc queries, asset inventory generation, and a single interface for exploring your cloud footprint.

What you need to know: Basic Backstage knowledge and a Snowflake account with data from your cloud accounts. We'll walk through CloudQuery setup if you haven't used it before.

Prerequisites

  • CloudQuery CLI set up to sync data into Snowflake.
  • Data synced to Snowflake. A minimal AWS example is in our Quickstart Guide.

Getting Started

Start by cloning the Backstage repository locally:

git clone https://github.com/cloudquery/backstage.git

In the root directory, create a file named app-config.local.yaml and add your Snowflake account details:

$ cat << 'EOF' | tee app-config.local.yaml > /dev/null
snowflake:
account: ${SNOWFLAKE_ACCOUNT}
username: ${SNOWFLAKE_USERNAME}
password: ${SNOWFLAKE_PASSWORD}
database: ${SNOWFLAKE_DATABASE}
schema: ${SNOWFLAKE_SCHEMA}
warehouse: ${SNOWFLAKE_WAREHOUSE}
role: ${SNOWFLAKE_ROLE}
authenticator: ${SNOWFLAKE_AUTHENTICATOR}
privateKeyPath: ${SNOWFLAKE_PRIVATE_KEY_PATH}
privateKeyPass: ${SNOWFLAKE_PRIVATE_KEY_PASS}
token: ${SNOWFLAKE_TOKEN}
EOF

You can use any authentication method supported by the Snowflake Node.js driver.

Running the Demo App

To get a quick idea on how the plugin works, install dependencies and start the app:

yarn install
yarn start

This will automatically launch the UI at http://localhost:3000.

Install Plugins to Existing Backstage App

You can easily integrate our plugin into your existing app.

  1. Copy the frontend and backend components of our plugin into your integrations directory:
cp -r plugins/cq-snowflake-frontend /path/to/your/app/plugins
cp -r plugins/cq-snowflake-backend /path/to/your/app/plugins
  1. Open your packages/app/packages.json and add a dependency for the frontend component:
{
"dependencies": {
"@internal/plugin-cq-snowflake-frontend": "workspace:*"
}
}
  1. Open packages/backend/src/index.ts and do the same for the backend component:
backend.add(import('@internal/plugin-cq-snowflake-backend'));
  1. You can now reference the plugin UI in the main app code. For example, you can add it as a route inside packages/app/src/app.tsx:
...
import { CqSnowflakeFrontendSqlConsolePage, CqSnowflakeFrontendAssetInventoryPage } from '@internal/plugin-cq-snowflake-frontend';

} />
} />
...
  1. Install dependencies with yarn install and you're done! 🎉

Using the SQL Console

The SQL console allows you to run arbitrary queries against your CloudQuery sync data.
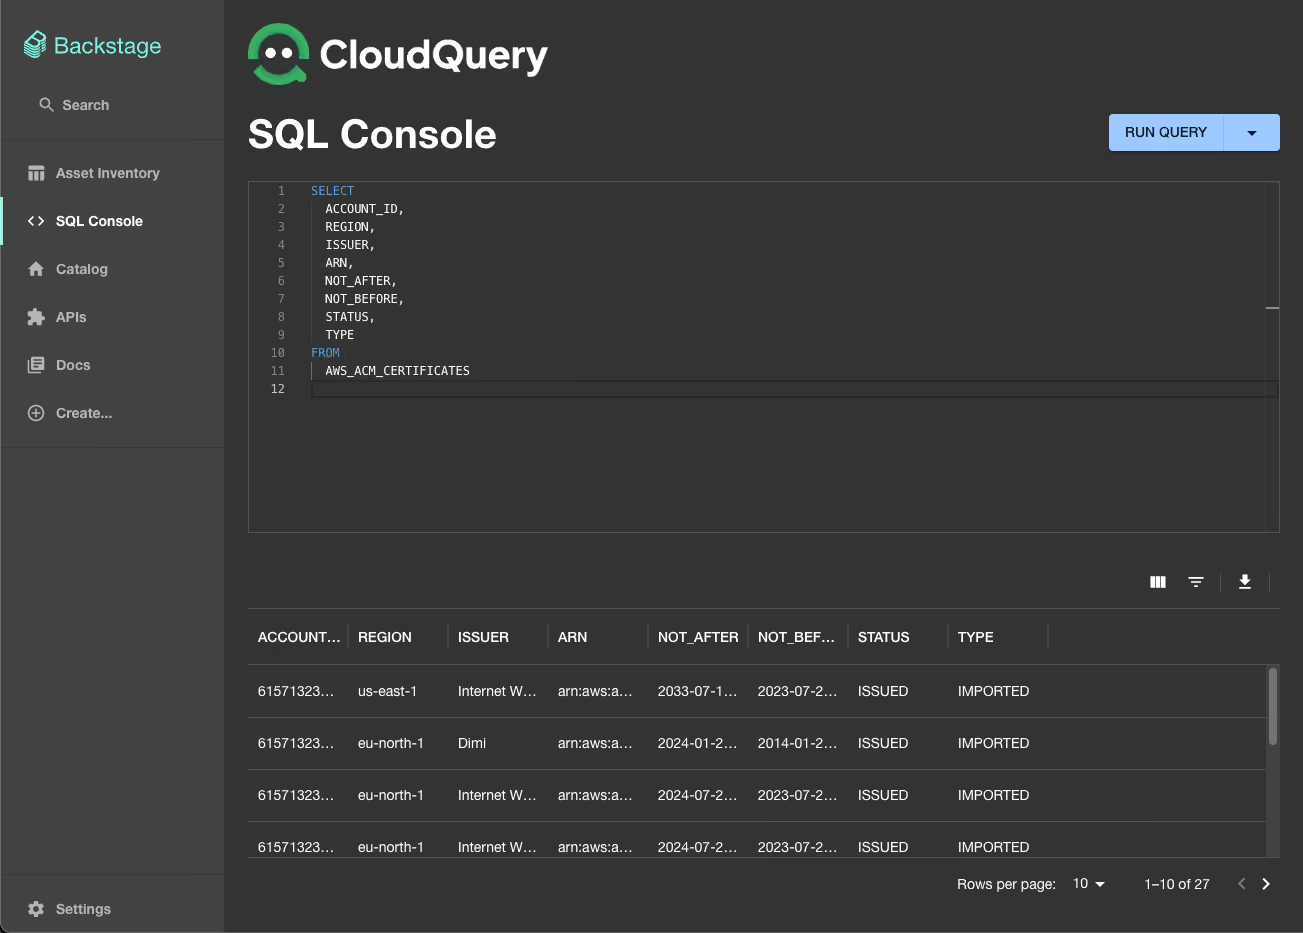
Backstage SQL Console showing a query interface with SQL editor and results panel

Generating Asset Inventory

Open the Asset Inventory page and click Generate Data. This will start a background task to create and populate your asset inventory.
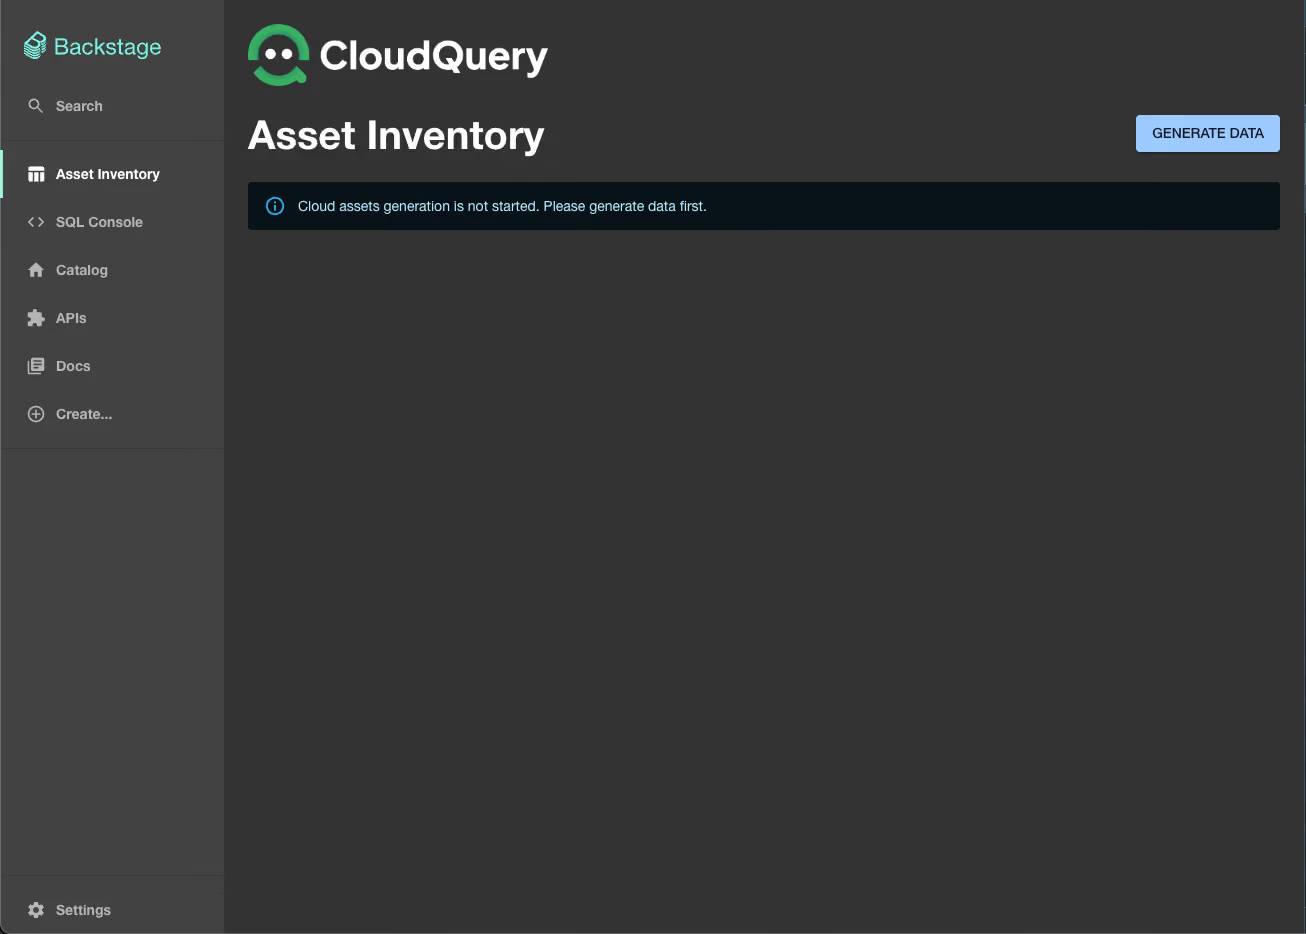
Empty Backstage Asset Inventory page with Generate Data button

This could take several minutes, depending on how much data you have on Snowflake. Once the task is done, you should be able to browse your asset inventory 🎉

Populated Backstage Asset Inventory showing cloud resources in a table format
Backstage Asset Inventory with filter panel showing search and filtering options

Wrap up

You've successfully set up a Backstage plugin that integrates with CloudQuery and Snowflake to provide a comprehensive view of your cloud infrastructure. The plugin offers:

  • SQL Console: Run ad-hoc queries against your CloudQuery sync data
  • Asset Inventory: Generate and browse filterable asset inventories
  • Unified Interface: Access all your cloud resources from one place

This integration eliminates the need to switch between multiple cloud consoles and provides a developer-friendly way to explore and query your infrastructure data.

Next Steps

If you find the plugin useful or have any feedback, we'd love to hear from you!

Try CloudQuery yourself

Self-hosted, open source, and free to start. Or schedule a demo to see the managed version.

Related posts

Engineering

We benchmarked our ETL tool and synced 1 million rows in 2 seconds on a MacBook

We benchmarked our ETL tool and synced 1 million rows in 2 seconds on laptop hardware, which is 68% faster than enterprise platforms.

Joe Karlsson

Joe Karlsson

August 27, 2026

Engineering

Third Normal Form (3NF) vs Star Schema: When to Use Each

Learn the differences between Third Normal Form (3NF) and star schema with SQL examples, table diagrams, and guidance on when to use each in a data warehouse.

Tim Armstrong

Tim Armstrong

February 25, 2026

Cloud Asset Inventory

Engineering

Platform Engineering

6 Cloud CMDB Best Practices for Platform Engineers (2026 Guide)

Cloud CMDB best practices for multi-account environments: automated discovery, tiered sync strategies, SQL-based querying, and historical data retention.

Joe Karlsson

Joe Karlsson

October 29, 2025

Cloud Asset Inventory

Engineering

The Real-Time Cloud CMDB - Why Ephemeral Infrastructure Killed Traditional Discovery

Traditional CMDBs miss ephemeral resources because containers live minutes. Modern cloud CMDBs use tiered sync strategies for real-time accuracy and coverage.

Joe Karlsson

Joe Karlsson

October 24, 2025

AI

Engineering

Tutorials

Scale GitHub Issues semantic search with CloudQuery, BigQuery, and Vertex AI

Sync GitHub issues to BigQuery with CloudQuery, generate Vertex AI embeddings via BigQuery remote models, and power fast, fully managed semantic search.

Mariano Gappa

Mariano Gappa

October 9, 2025

AWS

Cloud Infrastructure

Engineering

How to Design a Cloud Asset Inventory for AWS

Learn five essential design principles for cloud asset inventories: freshness, completeness, normalization, queryability, and automation for real AWS results.

Joe Karlsson

Joe Karlsson

October 3, 2025

AI

Engineering

Tutorials

Improve GitHub Issues search effortlessly with CloudQuery, pgvector and OpenAI

Turn GitHub issues into instant insights by syncing with CloudQuery, generating pgvector embeddings in PostgreSQL, and querying with natural language.

Mariano Gappa

Mariano Gappa

October 1, 2025

Engineering

CloudQuery Performance Benchmark Analysis: 581 GB/Hour Throughput and the Reality of Cloud API Constraints

Performance analysis of CloudQuery across AWS, GCP, and Azure achieving 581 GB/hour throughput on consumer hardware, with real-world API constraint data.

Joe Karlsson

Joe Karlsson

September 15, 2025

AI

Engineering

How we made our IDEs data-aware with a Go MCP Server

How we built a Go-based MCP server to make AI Assistants AI data-aware, bridging code and database, which ended up transforming the way we code.

Mariano Gappa

Mariano Gappa

Joe Karlsson

Joe Karlsson

July 29, 2025

Own your pipeline.
Own your data.