Prerequisites
- A CloudQuery API Key (https://www.cloudquery.io/docs/cli/managing-cloudquery/deployments/generate-api-key).
- A Databricks account with sufficient privileges to create Jobs, Apps, secrets, etc.
- Something to sync across; in this example we'll sync across some AWS sample data.
Setting up Databricks Secrets
We'll be using secrets to store all authentication and other sensitive data. We'll be using these when we configure the CloudQuery sync.
The easiest way to create secrets is via the Databricks CLI, which you can install following these instructions: https://docs.databricks.com/aws/en/dev-tools/cli/install
Before being able to make requests via the CLI, run Databricks auth login and follow the steps.
Before creating the secrets, you'll have to create a "scope" for them. You can call it default or whatever you choose. Use Databricks secrets create-scope to create it.
Once the scope is created, you can use this to create each secret, e.g.:
These are the secrets we need:
- AWS authentication in order to request the data to be synced across (the AWS login screen should have them):
- A CloudQuery API key in order to run the sync without any limitations:
- A Catalog name and Schema name within Databricks where CloudQuery should sync the data:
- The necessary environment information to connect to Databricks:
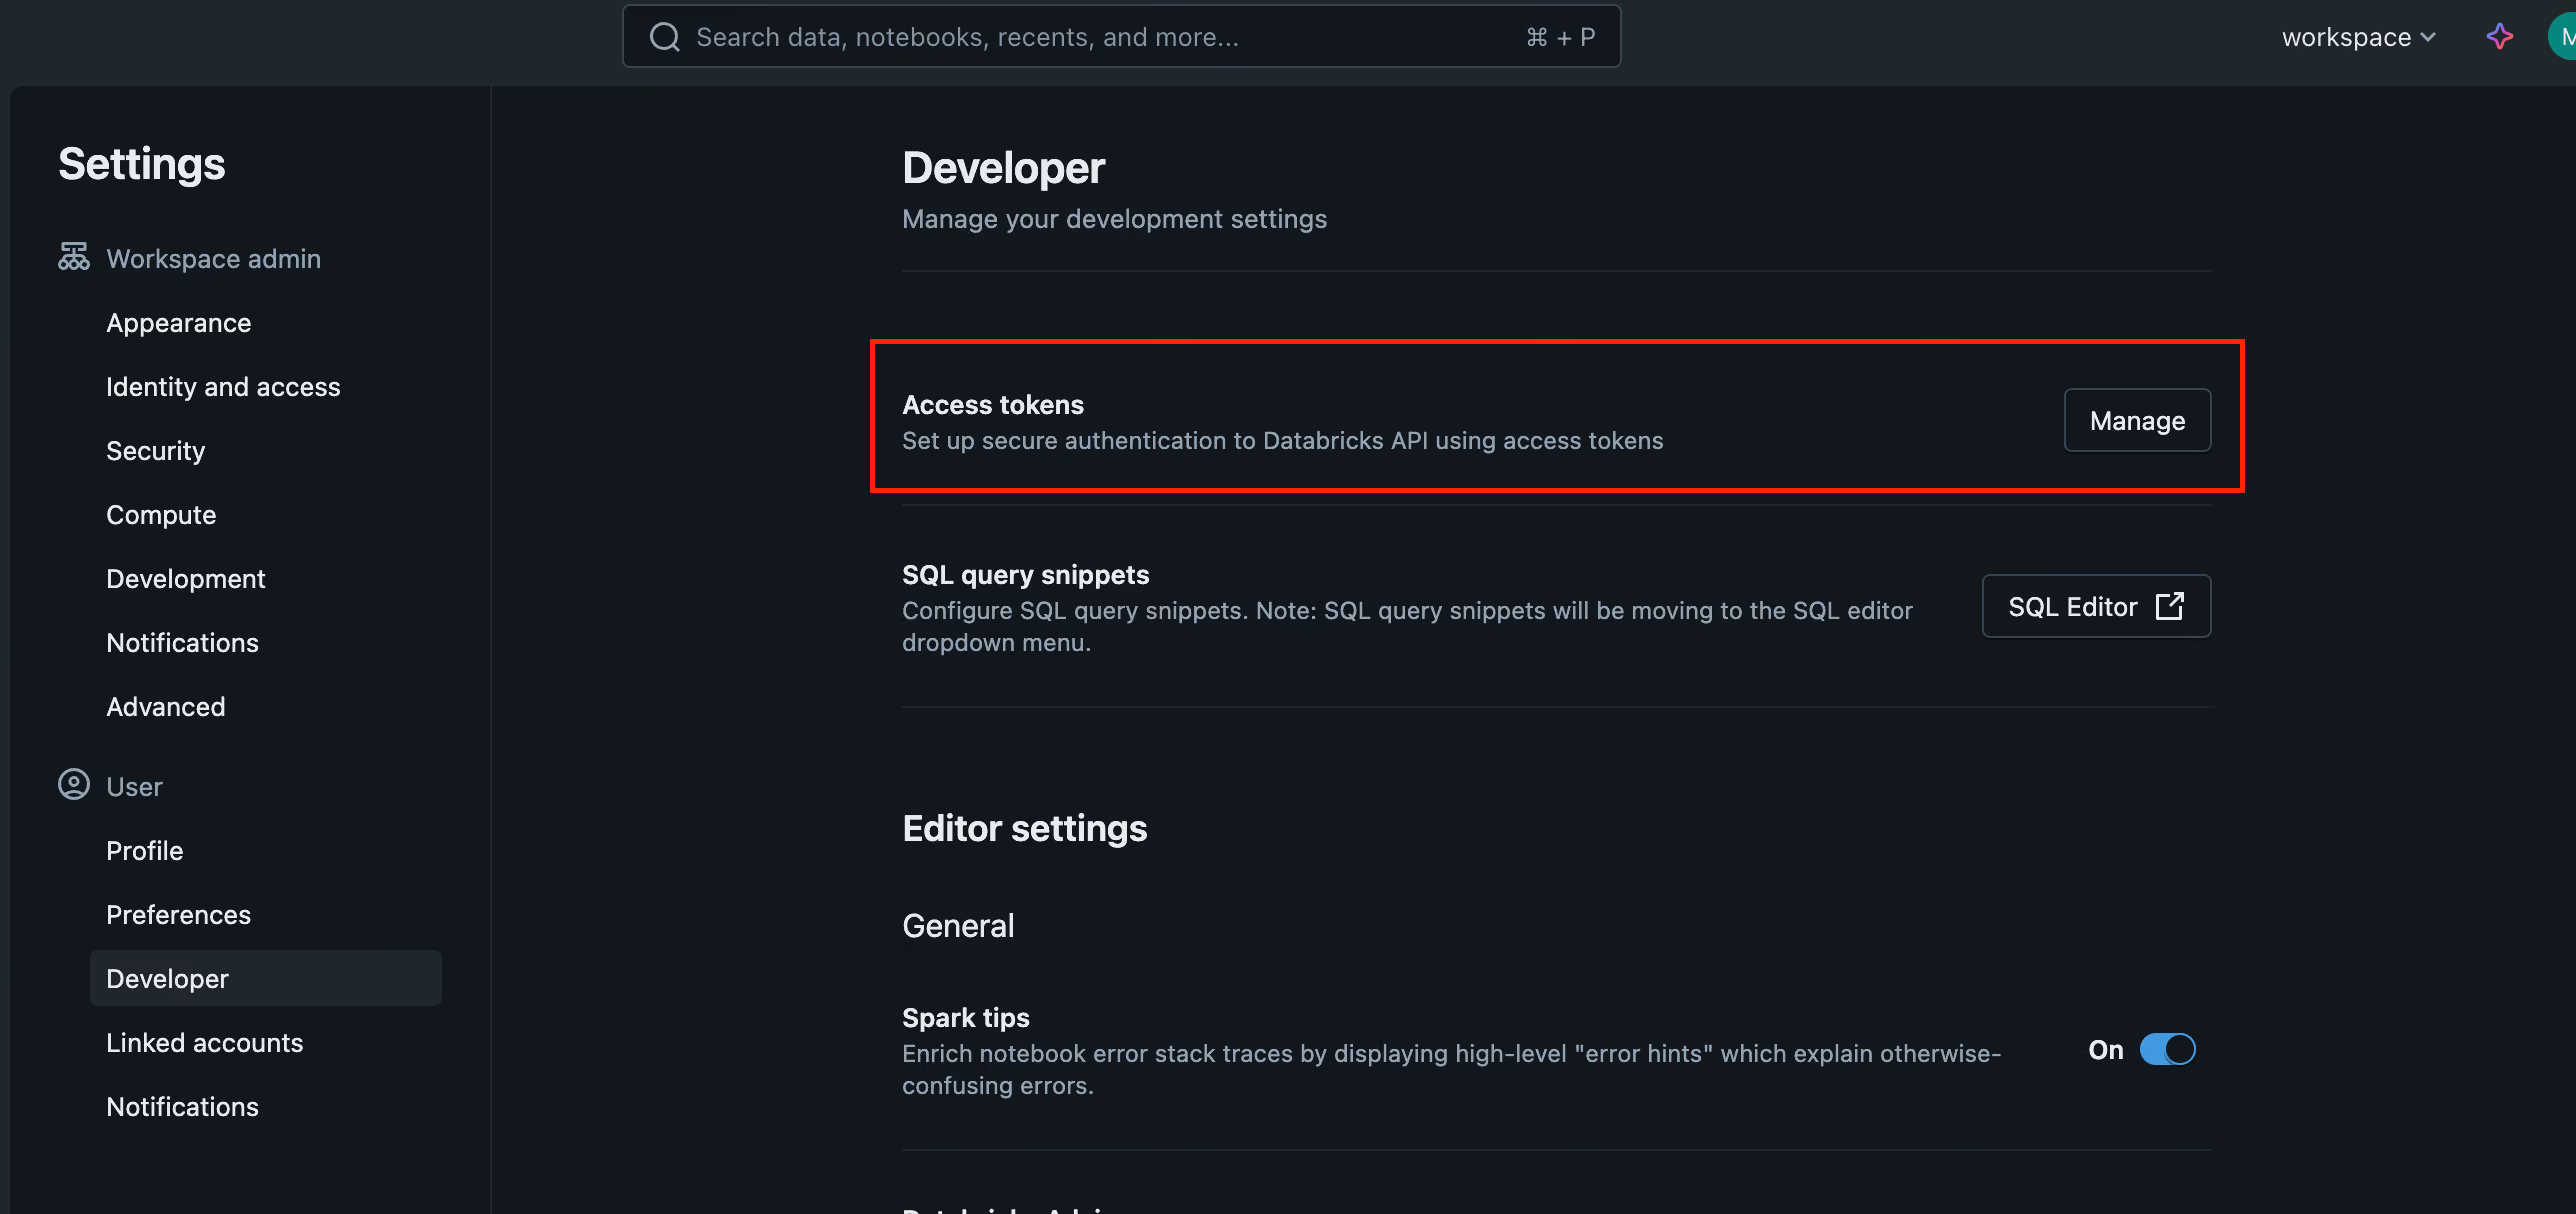
Create the Access Token by going to: Settings > Developer > Access Tokens > Manage
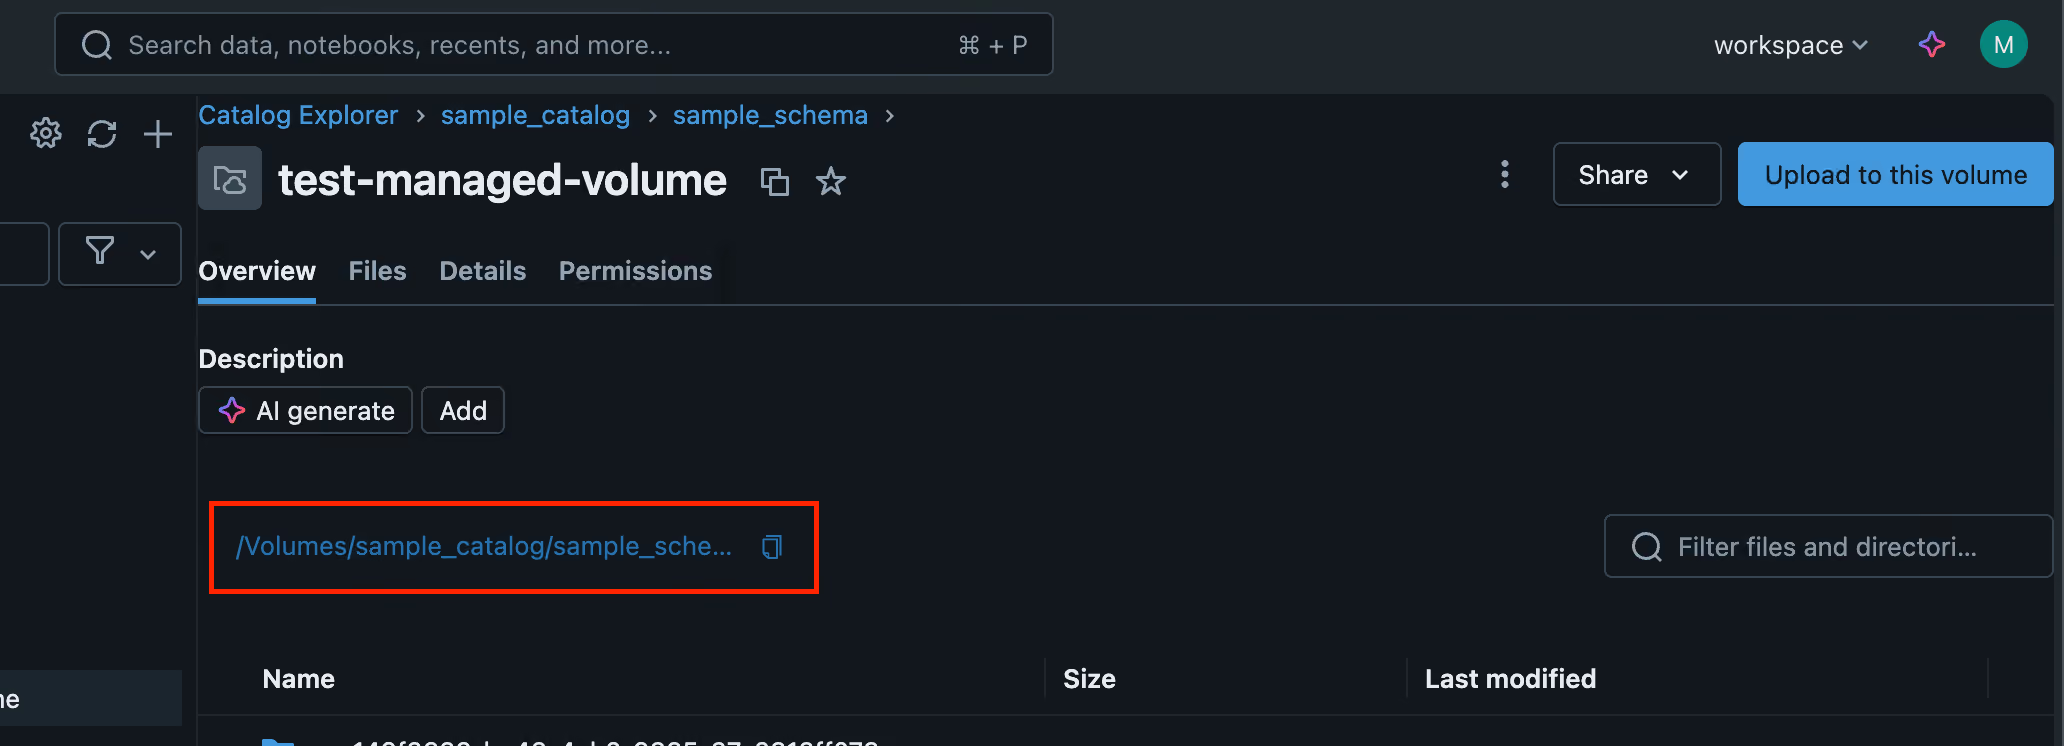
As the staging path, create a Volume within your catalog, copy its address and save it into the DATABRICKS_STAGING_PATH secret.
Running the sync
We'll be syncing AWS data using the CloudQuery CLI via a Databricks Job.
Create a new Job and configure it as a Python script; the code for this job is available at: https://github.com/cloudquery/databricks-simple-cli-job
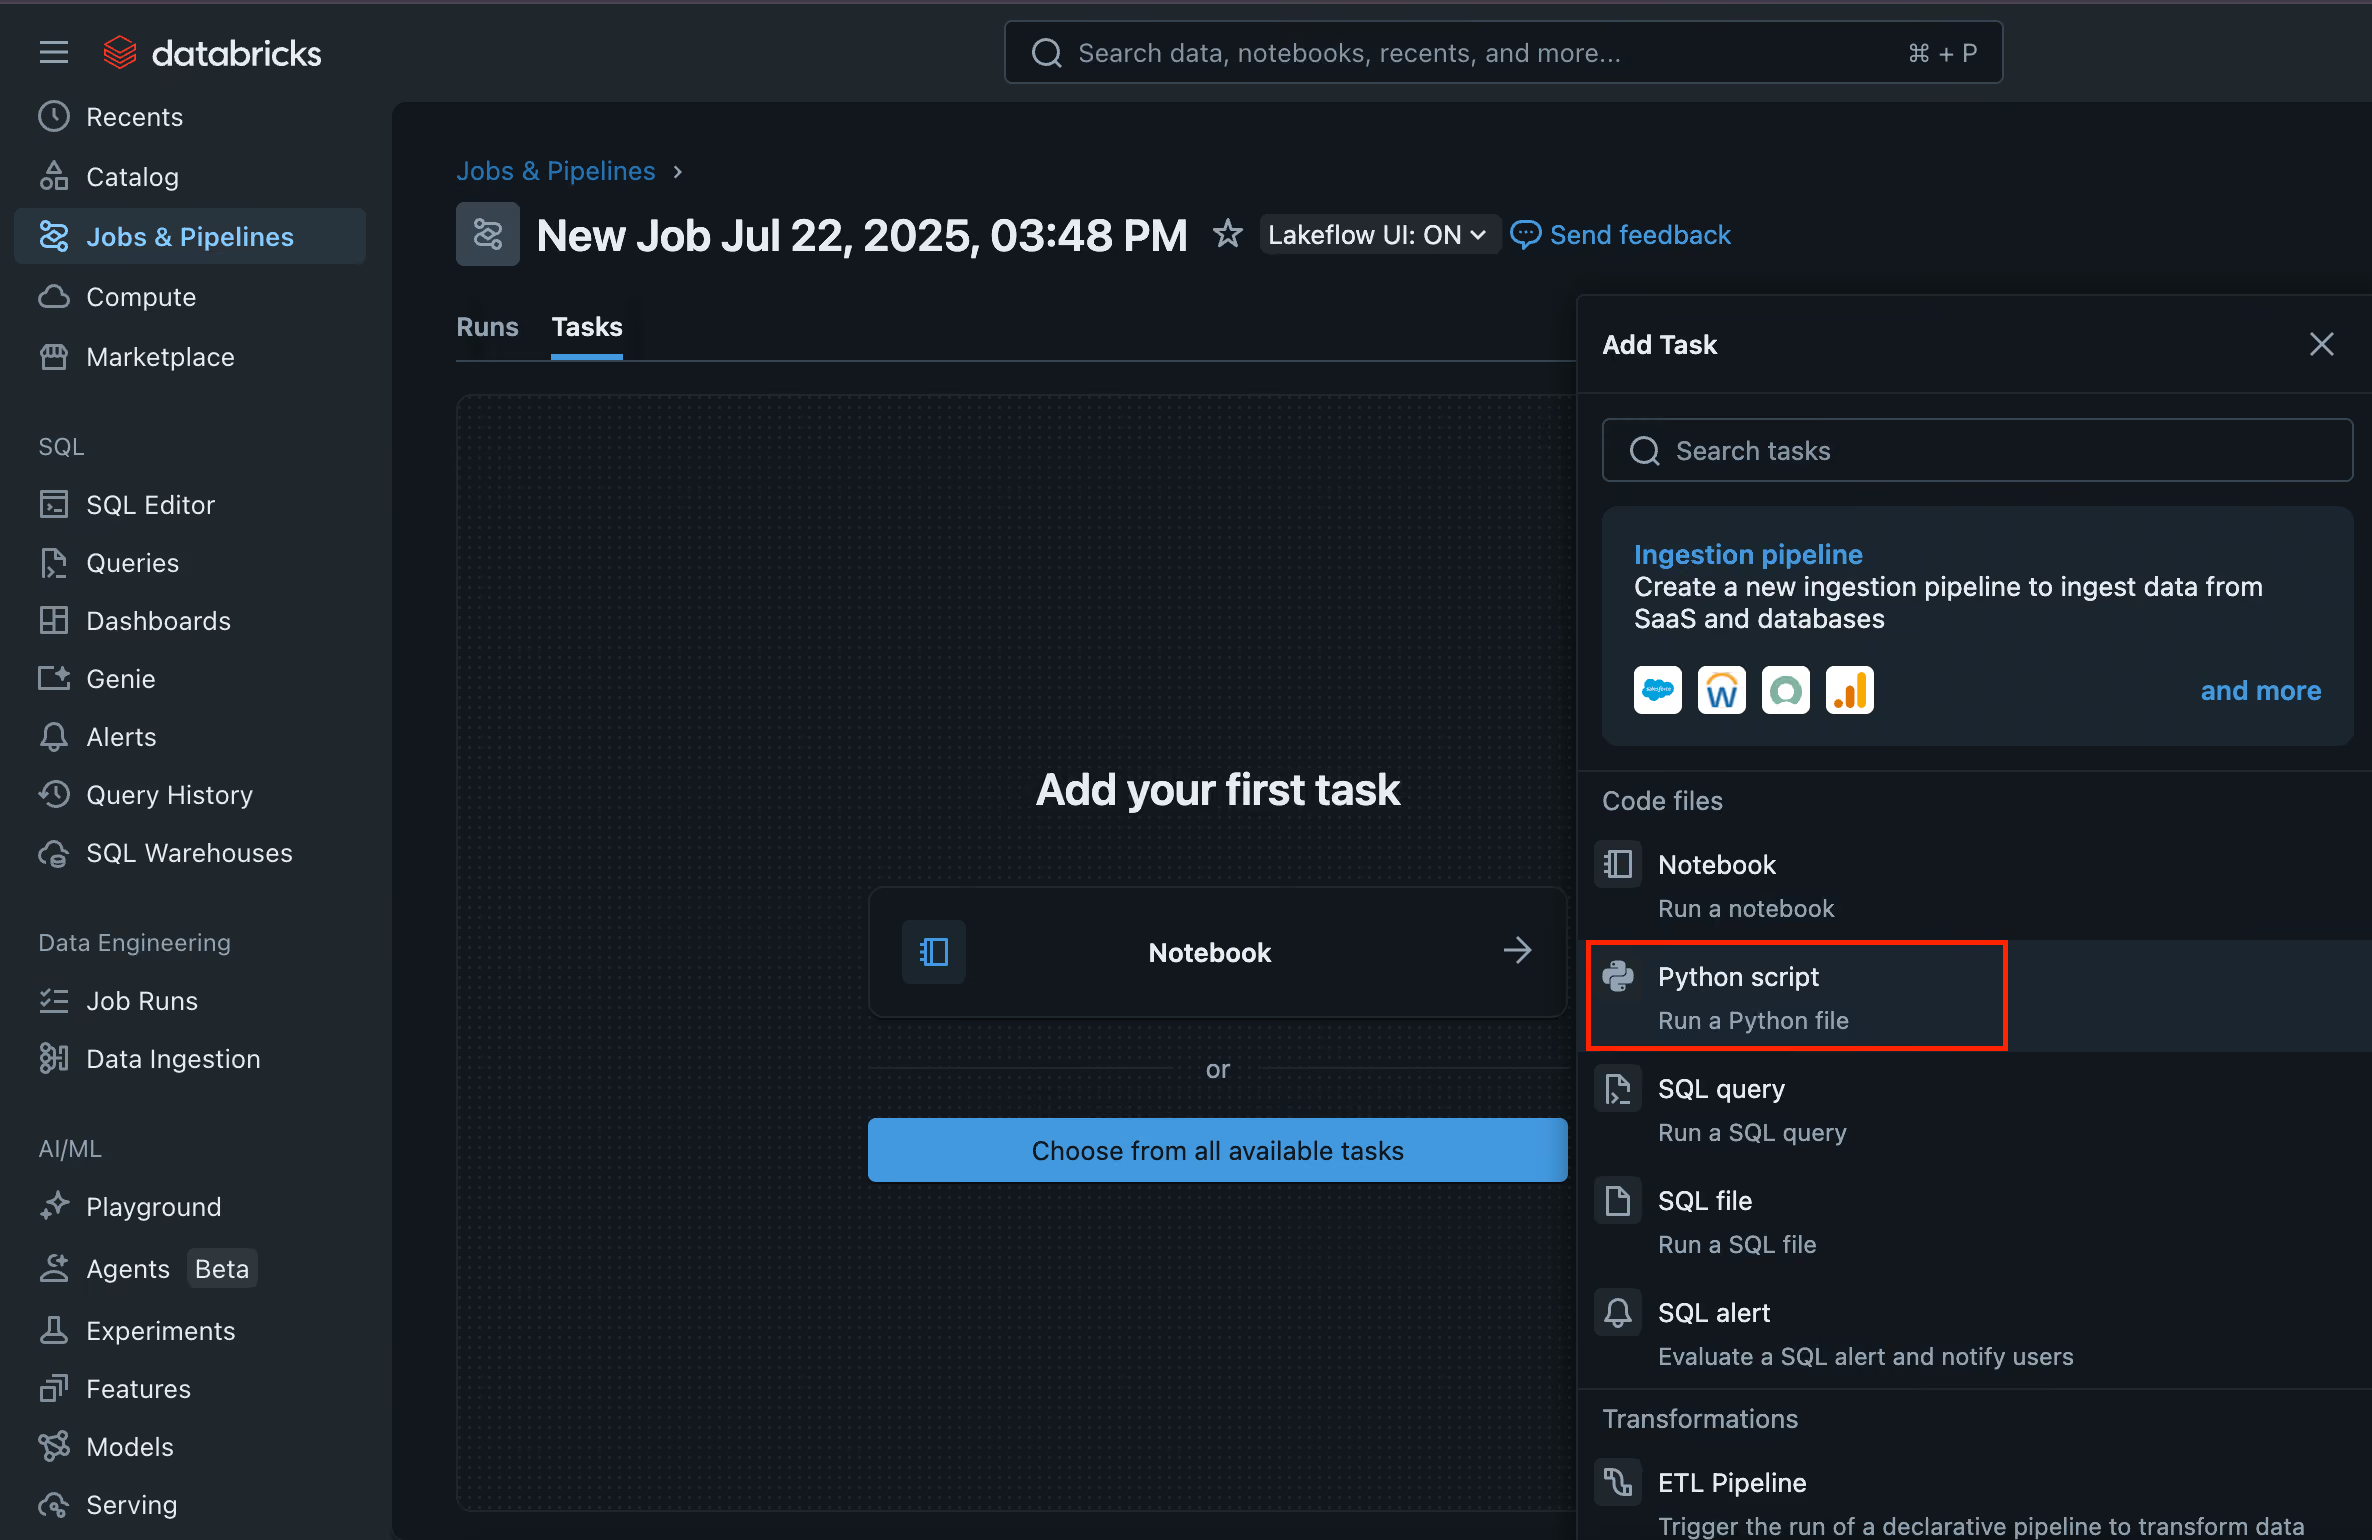
You can choose to fork the repository and use the Git provider source, or just copy the main.py code within the repository onto a file on your workspace and use that.
On the Environment and Libraries section, edit it to make sure to add the py-cloudquery==0.1.3 dependency (https://pypi.org/project/py-cloudquery/0.1.3/). This contains the CloudQuery CLI.
On the Parameters section, you'll need to provide the scope name you created earlier and a spec file for your sync (something like this for AWS: https://www.cloudquery.io/hub/plugins/source/cloudquery/aws/latest/docs#configuration-examples).
There's an example spec file on the repository: https://github.com/cloudquery/databricks-simple-cli-job/blob/main/aws_to_databricks.yaml.example
Note how the spec file is using the secrets you defined earlier. These will be converted into environment variables by the job as long as you set the scope argument properly, and then expanded by CloudQuery CLI automatically.
Create a spec file onto your Workspace based on the example provided and take note of its absolute address.
Your Parameters section should thus look something like this:
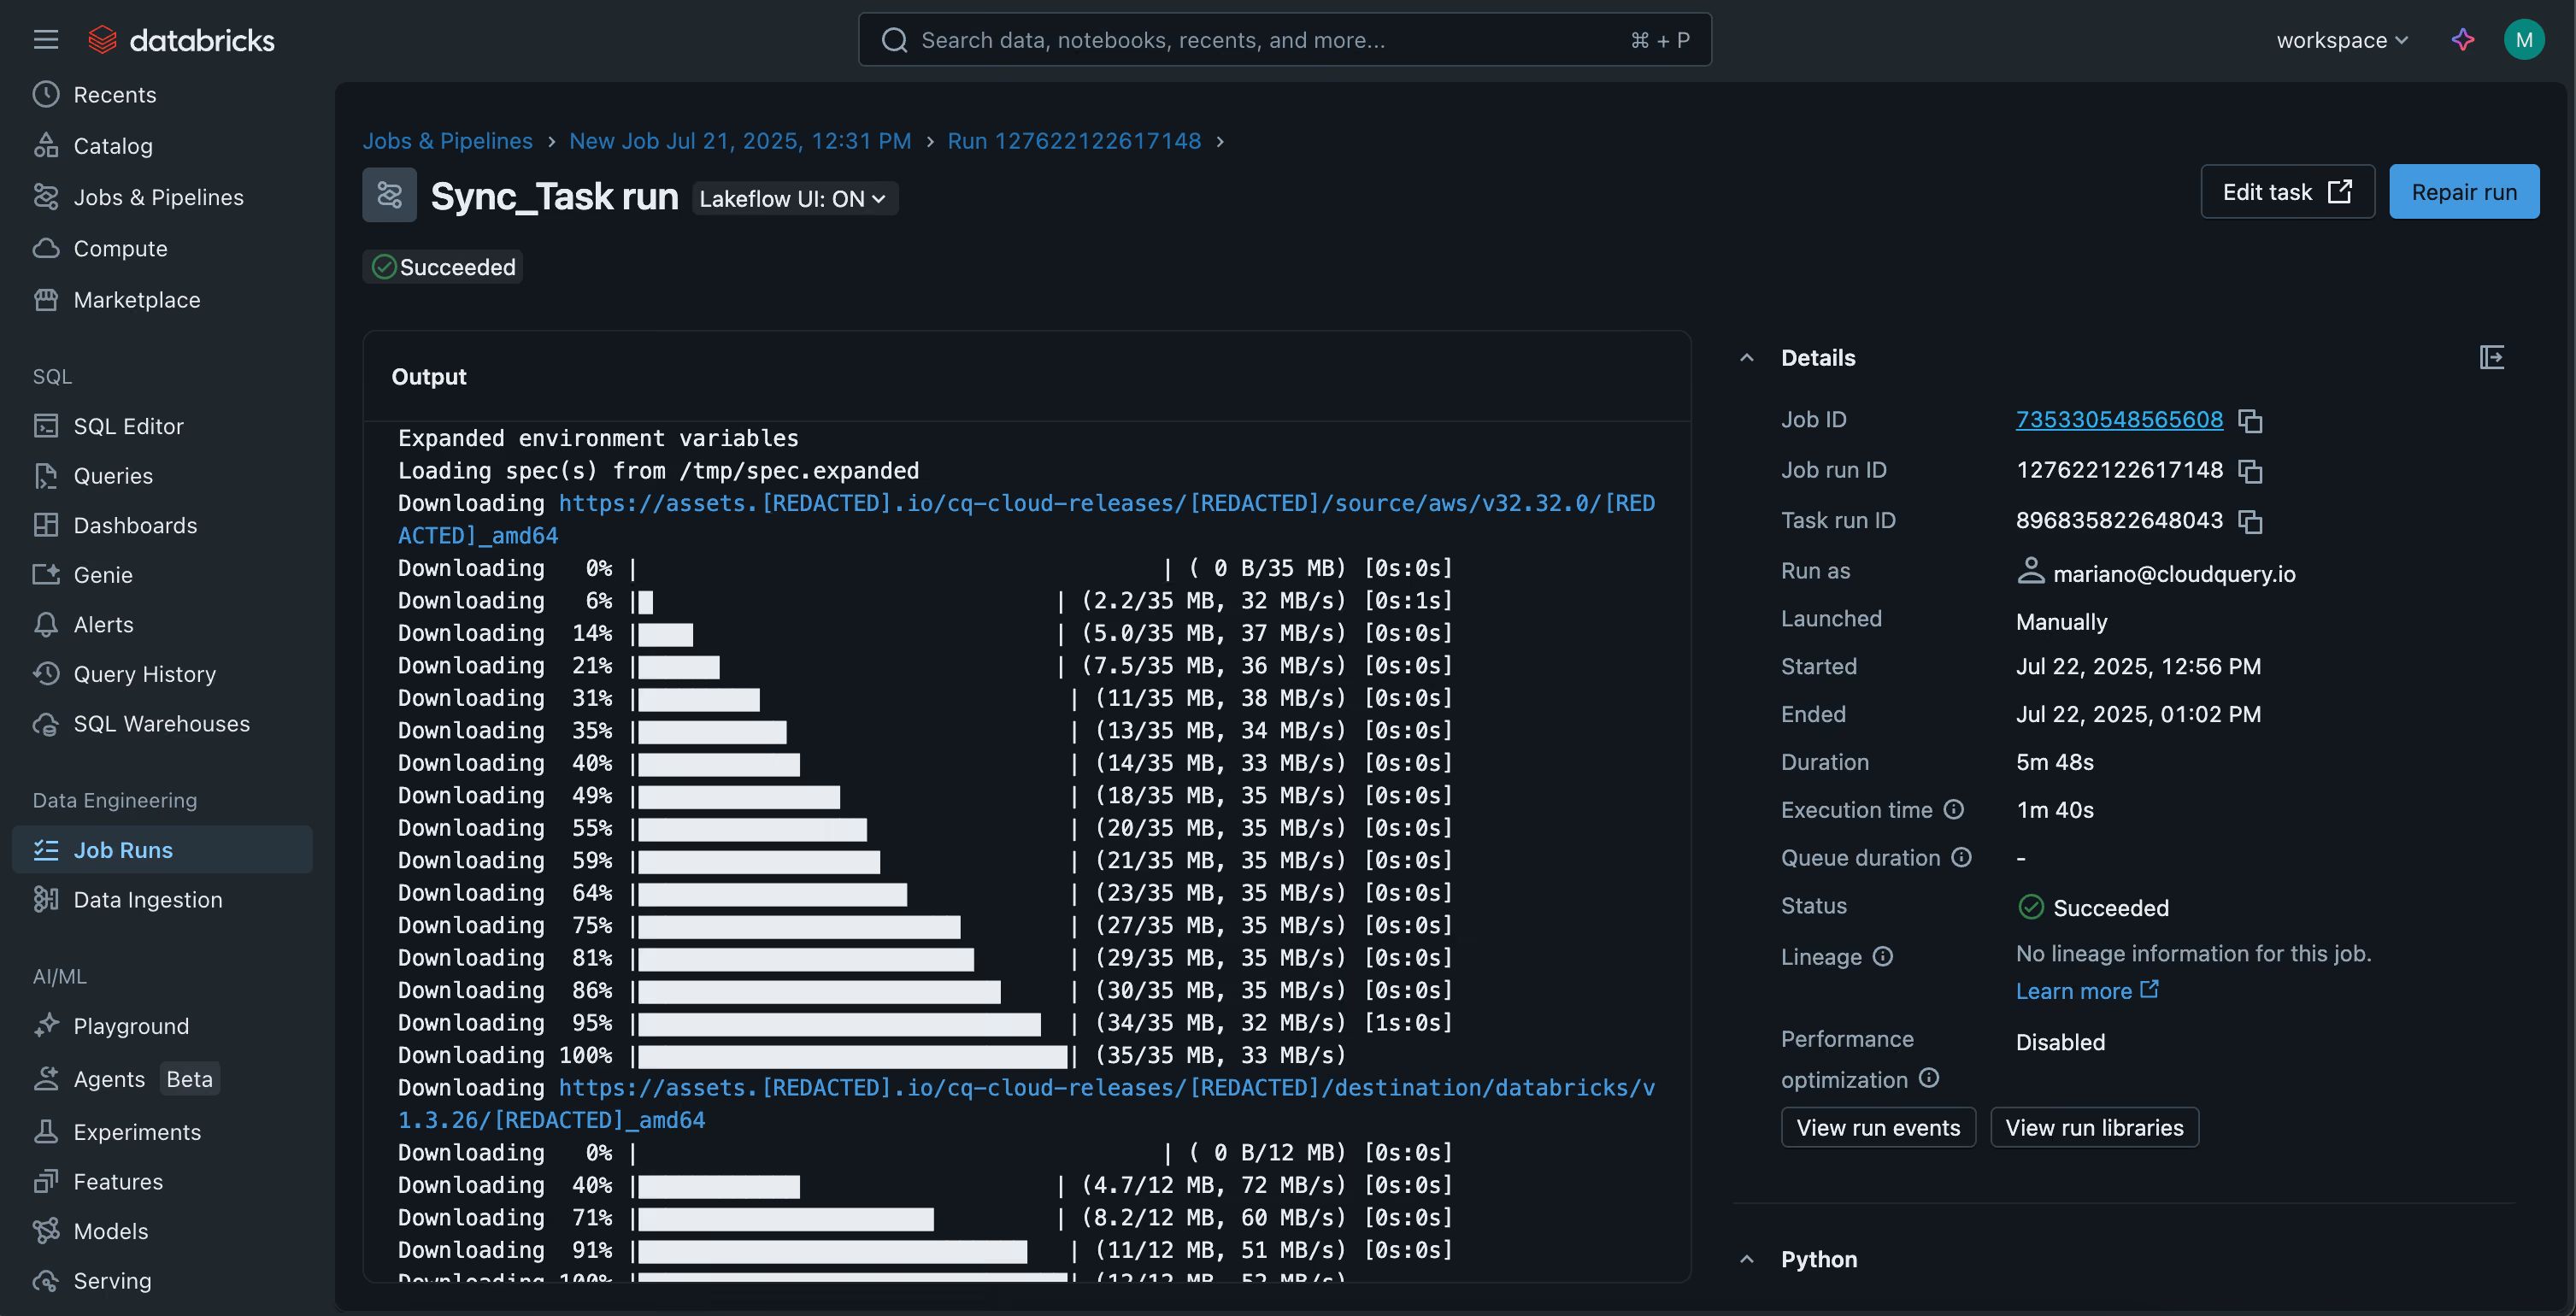
You should be able to run your job now. It should run the sync and succeed:
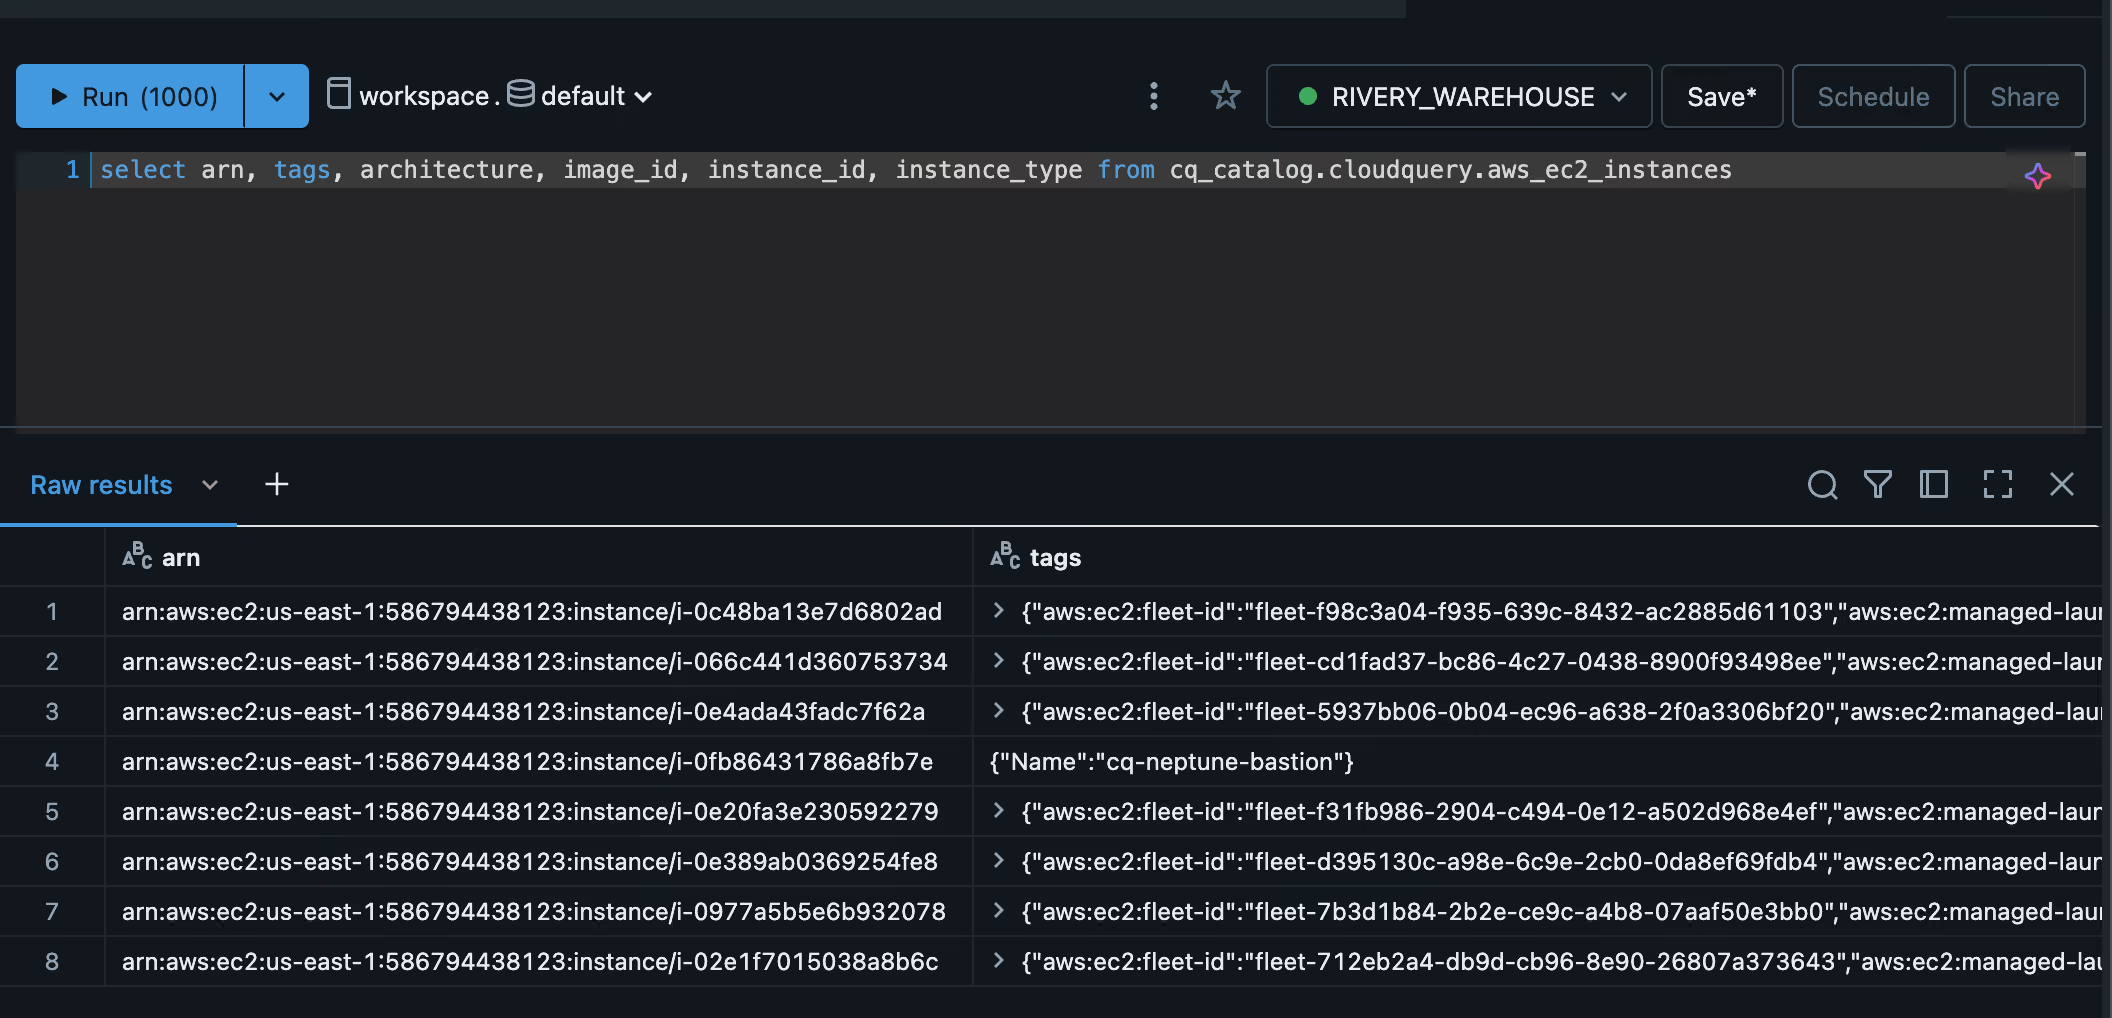
Optional: in order to validate that the sync worked properly, you can head over to the SQL editor and check the contents of the aws_ec2_instances table:
Transforming the data into a Cloud Asset Inventory
We'll use a different Job to transform the source sync data from AWS into a normalized Cloud Assets table that can be visualised later.
Note: this job is restricted to CloudQuery and Databricks users only, so the repository with the transformation code is private.
Create another Python-script-based job, and use this repository as source (fork it first so you're able to use it): https://github.com/cloudquery/databricks-sync-transformations
This code should already be set up to use the secrets you created for the sync, so there are no extra configuration steps. It should auto-detect your synced tables and construct a cloud_assets table from it.
There's no need to add special environments; only set the parameter that allows the job to know your secrets scope: ["--secrets-scope","default"]. You should be ready to run it straight after configuring the Git repository and it should succeed.
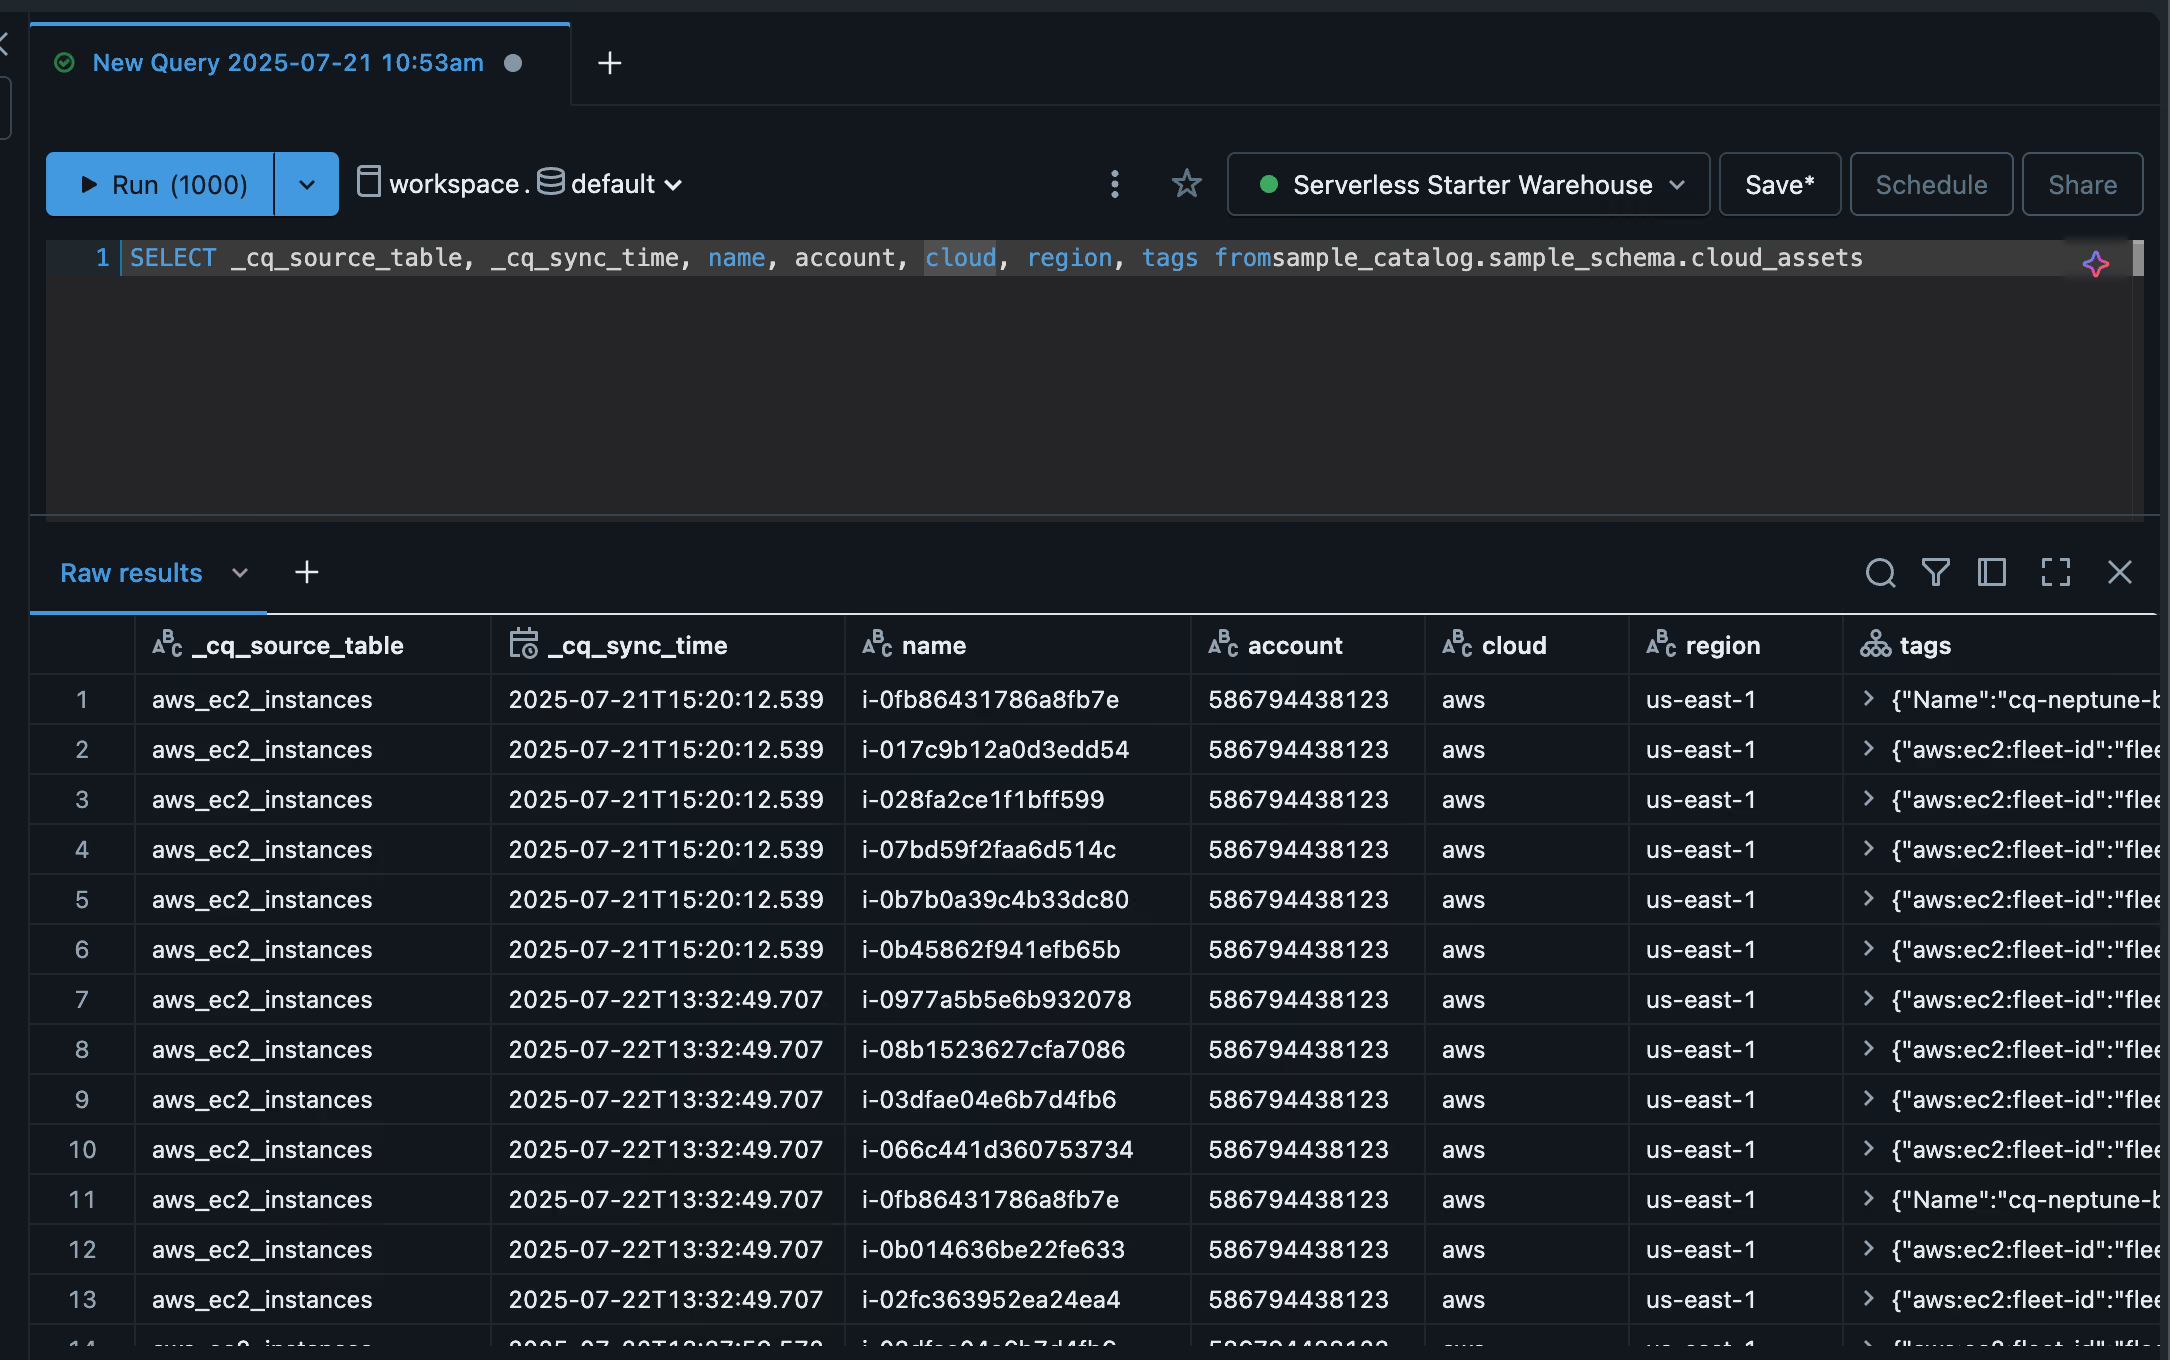
Optional: in order to validate that the transformation worked properly, you can head over to the SQL editor and check the contents of the cloud_assets table:
Visualising the Cloud Asset Inventory
We'll be using a NodeJS-based app to visualise the cloud_assets table.
Go to Compute > Apps and create a new app; let's call it hello-frontend.
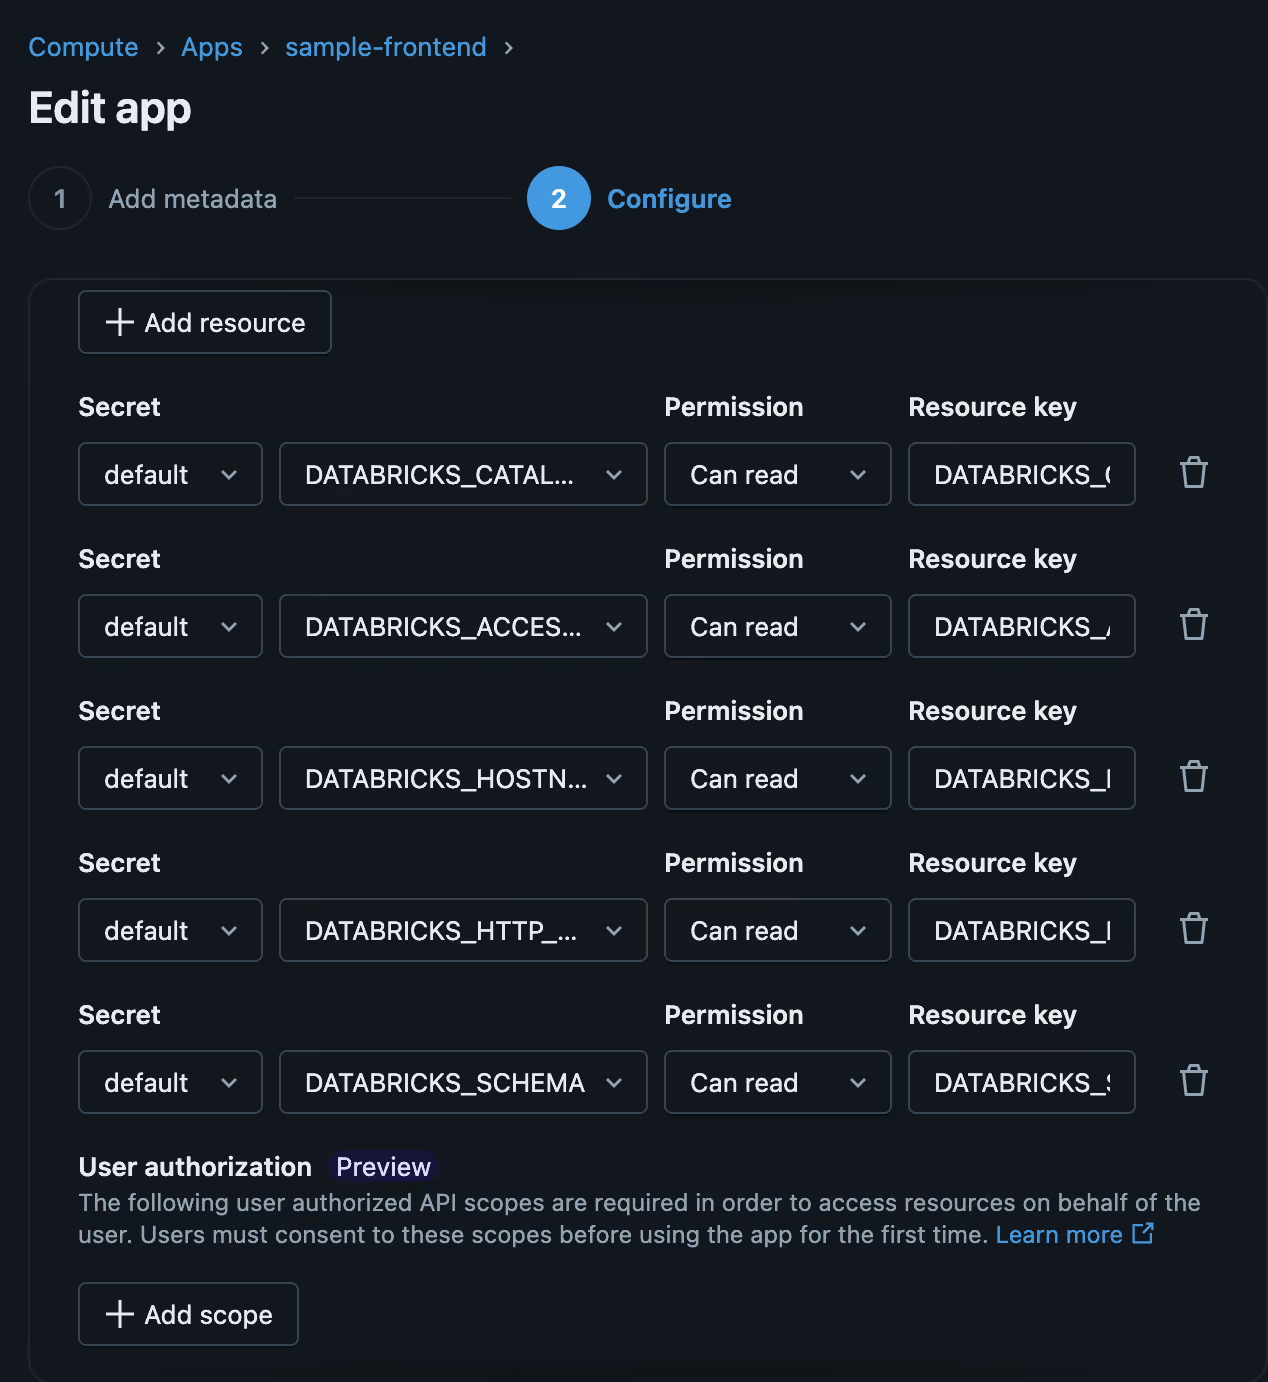
Apps are configured differently to Jobs. Our app will need to access the same secrets as the jobs, so edit the App configuration and make all the secrets available to it:
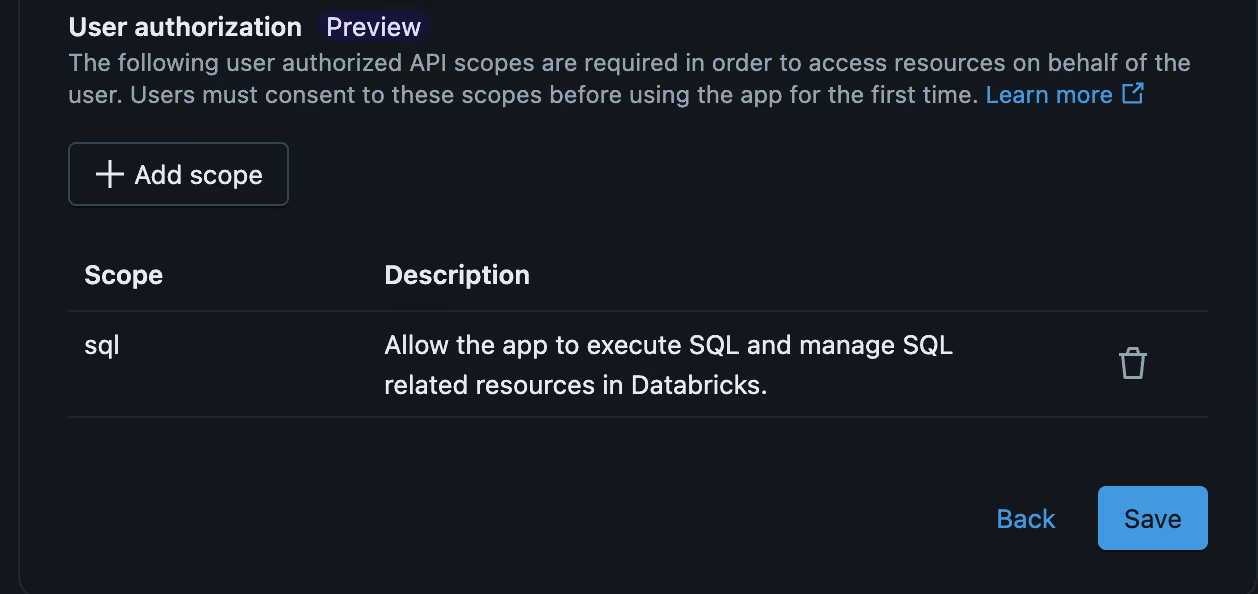
The App will also need to be able to run SQL queries against the Catalog, so enable that scope:
You can clone this repository and use it as source for your app: https://github.com/cloudquery/databricks-sample-app/
Then you should be able to just sync the contents of the folder into your workspace, and deploy it:
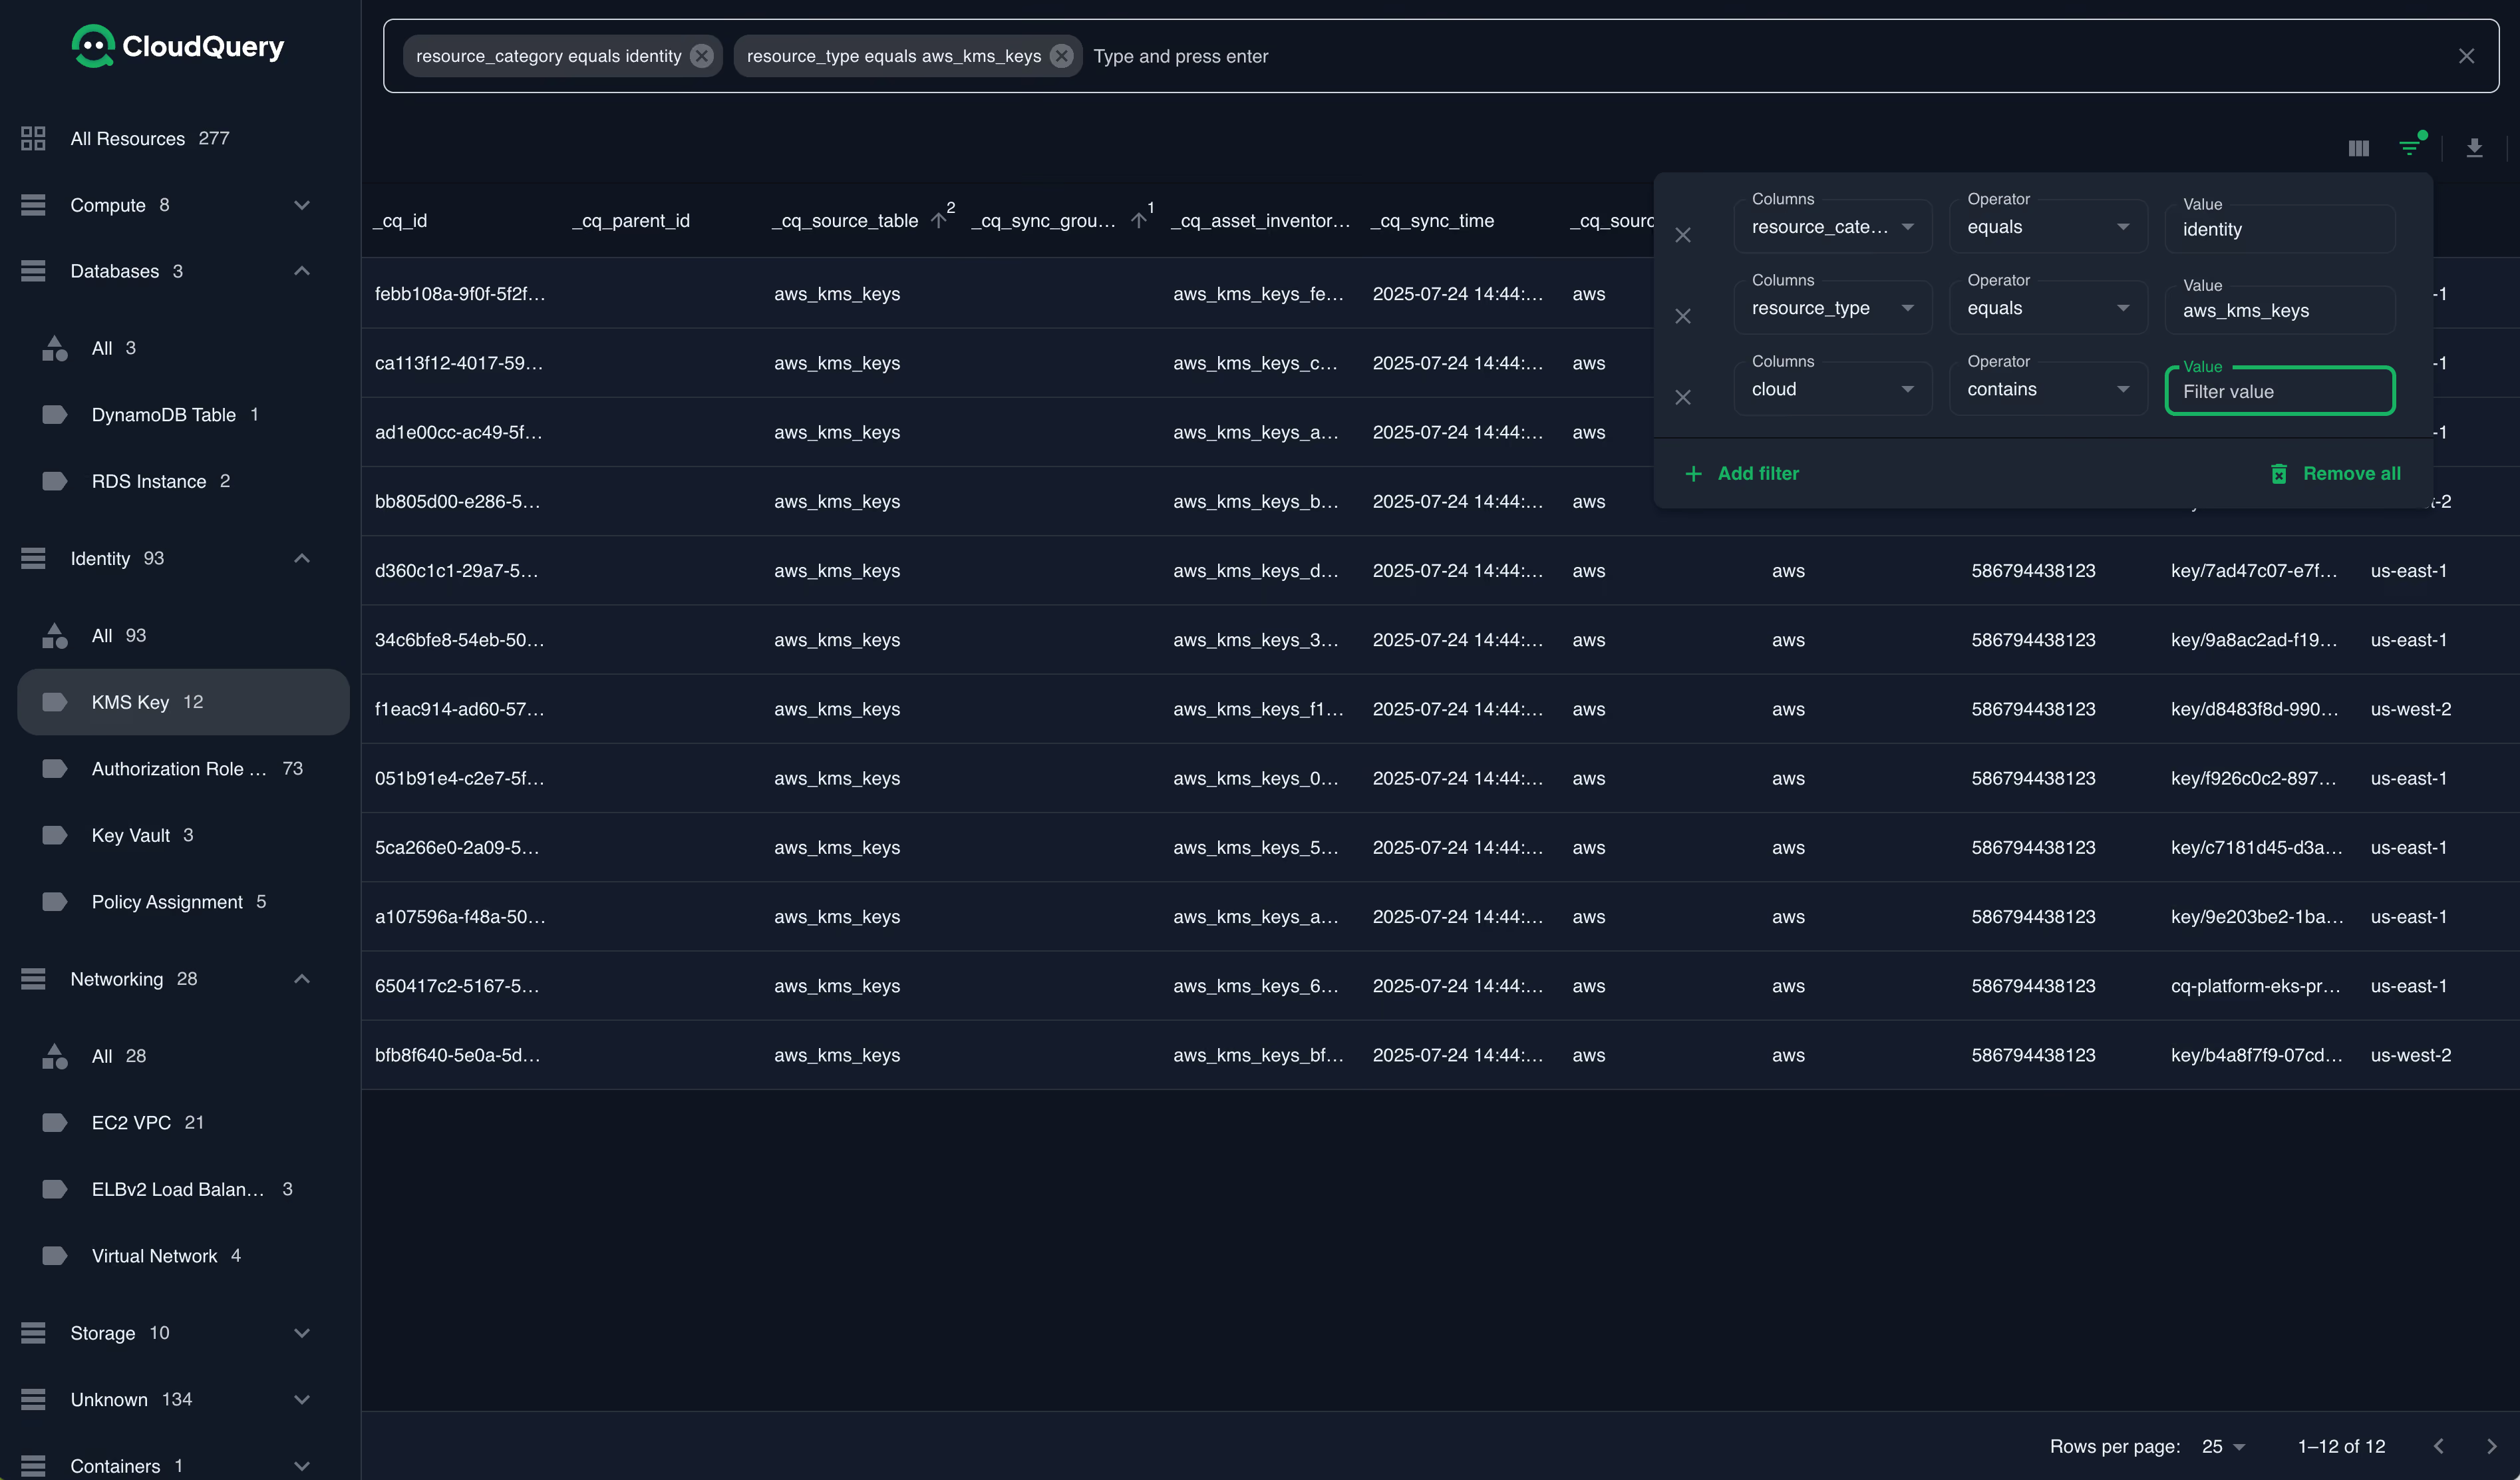
You should be able to start the app and browse your Asset Inventory 🎉
Enjoy!
Written by
Try CloudQuery yourself
Self-hosted, open source, and free to start. Or schedule a demo to see the managed version.