How we made our IDEs data-aware with a Go MCP Server
Most developers (and our own team) have been fully using AI code assistance to help with all aspects of building software. We have found that our AI-assisted IDEs know our functions, suggest completions, and help debug issues. However, their usefulness stopped dead at our database. AI assistants have zero understanding of what's actually in our tables, what queries make sense, or how your data connects together. This often results in hallucinations/bad data if you ever were to ask it a question about cloud infrastructure.
At CloudQuery, we've been running an experiment for months: what happens when you bridge that gap? We built an MCP server in Go (in fact, our entire stack runs on Go) that gives Claude or Cursor direct access to our cloud infrastructure database, and the results have fundamentally changed how our engineering team works.
This post covers what we learned about making LLMs truly data-aware, the technical gotchas nobody talks about, and why this pattern could transform how any team with substantial data operates.
We noticed something…
We noticed something frustrating: our engineers (and users) were constantly switching between an AI assistant for code analysis and our platform for actual data queries.
The workflow looked like this:
- Claude/Cursor helps us write Go code for infrastructure analysis
- Engineer switches to CloudQuery to understand available tables
- Copy-paste table schemas back to Claude
- Manually explain column meanings and relationships
- Write more SQL queries, debug them separately
- Go back to Claude with the results for further analysis
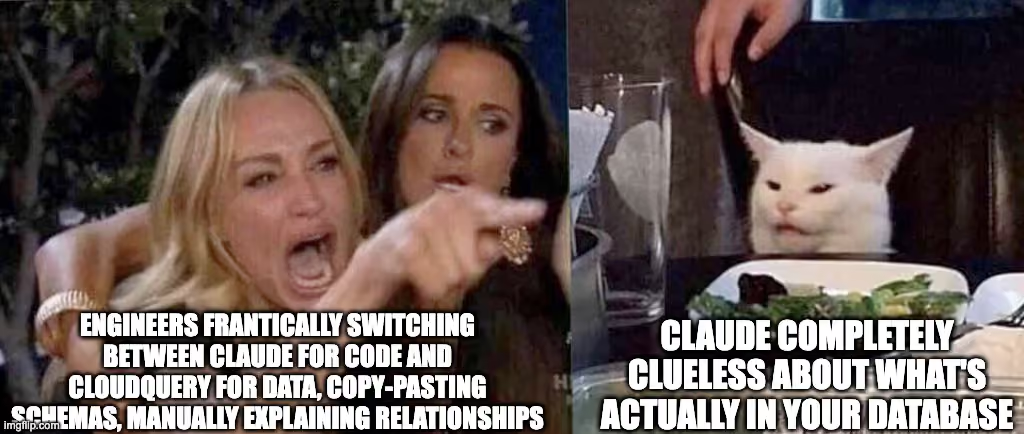
We realized: What if AI Assistants could directly explore our data layer?
By building an MCP server that exposes our database schemas, query capabilities, and data insights directly to your AI Assistant, we bridged this gap. Now Claude/Cursor/whatever doesn't just know our Go code - it knows our actual cloud infrastructure data.
What We Built
When Anthropic dropped the Model Context Protocol in November with SDKs for Python, TypeScript, Java, and Kotlin, but not Go, we had a problem. But also an opportunity.
We built our MCP server specifically to expose our data layer to Claude. We're using the mark3labs/mcp-go library since Anthropic doesn't have an official Go SDK yet (though they're working on it).
Here's what a bare bones MCP server looks like:
We created six specific tools that give your AI Assistant complete access to our data layer:
Data Discovery Tools:
list_installed_plugins- Shows what cloud providers and services are availabletable_search_regex- Finds tables using pattern matching across all data sourcestable_schemas- Retrieves detailed schema information for specific tables
Data Analysis Tools:
column_search- Locates specific fields across all tables (finding "tag" columns across different cloud providers)execute_clickhouse_sql_query- Runs analytical queries against our ClickHouse clusterknown_good_queries- Provides working SQL examples for common infrastructure analysis
Each tool is designed around data exploration workflows rather than just exposing database operations. When your AI Assistant needs to understand our AWS security groups, it can now:
- Discover that the AWS integration exists and is syncing data
- Search for security-related tables
- Retrieve the
aws_ec2_security_groupsschema - Execute queries to find groups allowing port 22 access
- Cross-reference with instance data to assess actual risk
Coding when the LLM Knows Your Data
The transformation in our engineering workflow has been dramatic. Here are specific examples of how bridging the code-data gap changed our day-to-day operations:
Infrastructure Troubleshooting
Before MCP server: We suspected our CloudQuery sync wasn't converging properly. Resources would appear, disappear, then reappear in our database. To investigate required:
- SSH into our server cluster
- Write complex SQL queries joining sync metadata tables
- Analyze patterns across multiple time windows
- Cross-reference with CloudQuery's internal state tables
- Document findings for the team
Total time: 2-3 hours, requiring deep SQL knowledge.
After MCP server: “Check if our asset sync data is converging properly for the production AWS account."
Claude uses our MCP tools to:
- Query sync run metadata across time windows
- Analyze resource count patterns and state transitions
- Cross-reference with expected AWS API responses
- Generate a comprehensive convergence report
Security Analysis
Our security team regularly needs to audit cloud configurations. Previously, this meant:
- Engineer receives security question about EC2 instances
- Manually explores CloudQuery tables to understand schema
- Writes queries to find relevant security groups, NACLs, instances
- Cross-references data across multiple tables
- Formats findings for security team
Now: "Audit our production AWS environment for instances with overly permissive security groups."

Your AI Assistant automatically:
- Explores EC2 instance and security group tables
- Identifies problematic configurations
- Cross-references with actual instance usage
- Provides remediation priorities
The security team gets actionable insights instead of raw data dumps.
Final Thoughts
By giving Claude/Cursor direct access to our data layer through structured tools, we've created something genuinely new: an AI assistant that understands both our code AND our data.

This pattern isn't specific to CloudQuery. Any team with substantial databases could benefit from this approach:
- E-commerce teams: AI Assistants could explore user behavior tables, understand purchase patterns, and suggest optimizations
- SaaS companies: Expose usage analytics, feature adoption data, and customer segments
- Financial services: Bridge the gap between trading algorithms and market data
- Healthcare platforms: Connect clinical code with patient data insights (with proper privacy controls)
The productivity gains compound when your AI assistant has full context of both code and data layers.
The Bigger Picture
Building an MCP server taught me more about how LLMs actually work than months of reading papers. When you watch your AI assistants make decisions about data exploration, tool selection, and query optimization, you start understanding the practical potential of AI-assisted development.
The code-data bridge we built isn't just a productivity hack. It's a preview of how software development changes when your AI assistant has full context of both your code and your data.
I'd argue 99.99% of developers haven't thought of this pattern yet. But exposing your data layer to LLMs through MCP servers genuinely supercharges what's possible with AI-assisted development. The barrier between "I have a question about our data" and "I have a comprehensive answer" basically disappears.
That changes everything.
Written by
Try CloudQuery yourself
Self-hosted, open source, and free to start. Or schedule a demo to see the managed version.