If you're like most engineering teams building a Cloud Asset Inventory, you've hit this wall: your cloud resources live in one place, but all the context around them (who owns what, how much things cost, what's scheduled for deletion) lives somewhere else.
Let's be real, we've all built janky workarounds:
- Exporting to CSV and doing VLOOKUPS in spreadsheets 🤢
- Writing custom scripts to join data across systems
- Making everyone memorize naming conventions (that no one follows)
Custom Columns fixes this by letting you put any data you want right alongside your cloud asset inventory in CloudQuery.
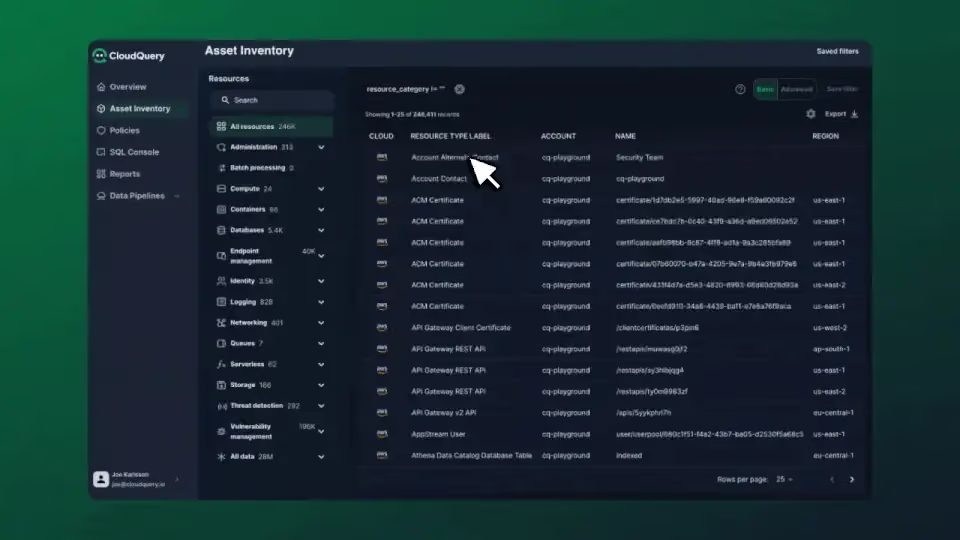
Custom Columns help you surface critical information right next to your cloud assets. Instead of jumping between tools, you can now see it all in one place at a glance:
- Which team or project does each resource belong to.
- How individual cloud resources contribute to your overall cloud budget.
- Security and compliance status from external scanners.
- Custom lifecycle information, like scheduled deletion dates.
- Any other metadata that matters to your organization.
According to cloud management best practices, tagging and metadata enrichment are essential for optimizing cloud asset visibility by implementing a robust tagging strategy for your cloud resources. Yet many organizations struggle with inconsistent tags across cloud providers. Custom Columns solves this by giving you a consistent layer for business context that works across your entire infrastructure.
Custom Columns does two simple things:
- Let's you define new columns in your Cloud Asset Inventory.
- Gives you ways to populate those columns (UI or API).
Creating a Custom Column from Tags
In the UI, here’s how you can create custom columns from your existing tags.
Now you have a new custom "Team" column that surfaces the name of the team associated with the cloud resource. This custom column doesn't just display information, it also becomes a filter in your asset inventory. You can filter by team name to find all resources owned by a specific team.
Additionally, custom columns are fully queryable via SQL in the console, allowing you to create reports or dashboards that incorporate your custom data alongside native cloud resource information. This dramatically simplifies both everyday browsing and advanced analysis of your cloud assets.
The Real Power: Custom Columns API
The UI is nice, but the real power comes from automating column updates through the API. Let's walk through adding cost data from your FinOps tool.
First, create the column:
Now, here's a script that could run daily to sync cost data:
Run this as a cron job, and boom - you've got cost data right next to all of your cloud asset data in CloudQuery.
What People Are Doing With This
Some cool things we've seen early users build:
- A script that pulls Datadog monitor data into CloudQuery to show which instances keep having alerts.
- A column that converts inconsistent environment tags (
prod,production,PROD) into a normalizedenvironmentfield. - A custom security score calculated from internal vulnerability scanners.
- A "scheduled deletion" column for instances flagged for cleanup.
Try It Out
Custom Columns are ready to use now. Check out our documentation and our API docs for the full reference on integrating CloudQuery custom columns into your Cloud Asset Inventory.
Got questions or cool use cases? Hit us up in the community forum, we'd love to see what you build with this.
About CloudQuery
CloudQuery is a developer-first cloud governance platform designed to provide security, compliance, and FinOps teams complete visibility into their cloud assets. By leveraging SQL-driven flexibility, CloudQuery enables you to easily query, automate, and optimize your cloud infrastructure's security posture, compliance requirements, and operational costs at scale. The central configuration store pattern we've described is just one example of how we've engineered our platform to handle enterprise-scale data volumes.
Ready to see how CloudQuery can transform your cloud visibility? Our team can walk you through a tailored demo based on your cloud environment and use cases. Let's talk about how CloudQuery can fit into your stack. Schedule a demo today.
For more information on how CloudQuery can help with your specific use case, check out our documentation or join our community.
Written by
Try CloudQuery yourself
Self-hosted, open source, and free to start. Or schedule a demo to see the managed version.