In this blog, we will share why we started CloudQuery as an open-source cloud asset inventory, as well as some of our product and technical decisions along the way.
CloudQuery: Backstory
Before I jump into the technical and product discussion, I want to give a personal context: As someone who has been in the security industry for more than a decade,
working for, running enterprise security companies and seeing many founded during the last couple of years. One thing always made my stomach hurt: The "Get a Demo" button
(Maybe because I'm a millennial or just because the industry didn't move fast enough).
I was looking for alternative solutions, potentially dev-first or even better open-source so I can engineer around them, but couldn't find any.
To validate that I'm not missing something nor I'm the only one asking for that, I've released the first CloudQuery version early 2021 and it started to gain traction pretty quick.
This is where we decided to double down on the opportunity, raise money, build the team and embark on this journey.
Now, I'll share some of our thought process and how we've built and designed CloudQuery and why we think open-source
is the right way to solve some of the fundamental challenges in the cloud.
CloudQuery: The Origins
First, let’s look at the following simplified cloud management market landscape.
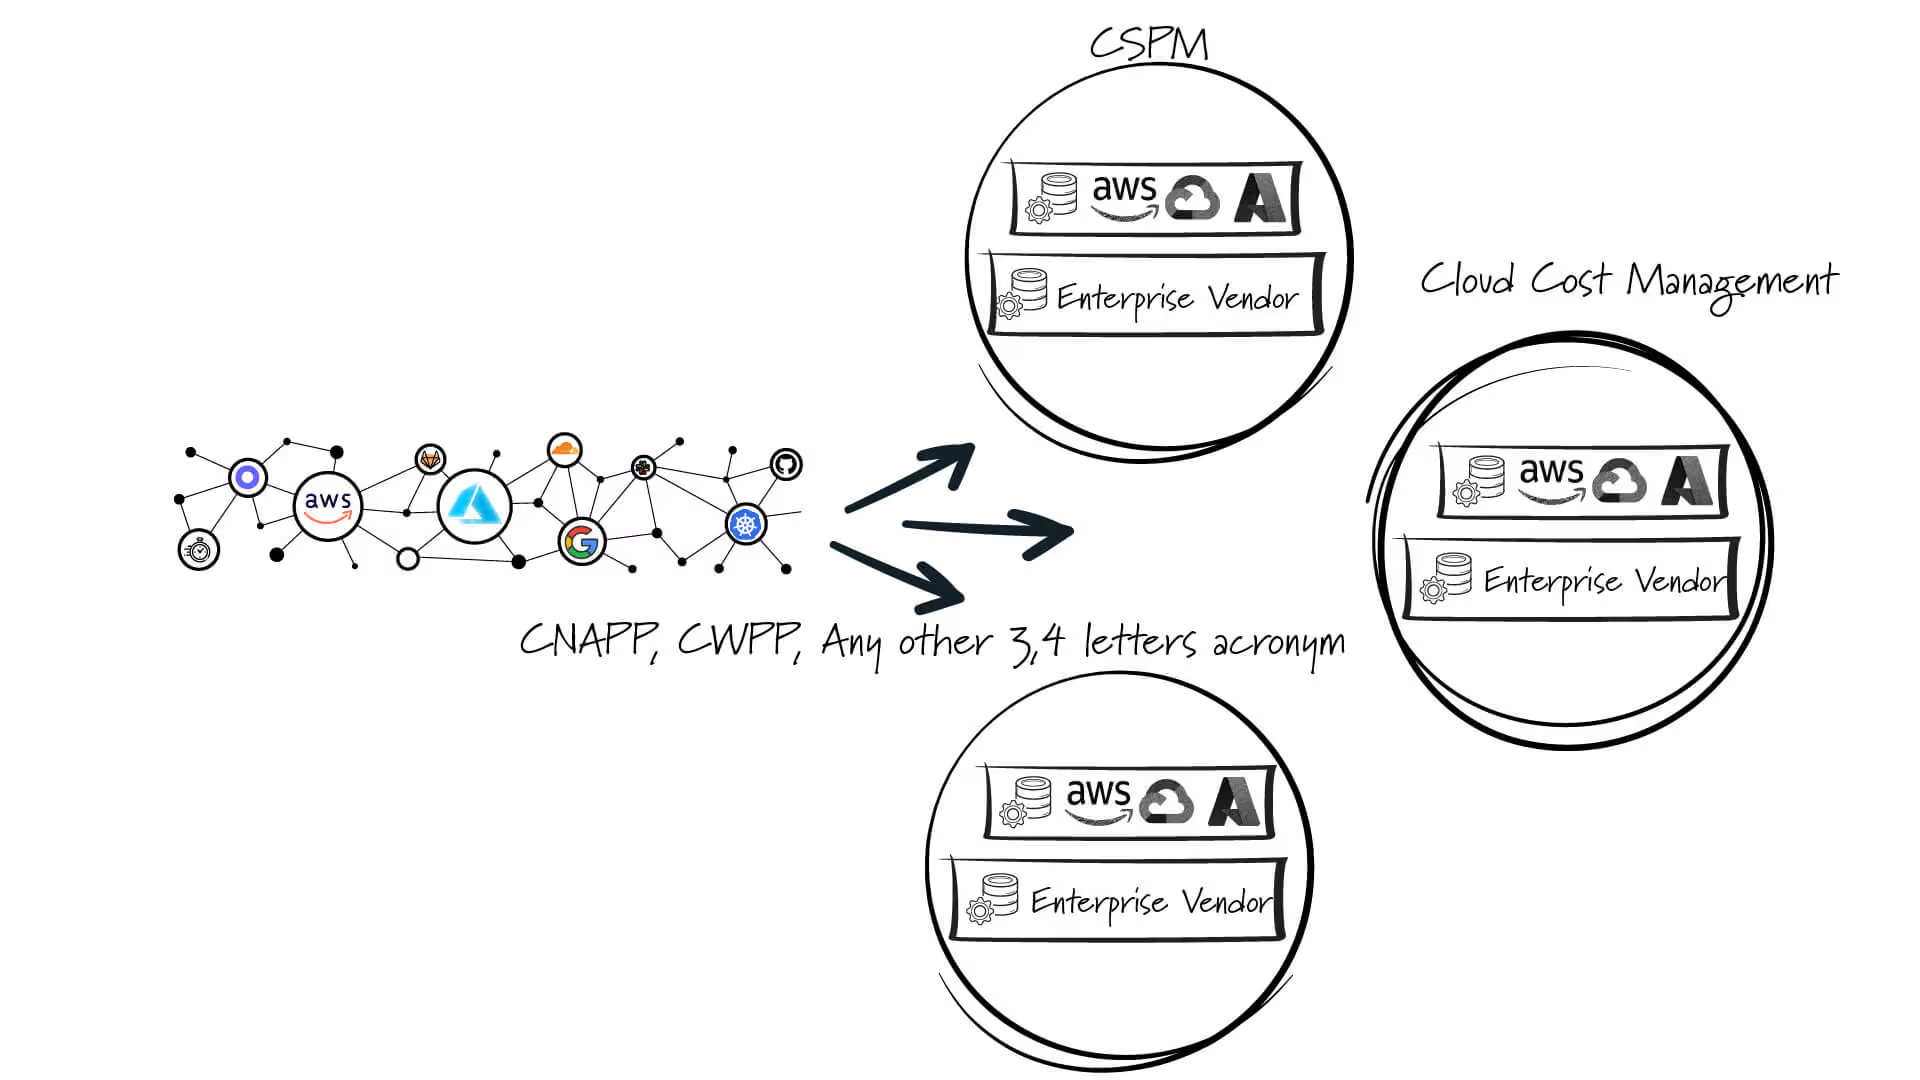
- We've split the vendors to 1) cloud vendors and 2) enterprise vendors (we didn't use logos/names to avoid law suits and so on but there are plenty)
This landscape can be quite confusing as the number of acronyms, vendors, and solutions just keep growing, so for simplicity, I've scribbled just 3 circles: CSPM, Cost, and another for all other acronyms.
Before we embarked on our open-source journey, we were looking at this landscape and tried to understand: Why are there so many vendors? Why are more popping up? Why are more acronyms popping up? What is the root cause for that?
If we throw for a second all confusing acronyms out the window and define in layman's terms what we want to achieve as SREs, Security Engineers, or DevOps, we can say the following: "I want to ask questions, get answers and then enforce/monitor some of those answers based on what I have in my Cloud/SaaS infrastructure".
Translating this to technical, product terms, it means we need an up-to-date database with all the information/configuration (asset inventory) to be able to ask questions.
This means we need a performant, up-to-date ETL (Extract, Transform, Load) engine with a wide variety of integrations - with good breadth (support for many different cloud/service providers) and depth (comprehensive coverage for every cloud provider's features).
And then we got our aha moment!
- ETL engine: Every vendor is implementing its own closed-source ETL engine with limited breadth and depth of integrations, and no way for users to add their own. When one vendor is missing a new integration or API, a new acronym and company pop up - for example, SSPM (SaaS integration).
- Custom query language: Vendors use custom query languages that provide limited power, high-learning curve and lock-in to a specific type of database. When a new use-case or query language is needed a new acronym/company pops up, For example: supporting a different database (i.e graph instead of relational or the other way around).
- Data Silos: As those solutions support different APIs, different databases and different query languages it is not possible to take advantage of the data as a whole and ask questions across data located in different solutions.
CloudQuery open-source
The main issue is that we have an infinite amount of APIs. If we look at other verticals such as IaC (Infrastructure as Code -Terraform, Pulumi, CloudFormation) we can see that all of them are open-source, and for a good reason:
- Community: Users can add their own resources and/or integrations without being blocked by a vendor.
The second issue we saw that caused the market fragmentation: co-locating the ETL engine with the database and processing layer.
Different solutions might need different queries or even different databases. Moreover, the number of use-cases and questions you want to ask and enforce is infinite, so the user must have raw access to the database.
Given these insights, we scribbled the following:
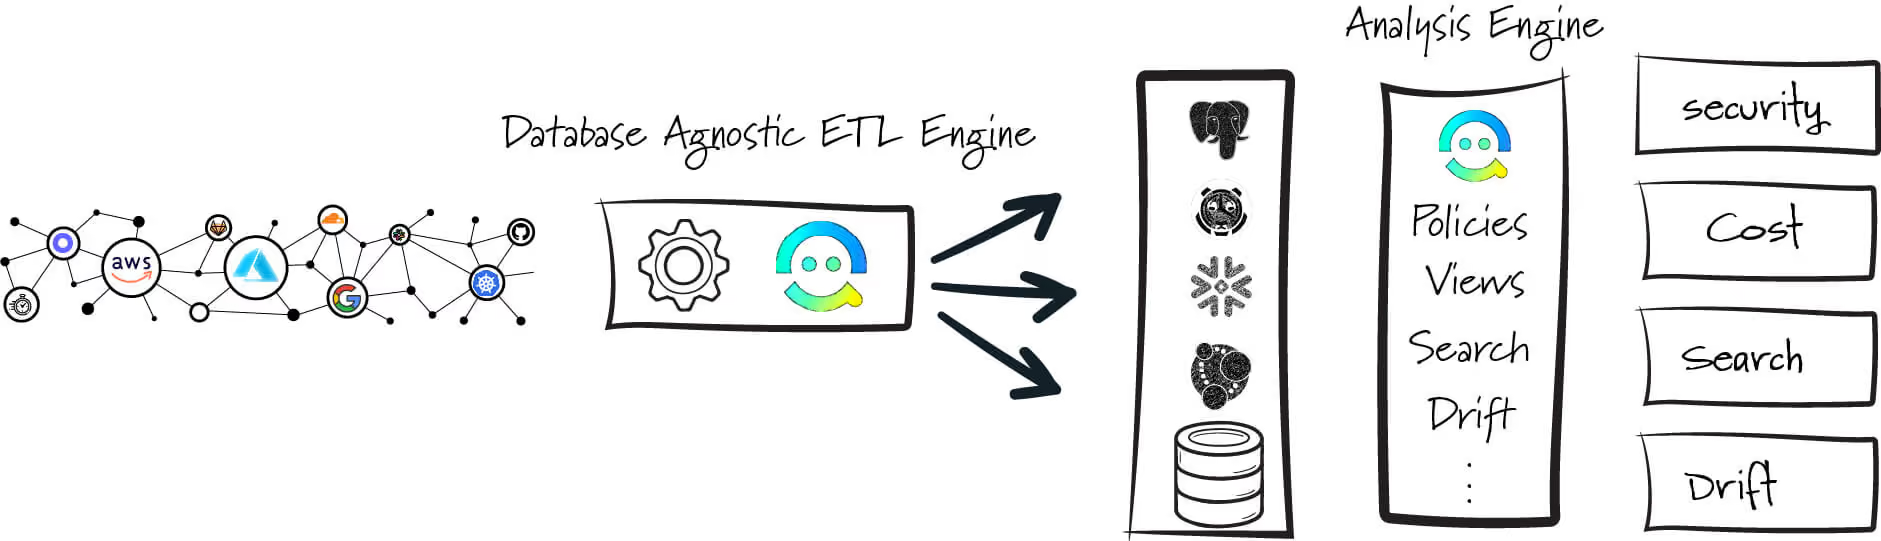
You can observe the following components:
- ETL Engine: The first thing we were out to do at CloudQuery is to consolidate and build one open-source engine with multi-database support.
- CloudQuery SDK: To make life easier for us and for the community we created an SDK that simplifies the development and testing of new integrations. The SDK gives developers the ability to focus only on the E (Extract) while taking care of the TL (Transform and Load) and giving the option for multi-database support.
- Decoupling ETL & Analysis Engine: This was solved by having the data/configuration in the database and giving users raw access to the database. The analysis engine is implemented using standard, well known, and documented query languages.
Replacing acronyms with use-cases: Instead of adding more acronyms we just want to focus on the end use-cases:
- Security & Compliance Policies: We introduced CloudQuery Policies which is just a thin layer that gives users the ability to run a pack of SQL queries.
- Search & Visibility: Standard SQL gives you visibility across accounts and clouds.
- Cost: This is something we didn’t actively touch yet, but are looking for feedback and suggestions.
- History: Being able to look back in time and investigate is useful for a variety of use-cases such as post-mortems, incident-response, and compliance. This is why we introduced CloudQuery history with TimescaleDB
- Other: There are probably many more use-cases, and there is no need to invent new acronyms for them - it can just be a matter of adding a novel query or a new integration. We’re looking forward to seeing what you can do with CloudQuery data - feel free to hop on our community and join our monthly community hours.
- Yet another dashboard disease: Companies have invested a lot of effort in having their own monitoring and visualization solutions. By giving raw access to the database you can take advantage of your current tools - Grafana, Preset, etc…
Future
We are really excited about the future of cloud management and we think it’s open-source, customizable, and community first.
P.S - we are hiring, join us to build an open-source future.
Want to see CloudQuery in action? Schedule a demo with our team or check out the platform documentation to learn more.
Want help getting started? Join the CloudQuery community to connect with other users and experts, or message our team directly here if you have any questions.
Written by
Try CloudQuery yourself
Self-hosted, open source, and free to start. Or schedule a demo to see the managed version.